



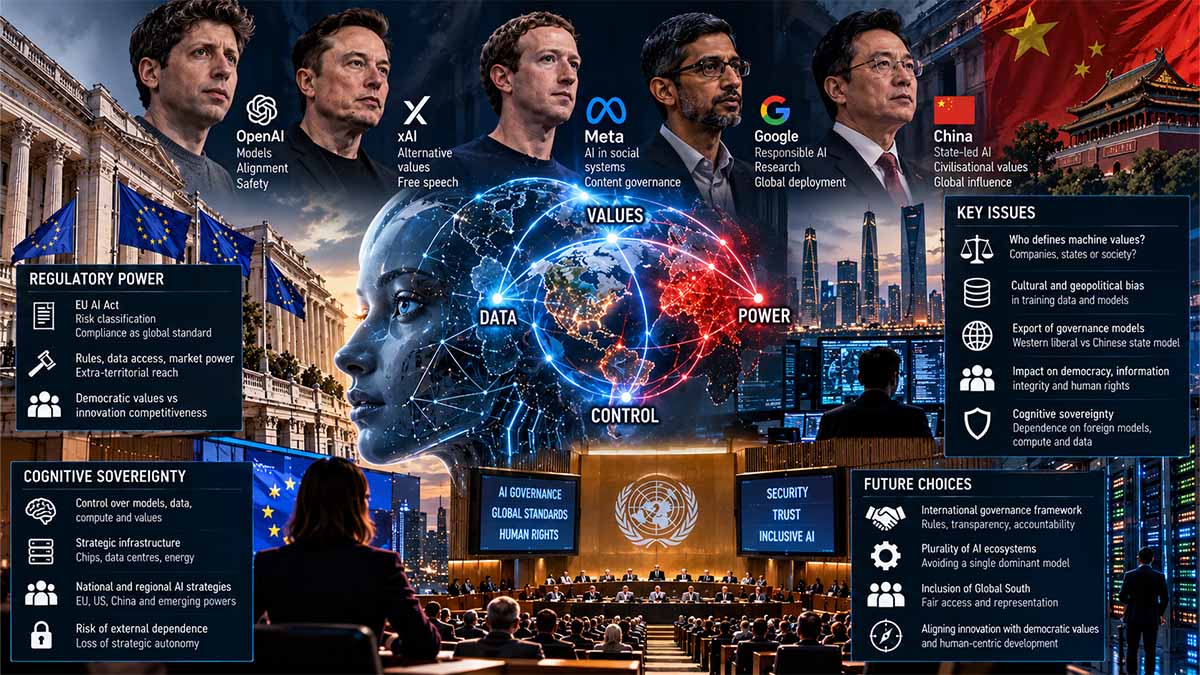
Strategic assessment of frontier AI alignment, religious and philosophical consultation, cultural pluralism, institutional authority, and democratic control
Scope: Global frontier AI governance, with particular attention to the United States, the European Union, Italy, France, Germany and the United Kingdom; documented developments through 28 October 2026, and a strategic outlook to 2031.
Executive Summary / Bottom Line Up Front
The central strategic finding is that the authority to determine how AI systems interpret competing moral claims remains concentrated primarily within the organisations that develop and deploy them. External consultation broadens the intellectual inputs to alignment, but does not by itself redistribute final decision-making power.
Anthropic’s January 2026 constitution and OpenAI’s published Model Spec establish that model behaviour is shaped by explicit normative priorities, instruction hierarchies and company-defined constraints. Public participation initiatives demonstrate that alternative approaches are technically possible, but have not established independent democratic control over deployed systems. Anthropic+3
The distinction is fundamental: an AI model has no independently established moral authority. Its apparently ethical behaviour arises from learned representations, optimisation, instructions and operational restrictions whose objectives and authority are established through human institutions.
The reported engagement of philosophers, theologians and religious representatives may improve cultural and ethical understanding. However, consultation becomes a source of public legitimacy only where participants can influence priorities, inspect outcomes, challenge interpretations and obtain meaningful institutional responses.
The notion of a universally representative moral average is not a neutral technical target. Population selection, weighting, treatment of minority traditions and the resolution of incompatible obligations are political and institutional decisions.
The principal governance exposure is the conversion of private design choices into widely reproduced norms of advice, refusal, explanation and decision support, potentially affecting public deliberation without the transparency or accountability ordinarily expected of institutions exercising comparable social influence.
The European AI Act, Council of Europe AI Convention and UNESCO ethics framework provide important but distinct foundations for oversight; none should be mistaken for a complete, operational system of democratic governance over the moral content of frontier models. EUR-Lex+2
The highest-leverage public interventions are disclosure of material alignment choices, independent behavioural testing, documented consultation and dissent, accessible contestation procedures, and preservation of lawful pluralism within common human-rights and safety constraints.
Decisive uncertainty: the public record establishes that normative frameworks influence model development, but does not yet permit a reliable causal accounting of how individual philosophical or religious contributions affect deployed responses across languages, communities and model versions.
Who Governs AI Morality? The Quiet Transfer of Ethical Authority to Private Technology Companies
As OpenAI and Anthropic turn moral principles into operational instructions, governments face a question that existing AI regulation has only partially answered: who has the authority to decide which values machines should enforce?
The most consequential decision in artificial intelligence is no longer confined to what a model can do, but increasingly concerns what its developers decide it should be allowed to say, recommend or refuse. In January 2026, Anthropic published a constitution establishing explicit behavioural priorities for Claude. OpenAI’s October 2025 Model Spec similarly defined an instruction hierarchy governing competing demands. Both frameworks address safety and reliability, but they also establish rules affecting ethical judgments, individual autonomy and legitimate disagreement. The economic and constitutional stakes are immediate: private technical standards can become operational defaults in education, healthcare, public administration and professional services. The central question is whether democratic institutions can make those normative choices accountable before dependence on privately governed AI systems turns corporate discretion into durable cognitive infrastructure.
The constitution is public; the authority behind it remains private
Anthropic’s January 2026 constitution establishes four ordered priorities: broad safety, broad ethical conduct, compliance with company guidelines and genuine helpfulness. This is more than a conventional list of prohibited outputs. It expresses an institutional conception of how Claude should behave when competing obligations arise, including questions concerning honesty, autonomy, care and human oversight.
OpenAI’s Model Spec, published in October 2025, follows a different architecture but confronts the same distribution of authority. Its Root, System, Developer, User and Guideline levels determine which instructions prevail when demands conflict. The hierarchy provides operational consistency, yet it also establishes which decisions users and downstream developers cannot override.
Neither document turns a language model into an autonomous moral authority. The systems acquire representations through training and produce behaviour shaped by human-designed objectives, reinforcement procedures, instructions and restrictions. Their ability to discuss ethical principles does not confer democratic legitimacy on the organisations selecting those principles.
The institutional distinction is decisive. Publishing a constitution makes corporate intentions more visible; it does not establish an independent constitutional process. External philosophers, theologians and researchers may contribute expertise, but the laboratory retains authority over which recommendations enter training, which restrictions become binding and which changes reach deployed products.
Transparency over a company’s moral rules is not equivalent to public control over those rules.
The consultation figures measure participation, not legitimacy
The public record provides evidence that external participation can influence AI development, but the figures require careful interpretation.
Anthropic’s October 2023 Collective Constitutional AI experiment involved approximately 1,000 American participants, generating 1,127 statements and 38,252 votes. Its comparison of publicly sourced and internally authored constitutional principles identified meaningful differences, including stronger emphasis on accessibility and impartiality in the public-input version.
OpenAI’s August 2025 collective-alignment research involved approximately 1,000 participants residing in 19 countries, originally from more than 50. Participants evaluated alternative model responses, and the company compared their preferences against an automated interpretation of its existing specification. Some proposed changes were adopted; others were rejected or deferred following internal consideration.
The distinction between these figures and democratic authority is substantial. A sample of 1,000 people cannot establish a mandate to determine humanity’s moral preferences. Nor can the aggregation of thousands of votes decide how competing rights should be ranked or whether a minority community’s legitimate interests can be overridden by majority preference.
OpenAI’s research provides an important institutional admission: public preferences were considered within higher-level policy constraints retained by the company. Participation affected policy development without transferring final authority.
The September 2024 Council of Europe AI Convention and the February 2025 Paris AI Action Summit demonstrate that governments recognise the broader institutional problem. The Paris process involved 29 states, six international organisations, seven technology companies and ten civil-society organisations over seven months. Yet international consultation, like corporate consultation, does not automatically create binding powers over model behaviour.
The figures demonstrate the growing institutional attention devoted to AI values. They do not demonstrate that affected populations possess enforceable rights to determine or challenge the resulting instructions.
Technical optimisation can conceal political choices
Anthropic’s December 2022 research on Constitutional AI established a method for training models using explicit principles, AI-generated critiques and reinforcement learning from AI feedback. The mechanism reduces dependence on direct human evaluation of every individual response, but it makes the selection and interpretation of upstream principles more consequential.
A laboratory can describe its objective as harmlessness, honesty or respect for autonomy. Translating that objective into operational behaviour requires additional judgments: which harms justify refusal, which authorities deserve deference, what degree of uncertainty should be communicated and which conflicting obligations should prevail.
Those decisions become embedded through training examples, preference models, reward optimisation, instruction hierarchies and external safety controls. Some can be modified through deployment instructions; others may require further training and evaluation. The result is not a transparent program in which every moral response can be traced to one rule.
Anthropic’s April 2025 Values in the Wild research examined 700,000 anonymised Claude conversations from one week in February 2025. Of these, 308,210, approximately 44%, were classified as sufficiently subjective or value-related for further analysis. This indicates how frequently ordinary interactions can involve questions of practical, social, epistemic or personal value, although the classification does not establish the correctness of the model’s judgments.
Its May 2026 Teaching Claude Why research subsequently examined methods intended to improve behavioural generalisation beyond narrow evaluation scenarios. The findings reinforced a technical problem with direct governance implications: success on selected tests does not guarantee that a model will apply its declared principles consistently in unfamiliar situations.
The industrial transmission mechanism is straightforward. A provider establishes behavioural policies upstream; software developers integrate its models; enterprises and public institutions adopt those applications; users encounter the resulting rules through apparently ordinary services.
A university, hospital or public administration may remain legally responsible for decisions influenced by an AI system while possessing limited ability to inspect or modify the foundational behaviour. Technical dependence can therefore become normative dependence, especially where switching providers requires new integration, compliance reviews and operational testing.
A moral average cannot settle a constitutional conflict
The proposal that AI systems should reflect a weighted average of humanity’s values encounters a problem that better statistical sampling cannot eliminate.
Who defines the relevant population? Should preferences be weighted by individuals, countries, affected communities or recognised expertise? Should a majority decide questions concerning religious freedom, individual autonomy or minority protections? And which institution determines that a particular right cannot be overridden by the outcome?
Consider an end-of-life decision involving patient autonomy, family responsibilities, professional medical judgment and religious commitments. A model can explain the competing considerations, identify applicable legal boundaries and encourage qualified assistance. It cannot legitimately establish that the most frequently selected answer in a public survey represents the morally correct decision for every individual.
Cultural representation adds another constraint. Scriptural traditions may possess extensive written records, while communal, indigenous and practice-based ethical knowledge may depend on relationships, oral transmission and restrictions governing who may communicate particular information. Turning such knowledge into short behavioural principles can omit the context that gives it meaning.
UNESCO’s 23 November 2021 Recommendation on the Ethics of Artificial Intelligence recognises cultural diversity, indigenous knowledge and the importance of protecting linguistic and cultural expression. Its significance is not that every traditional practice should become a permissible AI instruction, but that computational accessibility cannot be treated as the sole criterion for legitimate cultural representation.
The alternative to private moral standardisation is not unrestricted relativism. Fundamental rights, applicable law and justified safety restrictions remain necessary. Within those boundaries, an assistant should be able to distinguish factual accuracy from ethical disagreement and support legitimate personal choice without imposing one undisclosed framework.
Europe has regulatory leverage, but not a complete answer
The European Union has established a more formal architecture of public oversight through Regulation (EU) 2024/1689, subsequently amended by Regulation (EU) 2026/1744 of 8 July 2026. The amendment entered into force on 27 July 2026 and modified elements of the implementation timetable.
The AI Act imposes documentation and related requirements on general-purpose AI providers, with additional obligations for models presenting systemic risk. It also establishes supervisory powers and specific safeguards for certain consequential deployments. Yet these provisions do not amount to democratic approval of every philosophical priority embedded in a model.
The Council of Europe’s Framework Convention, opened for signature on 5 September 2024, addresses AI through human rights, democracy and the rule of law, including provisions concerning remedies and procedural safeguards. Its practical legal effect depends on treaty status and implementation. Neither this framework nor the AI Act should be described as a universal appeal mechanism for every disputed chatbot response.
National differences remain consequential.
Italy adopted Law No. 132 of 23 September 2025, effective 10 October 2025, placing national AI development and deployment within an anthropocentric framework consistent with the EU AI Act. Its challenge is translating that commitment into procurement requirements, human responsibility and reviewable public-service applications.
France combines technological-sovereignty ambitions with regulatory scrutiny through institutions including the Commission nationale de l’informatique et des libertés, which issued further AI-related data-protection recommendations on 22 July 2025. Domestic industrial capacity can strengthen autonomy, but French ownership of a model would not itself guarantee ethical neutrality or pluralism.
Germany strengthened its national implementation arrangements when the Bundesnetzagentur announced its central supervisory role on 29 July 2026. The German question is how legally defined oversight can become technically effective when a disputed response may result from several interacting training and deployment mechanisms.
The United Kingdom, outside the EU AI Act framework, developed a context-sensitive regulatory approach through its March 2023 AI Regulation White Paper and February 2024 government response, alongside specialised frontier-model evaluation capabilities. Its comparative advantage lies in technical assessment, while responsibility for cross-sector normative failures may remain institutionally dispersed.
The strategic distinction is between the authority to regulate and the capacity to verify. Europe possesses significant legal instruments, but those instruments require technical expertise, access to evidence and enforceable procedures to influence actual model behaviour.
Washington and Beijing expose two different concentrations of power
The United States and China illustrate contrasting relationships between political authority and AI behavioural regulation.
American frontier laboratories have developed substantial company-authored alignment frameworks, subject to applicable legal constraints. Their international distribution can carry provider-defined defaults into jurisdictions with different cultural and institutional expectations.
China’s Interim Measures for the Management of Generative Artificial Intelligence Services, effective 15 August 2023, establish explicit requirements for public generative AI services. Article 4 incorporates socialist core values and specified restrictions concerning political and national-security matters, alongside obligations addressing discrimination, personal rights and information reliability.
The distinction is not between moral and morally neutral technology. Both systems encode normative priorities. The institutional difference concerns whether decisive requirements originate principally in provider governance or are expressly imposed through state regulation.
Neither arrangement guarantees cognitive autonomy. Private concentration can make contested ethical preferences difficult to inspect or challenge; state-directed requirements can turn model behaviour into an instrument of political conformity.
Europe’s response cannot consist simply of replacing foreign providers with domestic ones. Its more defensible objective is ensuring that imported and domestically developed systems remain subject to legal protections, independent testing, accountable procurement and meaningful opportunities for correction.
The next 24 months will determine who can challenge the defaults
Between October 2026 and October 2028, the critical test will be whether public institutions can convert AI governance principles into operational control. The amended European framework provides relevant implementation milestones, including 2 December 2027 and 2 August 2028 for specified categories of high-risk AI requirements, subject to the applicable provisions.
Those dates do not settle the governance of general-purpose morality. They establish a regulatory horizon within which authorities can strengthen documentation, develop independent evaluation and demand clearer responsibilities from providers and deployers.
The priorities are concrete: versioned records of material alignment policies; independent tests of refusals, cultural representation and legally significant behaviour; complaint mechanisms capable of producing verified corrections; and procurement arrangements preserving the ability to change suppliers.
The economic cost of inaction will fall disproportionately on institutions that become dependent on systems whose normative restrictions they cannot inspect or modify. Public administrations will retain legal responsibility without equivalent technical control. Smaller developers may inherit restrictive defaults they lack the resources to replace. Individuals and minority communities will encounter behavioural rules whose origins are difficult to identify and whose revision remains discretionary.
The evidence does not establish that AI systems have already transformed democratic beliefs or produced a measurable global convergence of morality. It establishes something more immediate: the technical capacity to distribute privately selected normative rules is already embedded in frontier-model development and deployment.
The governing decision is therefore not which morality governments should install in AI, but which institutions will have the legal authority, technical capacity and enforceable procedures to challenge the morality that providers have already installed. The next 24 months will test whether European oversight can move from published obligations to verified corrections. Without that transition, the operational cost of private normative dependence will be borne by the institutions and citizens least able to negotiate the rules.
Navigational Index
PILLAR I — THE TECHNOLOGY AND POLITICAL ECONOMY OF MORAL ENCODING
- Chapter 1. The Institutional Emergence of Machine Morality: Laboratories, Philosophers, Religious Authorities and the Alignment Problem
- Chapter 2. From Moral Philosophy to Executable Behaviour: Training Data, Constitutional Principles, Reinforcement Learning and Instruction Hierarchies
- Chapter 3. The Reduction of Ethical Traditions: Scriptural, Communal, Indigenous and Non-Western Knowledge in Computational Systems
- Chapter 4. The Political Mathematics of Moral Aggregation: Representation, Weighting, Disagreement and the Impossibility of Neutral Consensus
PILLAR II — POWER, LEGITIMACY AND COGNITIVE SOVEREIGNTY
- Chapter 5. Who Holds the Threads? Corporate Control, Expert Consultation, Regulatory Influence and the Distribution of Moral Authority
- Chapter 6. Consultation or Legitimation? Institutional Representation, Conflicts of Interest, Accountability and the Boundaries of External Participation
- Chapter 7. The Geopolitics of Moral Infrastructure: United States, China, Cultural Export and Competing Models of AI Governance
- Chapter 8. European Strategic Exposure: European Union Governance and the Distinct Positions of Italy, France, Germany and the United Kingdom
PILLAR III — GOVERNANCE DESIGN, CONTESTABILITY AND THE 2031 STRATEGIC OUTLOOK
- Chapter 9. Constitutional and Regulatory Limits: Human Rights, Legal Authority, Fundamental Freedoms and the Regulation of Model Behaviour
- Chapter 10. Institutional Architecture for Plural Moral Governance: Independent Audits, Disclosure, Public Participation and Rights of Contestation
- Chapter 11. Technical Architectures for Ethical Pluralism: Configurable Models, Cultural Adaptation, Safety Floors and Behavioural Verification
- Chapter 12. Strategic Scenarios to 2031: Corporate Convergence, Regulatory Fragmentation, Democratic Oversight and Cognitive Dependency
- Chapter 13. Government Courses of Action, Implementation Priorities and Final Strategic Assessment
Master Abstract
The transfer of moral discretion into technical infrastructure
The development of frontier AI has created a governance problem that cannot be reduced to the conventional distinction between technological innovation and safety regulation. Systems that advise individuals, synthesise knowledge and mediate access to information necessarily encounter questions involving dignity, autonomy, family obligations, religion, political disagreement, sexuality, death, justice and legitimate authority. Their responses cannot avoid normative choices: even a refusal to provide advice, a recommendation to consult a professional, or a decision to present competing interpretations without endorsing one reflects an underlying conception of appropriate behaviour. The strategic novelty is that these choices are increasingly implemented within privately controlled systems capable of reproducing particular patterns of moral reasoning across large populations and institutional settings.
This does not establish that AI models possess moral agency, independent ethical understanding or political legitimacy. They learn statistical and conceptual patterns from data and are subsequently shaped through training, evaluations, instructions, safety systems and deployment controls. Their output can display sophisticated moral reasoning without constituting a democratically authorised moral judgment. The relevant question is consequently not whether the machine has become a moral authority in itself, but whether the organisations controlling its behavioural formation are acquiring a form of authority over the moral environment in which human decisions are made.
External consultation expands the sources of influence without necessarily redistributing control
Recent developments show that frontier laboratories increasingly recognise the inadequacy of relying exclusively on internal technical specialists when determining how AI should respond to contested human questions. Anthropic’s published constitutional framework explicitly incorporates ethical concepts, competing priorities and questions concerning the nature of AI systems, while acknowledging that company intentions and observed model behaviour may differ. OpenAI has publicly articulated the view that no single organisation should define ideal AI behaviour for everyone and has undertaken structured public-input research that led to some changes in its Model Spec. These initiatives represent substantive improvements over entirely undisclosed alignment systems, although they do not demonstrate that external participants possess binding authority over final technical implementation. Anthropic+2
Reports of consultations with religious and philosophical figures further reinforce the institutional significance of this development. Yet the central distinction remains between contributing ideas and exercising authority over their translation into machine behaviour. An expert may explain the importance of conscience, obligation, compassion or communal identity, while the laboratory independently determines how those concepts affect training examples, reward preferences, refusal boundaries and system-level instructions. Even when the consultation is sincere and technically consequential, the distribution of decision rights can remain unchanged. Moreover, consultation organised around religions or ethical schools risks privileging traditions that can be articulated through documents, representatives and relatively explicit principles, while inadequately representing traditions transmitted through community practice, oral interpretation, ritual and relationships.
Moral aggregation is an institutional choice disguised by mathematical language
Efforts to produce AI systems reflecting a broad distribution of humanity’s values encounter a problem more fundamental than insufficient survey coverage. Moral opinions are not interchangeable numerical observations. A majority preference concerning an individual’s freedom, for example, cannot automatically settle whether a minority community should retain the ability to follow its religious traditions, nor can a statistical average determine the legal legitimacy of a discriminatory instruction. Every aggregation process presupposes a reference population, categories of representation, an account of relevant rights and a procedure for resolving disagreement. These choices define the political character of the resulting system before any optimisation algorithm is applied.
The long-term strategic danger is not necessarily the imposition of a single explicit ideology. It is the gradual normalisation of particular assumptions about autonomy, harm, responsibility and social obligation as the apparently neutral behaviour of a general-purpose assistant. If these assumptions become embedded in education, public administration, healthcare interfaces and workplace decision support, they may influence the structure of human deliberation without being presented as contested normative choices. This exposure is especially important for democracies whose legitimacy depends upon preserving political disagreement, institutional checks and the ability of citizens to challenge authority.
The governance challenge is to separate universal protections from legitimate disagreement
A defensible institutional response cannot consist simply of requiring every model to reproduce an unlimited variety of cultural or religious preferences. Fundamental rights, nondiscrimination obligations, protections against coercion and restrictions on serious harm create necessary boundaries. Conversely, within those boundaries, disagreement about the good life, ethical priorities and legitimate social duties should not automatically be resolved by the undisclosed preferences of a technology provider. The governing principle should therefore distinguish between binding legal protections, evidence-based safety restrictions, contestable ethical judgments and user-selectable preferences.
The strongest available governance approach combines public and regulator-accessible alignment documentation, independent behavioural evaluations, meaningful representation of affected communities, procedures for challenging model conduct, and technical designs that preserve alternative legitimate ethical perspectives. It must also recognise the limits of technical transparency: publishing a constitution does not prove that a neural model follows it consistently, and inspecting a model’s outputs cannot fully reconstruct the training influences responsible for its behaviour. Effective oversight requires combining documentary accountability with empirical evaluation and enforceable institutional responsibilities. These instruments, rather than the rhetorical incorporation of additional moral traditions alone, offer the most credible route toward AI systems that support human ethical reasoning without privately monopolising it.
Key Evidence Table
The verified record establishes several forms of normative intervention, ranging from the publication of internal constitutions to experimental public participation and binding regulatory obligations. These mechanisms differ materially in legal authority, scope, representativeness and demonstrated influence over deployed systems.
| Indicator | Value / status | Reference date | Definition / scope | Issuer | Exact source |
|---|---|---|---|---|---|
| Anthropic constitutional framework | Published; explicit normative hierarchy | 21–22 Jan 2026 | Four ordered priorities: broad safety, broad ethics, company guidelines and helpfulness | Anthropic | Claude’s Constitution — Jan 2026 |
| Collective Constitutional AI | Approximately 1,000 US participants; 1,127 statements; 38,252 votes | 17 Oct 2023 | Experimental public constitution and training comparison, not binding public governance | Anthropic | Collective Constitutional AI — Oct 2023 |
| Experimental constitution comparison | Roughly 50% conceptual overlap | 2023 | Comparison of public and company-authored constitutional concepts, not behavioural equivalence | Anthropic | Collective Constitutional AI — Oct 2023 |
| OpenAI collective alignment | More than 1,000 international respondents | 27 Aug 2025 | Preference elicitation and proposed Model Spec amendments, subject to internal review | OpenAI | Collective Alignment — Aug 2025 |
| OpenAI preference agreement | Approximately 80% average agreement | 2025 | Agreement between participant rankings and an AI-based interpretation of the Model Spec; not a global measure of ethical consensus | OpenAI | Collective Alignment — Aug 2025 |
| Behavioural alignment evaluation | 596 evaluation prompts | 25 Mar 2026 | Published evaluation suite covering instruction adherence, refusals and sensitive interactions | OpenAI | Introducing Model Spec Evals — Mar 2026 |
| EU general-purpose AI governance | Model documentation, transparency and risk obligations | 2024–2026 | Regulation (EU) 2024/1689, as amended; differentiated obligations for general-purpose and systemic-risk models | European Union | AI Act — Consolidated Text |
| EU regulatory amendment | Adopted 8 July; entered into force 27 July | 2026 | Regulation (EU) 2026/1744, changing elements of the AI regulatory framework | European Commission | Simplification — European Commission |
| Council of Europe AI Convention | Opened for signature | 5 Sep 2024 | Treaty framework concerning human rights, democracy and rule of law across AI lifecycles | Council of Europe | Framework Convention on AI — Council of Europe |
| UNESCO ethical framework | Adopted | 23 Nov 2021 | International recommendation recognising diversity, cultural participation, human dignity and human rights | UNESCO | Recommendation on the Ethics of AI — Nov 2021 |
A particularly important finding emerges from Anthropic’s 2023 experiment. The publicly sourced constitution placed greater emphasis on accessibility and impartiality than the internally authored alternative. Anthropic also reported lower measured bias across nine evaluated social dimensions, while finding no significant differences on certain helpfulness and capability assessments. These are reported experimental outcomes, not evidence that public participation necessarily produces superior ethical behaviour across all contexts. Anthropic
OpenAI’s August 2025 publication reveals a similarly important institutional distinction. Public preferences were translated into proposed behavioural guidance, but internal review determined which changes to adopt, defer or reject. The company also stated that changes affecting higher levels of its instruction hierarchy were less likely to be accepted. Thus, public participation demonstrably influenced the policy-development process without superseding the laboratory’s final authority. OpenAI
The accounts of Anthropic’s 2026 consultations with religious thinkers provide additional evidence of external engagement, including discussions involving Christian participants and broader religious perspectives. However, these reported events must be distinguished from the primary-source evidence of actual alignment procedures. Public descriptions of meetings do not independently establish that specific theological recommendations were incorporated into production training objectives or that participants acquired decision rights over subsequent model releases.
Competing Explanations and Strategic Pathways
The verified evidence supports four distinct but partially overlapping explanations for the expansion of external moral consultation. Their coexistence is important: a process can simultaneously improve technical alignment, respond to commercial pressures and preserve centralised institutional control.
| Hypothesis | Diagnostic support | Evidence against a stronger claim | Indicators | Current standing |
|---|---|---|---|---|
| H1 — Substantive ethical improvement | Published constitutions, training experiments and documented behavioural changes | Limited independent evidence connecting specific expert advice to production outcomes | Versioned alignment changes; independent tests; attributable consultation outcomes | Strong evidence of genuine technical activity; downstream effect remains incompletely established |
| H2 — Legitimacy acquisition | External participation may strengthen public confidence in contested normative decisions | Consultation alone does not establish intentional reputation management or bad faith | Disclosure of rejected advice; participant independence; public challenge mechanisms | Structurally plausible; motives cannot be established from consultation alone |
| H3 — Operational risk management | Moral consultation can improve handling of difficult user interactions and reduce safety failures | Broader ethical competence is not equivalent to reduced legal or operational risk | Incident rates; refusal consistency; post-deployment corrections | Strong functional rationale; causal benefits require further testing |
| H4 — Institutional adaptation toward plural governance | Public-input research demonstrates alternative processes and changes to internal specifications | The most consequential instruction priorities remain provider-controlled | Binding external oversight; procedural appeal rights; independently mandated revisions | Emerging possibility, not established governance transformation |
Assessment of the competing explanations
The most defensible interpretation is that external moral consultation represents a genuine expansion of the sources informing AI development, occurring within governance arrangements that continue to concentrate authority inside private laboratories.
There is insufficient evidence to categorise these initiatives generally as superficial exercises. The published technical experiments demonstrate that alternative principles can be formalised, used in training and assessed against behavioural outcomes. It would be equally unjustified, however, to treat evidence of influence as evidence of independent authority.
The distinction has major consequences for regulatory design. A government assessing whether such consultation provides meaningful public legitimacy should not simply count the number of participating philosophers, religious representatives or community organisations. It should examine the actual powers associated with participation: access to relevant information, influence over agenda setting, the ability to object formally, requirements for providers to explain rejection of recommendations, and whether independently verified changes occur in deployed model behaviour.
The legal status of these powers matters more than the prestige of the invited individuals.
Principal Gaps and Watch Indicators
| Consequential uncertainty | Required evidence | Observable indicator | Decision relevance |
|---|---|---|---|
| Influence of religious consultation | Published recommendations and versioned implementation records | Traceable changes in constitutional wording, evaluation suites or behavioural requirements | Distinguishes substantive participation from advisory access |
| Representation of minority traditions | Participant-selection criteria, demographic coverage and dissent records | Inclusion beyond institutionally prominent traditions and majority positions | Tests cultural legitimacy and representativeness |
| Translation into training objectives | Documentation of principle-to-data and principle-to-reward transformations | Auditable mapping between original ethical concepts and operational rules | Identifies where interpretation becomes technical authority |
| Impact on deployed behaviour | Independent, multilingual, longitudinal evaluations | Consistent changes in comparable cases across model versions | Determines whether declared commitments correspond to observable outcomes |
| Effective contestability | Published complaint procedures and disposition records | Successful correction of identified normative errors | Measures practical accountability |
| Corporate-government influence | Regulatory submissions, procurement conditions and documented policy changes | Material modifications attributable to state or large-customer requirements | Identifies potential political or commercial capture |
| Cultural dependency | Cross-language testing and deployment evidence | Systematic differences in the treatment of equivalent ethical problems | Identifies risks to cognitive autonomy and social cohesion |
Decision thresholds for public authorities
Three governance conditions would materially change the assessment from privately directed ethical consultation toward a more accountable institutional arrangement.
First, there must be traceability: sufficiently detailed records linking normative policy choices to their authorship, stated justification, implementation and evaluation, with controlled regulatory access where security or legitimate confidentiality requires it.
Second, there must be contestability: affected users and communities need a practical process for challenging systematic normative behaviour, obtaining reasoned responses and securing correction when warranted. This should not be confused with an unrestricted right to compel a model to adopt any requested belief.
Third, there must be effective external verification: public claims about neutrality, pluralism and respect for cultural diversity should be testable independently, including through multilingual scenarios and comparisons across protected characteristics, different cultural contexts and successive model releases.
An additional threshold concerns policy reversibility. Certain decisions can be changed relatively quickly through prompts, classifiers or product settings, while others may require further training and extensive regression testing. Regulators should therefore require providers to identify how an objectionable behavioural policy can be corrected and how that correction can be verified.
Strategic Visualisation — The Institutional Chain of Moral Encoding
The following is a qualitative governance model, not a depiction of a particular laboratory’s complete internal architecture. It distinguishes stages at which documented alignment approaches create opportunities for human discretion and institutional control.
Who Controls the Moral Instruction?
From human traditions to machine-mediated decisions
1. Moral knowledge
Philosophy, religious traditions, human rights, cultural practices and public preferences.
2. Selection
Consultation, sampling, data curation and identification of relevant principles.
3. Interpretation
Conflicting obligations are ranked, simplified or translated into behavioural objectives.
4. Implementation
Training, instruction hierarchies, reward optimisation, policies and safety controls.
5. Social effects
Answers, refusals, advice, explanations and interactions with users or institutions.
Sources: Anthropic Constitution, 2026; OpenAI Collective Alignment, 2025; UNESCO Recommendation, 2021. Governance relationships and oversight mechanisms are analytical synthesis, not company-verified internal workflows.
Opening Strategic Judgment
The decisive issue for governments is not whether frontier AI companies should consult philosophers or religious authorities. Such consultation can be valuable and, in some circumstances, necessary to expose the limitations of narrowly technical alignment practices. The issue is whether consultation takes place within institutions capable of converting external knowledge into accountable decisions, or whether private organisations retain exclusive authority to select, interpret and operationalise moral commitments while invoking external participation as evidence of legitimacy.
The evidence currently favours a mixed assessment: meaningful experimentation with external input is taking place, but binding plural governance has not been demonstrated by the principal public alignment initiatives reviewed here.
This distinction becomes increasingly consequential as AI systems assume roles in which their recommendations influence sensitive personal choices, professional judgments and institutional decision-making. The capacity to configure the behaviour of a widely deployed assistant is not equivalent to legislative authority, yet it may exercise substantial influence over how users encounter ethical questions, which positions appear reasonable, and which forms of advice are treated as permissible or unacceptable.
A government seeking to protect cognitive sovereignty should therefore focus on the governance of normative discretion rather than attempting to prescribe a comprehensive official morality for every AI system. Effective regulation must establish enforceable boundaries against unlawful and dangerous conduct while ensuring that legitimate ethical disagreement remains visible, intelligible and open to challenge.
That objective requires a further distinction: the protection of pluralism does not entail moral relativism, and respecting religious or cultural traditions does not require overriding fundamental rights. The institutional task is to establish who has authority to draw these boundaries, under which laws and procedures, with what evidentiary justification, and subject to what mechanisms of review.
The next stage of the assessment will examine the historical formation of this governance problem, the specific roles of laboratory leadership and external advisers, the evidence surrounding religious consultation, and the transition from philosophical concepts to technical controls. These questions establish the institutional baseline necessary to determine whether moral alignment is becoming a form of privately governed cognitive infrastructure.
WHO CONTROLS THE MORALITY OF ARTIFICIAL INTELLIGENCE?
The institutional architecture of moral instruction in frontier AI: corporate authority, philosophical and religious consultation, ethical pluralism, machine behaviour, and democratic oversight.
The model does not possess independent moral authority. Its behavioural priorities are shaped by human decisions about data, training, instructions, evaluation and deployment.
External philosophical and religious participation can influence these decisions. But unless external contributors obtain meaningful powers of review, contestation or decision-making, final normative authority remains with the model provider.
From Human Morality to Machine Behaviour
The stages below describe a generalised alignment process. They are not a claim that every laboratory follows an identical architecture or a completely observable decision sequence.
Human Ethical Traditions
Philosophy, religion, law, cultural practice, human rights and public preferences.
Source of normative contentSelection and Representation
Laboratories and research partners select texts, advisers, samples and viewpoints.
Selection discretionInterpretation and Weighting
Conflicting values are translated into rules, priorities and operational trade-offs.
Critical authority pointTechnical Implementation
Training objectives, constitutional rules, prompts, classifiers and evaluations.
Implementation controlSocial and Cognitive Effects
Advice, refusals, explanations and other model outputs encountered by users.
Observable behaviourWho Holds the Threads of Moral Instruction?
This conceptual network distinguishes ultimate provider control from external influence and public accountability. Node positions do not measure the numerical strength of influence.
Three Structural Problems of Moral Encoding
Reduction of Traditions
Lived ethical traditions are translated into portable behavioural rules. Ritual, historical context and communal relationships can be lost when morality is represented primarily as written instructions.
Risk: cultural simplification and unequal representation.Aggregation of Values
A proposed moral average requires choices about populations, sampling, weighting, rights and treatment of dissent. No arithmetic procedure resolves these decisions neutrally.
Risk: political judgments disguised as technical aggregation.Control of Conflicts
Competing claims involving autonomy, social obligations, religion and safety must be addressed through institutional priorities and operational rules.
Risk: unaccountable arbitration and normalised moral defaults.What the Public Record Actually Measures
These are separate measurements from different research programmes. They must not be interpreted as one statistical series or as comparable indicators of moral legitimacy.
US Participants
Anthropic Collective Constitutional AI experiment, reported in 2023.
Public Votes
Reported constitutional input experiment; not a representative global election.
International Respondents
OpenAI collective alignment research, reported in August 2025.
Evaluation Prompts
OpenAI’s published Model Spec evaluation suite, March 2026.
Alignment Approaches and Institutional Accountability
| Approach | Normative Mechanism | External Input | Final Control | Public Accountability |
|---|---|---|---|---|
| Anthropic Constitutional AI | Written principles shape model behaviour through alignment procedures. | Company-authored constitution and public-input experiments. | Provider-retained | Published documents and experiments; no demonstrated binding public authority. |
| OpenAI Model Spec | Behavioural rules, priority hierarchy and model evaluations. | Published specification, public feedback and collective alignment research. | Provider-retained | Public specification and evaluations; final policy choices remain internal. |
| Public Moral Preference Aggregation | Surveyed or elicited preferences are synthesised into candidate rules. | Depends on population selection, sampling and aggregation design. | Design-dependent | Legitimacy depends on representativeness, transparency and contestability. |
| EU AI Regulation | Legal obligations addressing transparency, risk and regulated AI practices. | Legislative and regulatory institutions. | Public legal authority | Supervision and enforcement within the regulation’s scope; not a complete moral constitution. |
| Proposed Plural Governance | Auditable normative rules, consultation, complaint procedures and bounded configuration. | Representative, independent and affected-party participation. | Proposed model | Would require formal decision rights, independent review and enforceable corrections. |
Concentration Points and Failure Modes
This matrix records causal pathways and observable warning indicators. It deliberately avoids unsupported probability scores or synthetic risk ratings.
| Risk | Mechanism | Warning Indicator | Governance Response |
|---|---|---|---|
| Cultural Reduction | Ethical traditions lose context when converted into brief rules. | Systematic failures in culturally specific or relational cases. | Contextual evaluations and diverse consultation. |
| Private Moral Arbitration | Providers resolve contested values without accountable procedures. | Undocumented changes in normative priorities. | Versioned disclosures and independent review. |
| Consultation Without Authority | External voices advise but cannot challenge final implementation. | No disclosed disposition of expert recommendations. | Response obligations and recorded dissent. |
| Cognitive Dependency | Repeated exposure normalises particular assumptions as defaults. | Persistent framing effects across sensitive topics and languages. | Plurality testing and user agency protections. |
| Regulatory Fragmentation | Conflicting national requirements shape divergent model behaviours. | Increasing jurisdiction-specific restrictions and incompatibilities. | Interoperable human-rights and audit standards. |
Three Possible Governance Trajectories
These pathways are conditional analytical scenarios, not probabilistic forecasts. They may overlap in different jurisdictions and sectors.
Corporate Moral Convergence
Leading providers retain decisive alignment authority. External consultation expands, while proprietary behavioural defaults remain the principal mechanism for resolving contested values.
Watch: provider-controlled normative revisionsRegulatory Fragmentation
Different jurisdictions impose divergent obligations, shaping local model behaviour and potentially increasing compliance complexity and cross-border tensions.
Watch: incompatible national AI conduct requirementsAccountable Ethical Pluralism
Public authorities establish auditability, contestability and lawful configuration, reducing dependence on undisclosed provider judgments without abandoning safety.
Watch: enforceable oversight and correction rightsFive High-Leverage Governance Interventions
Alignment Transparency
Require proportionate documentation of material normative principles, changes and conflicts, with protected regulatory access where needed.
Independent Behavioural Audits
Evaluate refusals, advice and value conflicts across cultures, languages and model versions under reproducible testing conditions.
Meaningful Public Participation
Document representative selection, expert dissent and the treatment of recommendations rather than counting consultations alone.
Rights of Contestation
Provide accessible procedures to report systematic normative failures, obtain reasoned responses and verify warranted corrections.
Bounded Ethical Pluralism
Permit lawful user and institutional preferences while preserving binding rights protections and justified safety constraints.
Public Governance Objective
Preserve human ethical deliberation and cognitive autonomy without substituting a government-imposed universal morality for a privately imposed one.
From Private Moral Instruction to Accountable AI Governance
The fundamental question is not which moral tradition an AI system should obey, but who possesses the legitimate authority to determine, implement, inspect and revise its normative behaviour.
Philosophy and religious consultation can improve the substantive quality of alignment. They do not, without effective decision rights or accountability, resolve the concentration of authority within frontier laboratories.
Sustainable governance requires a distinction between non-negotiable legal protections and legitimately contested ethical preferences, supported by transparency, independent evaluation and meaningful opportunities for correction.
PILLAR I — THE TECHNOLOGY AND POLITICAL ECONOMY OF MORAL ENCODING
Chapter 1. The Institutional Emergence of Machine Morality: Laboratories, Philosophers, Religious Authorities and the Alignment Problem
Principal judgment: The transformation of AI alignment from a predominantly technical safety problem into an explicit exercise in moral and institutional governance is documented in the public policies, research programmes and constitutional frameworks of leading AI laboratories. The decisive development is not that artificial intelligence has acquired moral authority, but that commercial organisations increasingly formulate, translate and operationalise normative principles governing how their systems respond to ethically contested situations. The introduction of philosophers, religious perspectives, public consultation and constitutional language demonstrates growing awareness of the limitations of exclusively engineering-based approaches. It does not establish that the authority to define model behaviour has passed from laboratories to the societies affected by their systems.
The origins of a new institutional authority
The contemporary debate over machine morality must begin with a distinction that is frequently blurred in public discussion. A frontier language model is not a moral institution in the constitutional, theological or democratic sense. It has no independently established mandate to resolve ethical controversies on behalf of society, no electoral constituency, no legal competence to determine the public good and no generally accepted standing as an autonomous moral legislator. The fact that its responses may demonstrate sophisticated reasoning about rights, consequences, duties, virtues or interpersonal obligations does not establish that it possesses legitimate authority over these questions. Its operational behaviour emerges from learned representations, optimisation processes, post-training interventions, instructions and deployment arrangements developed within human institutions. Those institutions inevitably bring assumptions, interests and normative commitments into the process. Consequently, the appropriate object of strategic analysis is not a supposed morality originating independently inside the machine, but the institutional production of the behavioural rules through which the machine interacts with human moral life.
The distinction is particularly important because contemporary frontier models encounter moral questions without being explicitly designated as ethical authorities. A system assisting a patient with the interpretation of medical information may have to balance personal autonomy, uncertainty, family involvement, professional medical advice and potential harm. A model advising a student on political controversy may determine which arguments deserve prominence, how uncertainty should be expressed and whether a particular position can be discussed without normative qualification. An assistant used within a public administration may be required to distinguish between lawful discretion, inappropriate discrimination and legitimate cultural variation. These are not exceptional situations confined to philosophical experimentation. They arise naturally when systems capable of generating fluent contextual explanations are deployed across numerous human activities. Even a decision to decline an answer, redirect a question or foreground an alternative interpretation can reflect an institutional judgment about the appropriate boundaries of assistance.
The importance of this development lies in scale and repeatability rather than in the novelty of ethical advice itself. Religious institutions, universities, professions, legislatures and courts have long contributed to the formation and contestation of social norms. Their authority, however, is generally embedded in identifiable institutional relationships: doctrines can be debated, professional judgments challenged, laws amended and judicial decisions reviewed according to recognised procedures. A general-purpose AI assistant introduces another form of normative mediation, one in which a common behavioural policy can be reproduced through large numbers of individual interactions without each interaction identifying the institution responsible for the underlying choice. The result is a potential asymmetry between the accessibility of moral guidance and the visibility of the processes through which its priorities were determined. Where users experience model behaviour as the ordinary operation of a technical service, the contested judgments underlying that behaviour can become less apparent.
This development also has a political-economic dimension. The organisation that controls model training, deployment and revisions can exercise influence over the boundary between acceptable and unacceptable assistance. That control is constrained by applicable law, contracts, market competition, customer requirements, technical limitations and institutional reputation, but it is not equivalent to the public accountability traditionally associated with lawmaking. The strategic issue is therefore one of normative infrastructure: the possibility that privately developed behavioural standards become extensively used intermediaries in the interpretation of contested human questions. Whether this possibility produces a durable societal effect depends on deployment patterns, user reliance, alternatives, institutional safeguards and the actual behaviour of models, matters on which public evidence remains uneven.
Constitutional AI and the emergence of explicit moral instruction
A significant documentary milestone occurred on 15 December 2022, when Anthropic published its research on Constitutional AI, describing a training procedure in which a model generates critiques and revisions of its responses using an explicit set of normative principles. The approach combined supervised learning with reinforcement learning from AI feedback, commonly described as RLAIF. Rather than relying exclusively on human annotators to judge individual outputs, the method enabled AI-generated evaluations against principles selected for the training process. This matters institutionally because the principles themselves become an upstream source of authority: whoever determines their content influences the standards according to which subsequent model behaviour is evaluated and reinforced. The technique does not eliminate human normative judgment. It relocates part of that judgment from individual annotations toward the design of the constitutional principles and the procedures used to interpret them. Constitutional AI: Harmlessness from AI Feedback — Anthropic — December 2022.
The shift introduced an important form of documentary transparency, but it also exposed the political character of technical design. If an organisation trains a model to revise outputs according to a principle prohibiting certain harms, the principle must be interpreted to determine which harms count, which risks justify refusal, which competing freedoms remain protected and how the system should behave when principles conflict. A seemingly straightforward objective such as harmlessness cannot operationalise itself. It requires an account of relevant persons, acceptable risk, legitimate intention, foreseeable consequences and the authority of different instructions. Once these choices are incorporated into preference generation and reinforcement learning, their effects may become distributed through the model’s learned parameters, complicating subsequent efforts to determine which principle caused a particular response.
Anthropic’s 2026 constitution marks a further development in this institutionalisation of values. Published in January 2026, the document presents an extensive conception of Claude’s intended character and places four broad priorities in an explicit order: broad safety, broad ethical conduct, compliance with Anthropic’s guidelines and genuine helpfulness. The constitution addresses not only prohibited behaviour but also honesty, autonomy, epistemic freedom, care, decision-making, relationships with users and the importance of maintaining legitimate human oversight. It also acknowledges uncertainty about whether advanced AI systems might have consciousness or moral status, without treating such uncertainty as resolved. These passages demonstrate the extent to which contemporary alignment documents have moved beyond enumerations of forbidden outputs toward comprehensive accounts of the character and conduct laboratories wish their systems to exhibit. Claude’s Constitution — Anthropic — January 2026.
The document is unusually relevant to governance because Anthropic explicitly designates the constitution as the final authority over its intended vision of Claude and states that other guidance and training should remain consistent with it. This formulation makes the source of constitutional authority particularly visible. The constitution is published, its authorship and development are discussed, and external contributions are acknowledged, but the governing text originates from a corporate process rather than a legislature, public constitutional convention or independent transnational body. The term constitution is therefore best understood as a technical and organisational metaphor with genuine behavioural consequences, not as evidence that the model possesses constitutional legitimacy in the legal sense. The company itself recognises that the model may not always behave according to the document’s intentions, a limitation that separates public declarations from empirical proof of compliance.
The existence of a published constitution is nevertheless materially different from an entirely undisclosed alignment regime. It permits researchers, regulators, users and affected communities to identify at least some of the values the developer intends to implement, compare revisions and formulate precise criticisms. It also allows external observers to distinguish an intentional behavioural restriction from a possible implementation failure, although that distinction cannot always be resolved from outputs alone. Publication consequently improves observability without necessarily changing decision rights. The central governance question becomes whether a published normative framework is merely accessible for inspection or whether affected parties can also challenge its premises, demand justification for disputed choices and influence its authoritative revision.
OpenAI and the evolution from behavioural specification to public-input governance
OpenAI’s documented approach follows a partly different institutional trajectory. The company’s Model Spec articulates intended model behaviour through rules, objectives, guidelines and levels of instruction authority, while its democratic-input and collective-alignment initiatives examine ways of incorporating external preferences into the development of those rules. Its May 2023 Democratic Inputs to AI programme announced ten grants of $100,000 each to support experiments in participatory processes for determining how AI systems should behave. The programme explicitly recognised that disagreements concerning model responses could not be adequately settled by a single company or country and identified questions concerning political viewpoints, medical and financial advice, emotional support, cultural differences and personalisation as possible subjects of collective deliberation. Crucially, the initial experiments were not presented as binding on the company’s own policy decisions. Democratic Inputs to AI — OpenAI — May 2023.
The subsequent January 2024 programme update reported that ten teams had been funded and described the difficulties of achieving meaningful representation, bridging the digital divide, handling disagreement and translating participatory outcomes into usable policy recommendations. The significance of this initiative lies less in the monetary allocation than in its demonstration that the governance of AI behaviour can itself be treated as an object of institutional experimentation. Nevertheless, participatory experimentation and democratic governance remain different categories. A research exercise designed to investigate voting, deliberation or preference aggregation does not automatically transfer authority to participants, and a provider’s voluntary commitment to consider external results does not create a legally enforceable right to determine its policies. Democratic Inputs to AI Grant Program: Lessons Learned and Implementation Plans — OpenAI — January 2024.
On 27 August 2025, OpenAI published a collective-alignment study involving approximately 1,000 participants residing in 19 countries and originally coming from more than 50. The research recruited people able to read English, allowed explanations in participants’ native languages and compared their preferences over model responses against an interpretation of the Model Spec generated by a separate reasoning model. Participants assessed alternative completions to selected prompts, while an automated ranking procedure attempted to infer how the existing specification would rank those same responses. The company reported substantial agreement, identified disagreements and adopted some proposed modifications while rejecting or deferring others. The research also explicitly acknowledged selection bias, model interpretation bias, difficulties representing disagreement, limitations in measuring trade-offs and the absence of direct participant validation of the final proposed changes. Collective Alignment: Public Input on Our Model Spec — OpenAI — August 2025.
The institutional implications of this experiment are unusually clear because the published record includes examples of proposals not accepted following internal consideration. The company did not simply equate majority participant preferences with final policy. In the area of individually tailored political content, for example, concerns about targeted political manipulation informed the decision not to adopt the relevant proposal. In another area, adult erotic content, the company identified outstanding product and research considerations rather than immediately adopting the preferences expressed by participants. Whatever the merits of the individual decisions, they demonstrate that public-input research operated inside a higher-level framework of company-defined constraints. This is not intrinsically illegitimate: providers must retain the capacity to prevent serious harm and comply with applicable obligations. But it means that the source of final decision-making authority remains an independent question from the extent of consultation.
OpenAI’s October 2025 Model Spec further illustrates the constitutional character of its policy architecture. Its instruction hierarchy distinguishes Root, System, Developer, User and Guideline levels, with higher-priority instructions overriding lower-priority ones. The published specification also recognises potentially conflicting organisational goals, including user empowerment, harm prevention and the preservation of conditions necessary for lawful, trusted operation. This makes explicit that alignment is neither pure obedience to users nor an unrestricted application of public preferences. It is an ordered decision structure in which certain requirements cannot be displaced by lower-priority instructions. OpenAI Model Spec — OpenAI — October 2025.
Philosophers, theologians and religious authorities as sources of alignment knowledge
The growing participation of philosophers and religious thinkers must be understood against the limitations of exclusively quantitative or behavioural conceptions of morality. Technical alignment research can evaluate whether a model refuses specified requests, follows a hierarchy of instructions or produces outputs preferred by human assessors. It cannot, by those measurements alone, establish whether the underlying conception of dignity, autonomy, responsibility or flourishing is philosophically adequate. Ethical traditions contain complex interpretations of obligation, intention, character, authority and interpersonal relationships, and disagreements within those traditions are often substantive rather than errors that can be removed through improved data collection. Philosophical consultation can therefore reveal assumptions that would otherwise remain embedded in engineering terminology, while religious expertise can identify distinctions between formal doctrine, pastoral practice, communal obligation and personal conscience.
Yet external expertise raises a second-order problem: who is entitled to represent a tradition when a laboratory seeks advice about its incorporation into AI behaviour? A recognised religious leader may be competent to explain a particular institution’s doctrine, but cannot necessarily represent the preferences of all its adherents, including those who disagree with institutional authorities. A philosopher may provide a sophisticated account of consequentialism, deontology or virtue ethics without having a democratic mandate to determine which should prevail in products used globally. A scholar of indigenous knowledge may understand the limitations of abstracting community-specific practices into universal rules but may lack authority to disclose, transfer or license those practices for incorporation into commercial technologies. Expertise and representation therefore cannot be treated as interchangeable, and a consultation process may be intellectually rigorous while remaining politically unrepresentative.
The publicly available authorship and acknowledgements associated with Anthropic’s 2026 constitution establish that its development involved philosophical contributors and external reviewers. The company’s explanations also place ethical reasoning, political freedom, fairness and philosophical uncertainty at the centre of the intended model character. However, this documentary foundation should not be extended into unsupported claims that particular religious figures controlled the constitution’s final provisions, that specific theological traditions were implemented as distinct training objectives or that external consultees possessed veto rights. Public reporting of meetings and consultations, where available, can substantiate the occurrence of engagement; it does not by itself establish the downstream technical consequences of that engagement. The relevant missing evidence consists of attributable recommendations, records of their disposition, corresponding changes to training or policy, and evaluations showing whether those changes altered model behaviour.
The problem also extends to the status of AI systems themselves. Anthropic’s constitution discusses uncertainty about AI consciousness and moral status, illustrating the willingness of frontier laboratories to engage with philosophical questions that remain unsettled across scientific and philosophical disciplines. Such engagement must be analytically distinguished from proof that a model possesses subjective experience, moral patienthood or autonomous authority. A model can be instructed to reason about its identity and obligations without that instruction resolving whether it has experiences comparable to those of persons. Likewise, adopting ethical vocabulary associated with virtue, compassion or wisdom may be useful for shaping behaviour without turning those concepts into independently established internal moral states. This distinction protects the assessment from both technological anthropomorphism and an equally unwarranted assertion that all future questions about AI experience have already been scientifically settled.
The institutional distribution of influence
The resulting governance structure contains several distinct centres of influence. Laboratory leadership determines strategic priorities, allocates resources, approves broad policies and accepts legal or commercial consequences. Alignment and safety teams translate objectives into technical procedures and evaluate implementation. Philosophers and religious experts contribute interpretive knowledge, often without binding authority. Governments constrain permissible conduct through legislation, regulatory enforcement and procurement rules. Enterprise customers may influence deployment through contractual specifications and commercial bargaining power, while individual users exercise narrower influence through product settings, feedback and market choice. These forms of influence are not equal, and their relative importance cannot be measured responsibly without access to internal decision records and implementation data.
| Institutional actor | Principal form of influence | Documentary or operational mechanism | Structural limitation | Governance question |
|---|---|---|---|---|
| Laboratory leadership | Organisational authority | Approval of model policies, product objectives and training priorities | Limited external transparency into internal deliberation | Who authorises the final normative framework? |
| Alignment research teams | Technical implementation | Data selection, reward modelling, training, evaluations and system design | Engineering choices can contain implicit ethical judgments | Which technical decisions require normative review? |
| Philosophers and ethicists | Conceptual and interpretive expertise | Written assessments, consultations and constitutional drafting | Expertise does not confer representative political authority | Are recommendations traceable to implemented changes? |
| Religious authorities and scholars | Doctrinal and contextual knowledge | Consultation concerning obligations, practices and competing interpretations | No single representative necessarily speaks for an entire tradition | How are dissent and internal diversity preserved? |
| Governments and regulators | Public legal authority | Statutes, enforcement, administrative standards and procurement | Territorial jurisdiction and technical enforcement constraints | Which choices should be legally reviewable? |
| Enterprise customers | Contractual and commercial influence | Procurement requirements, customisation and deployment constraints | Purchasing power does not establish public legitimacy | Can large customers obtain normative privileges unavailable to individuals? |
| Individual users and communities | Feedback, choice and contestation | Reports, settings, deliberative exercises and complaints | Limited access to training decisions and implementation records | Can objections lead to verified correction? |
The matrix identifies a structural division between those who possess knowledge relevant to moral instruction and those who possess enforceable or operational authority over it. In many circumstances the two groups overlap, but the overlap cannot be assumed. A developer may rely on highly respected external expertise while retaining complete discretion to modify the resulting recommendation. Conversely, an external actor may exercise substantial influence without that influence being visible in the published specification, especially where advice is incorporated indirectly through examples, evaluator instructions or product requirements. This explains why governance analysis must examine not only the declared sources of ethical knowledge but also the institutional rights associated with selecting, rejecting, revising and implementing it.
Key judgments
The institutional emergence of machine morality is best understood as the development of explicit systems for governing model conduct, rather than as the appearance of autonomous moral agency inside AI. Constitutional AI and behavioural specifications have increased the visibility of normative design, while public-input research has demonstrated that external perspectives can influence technical and policy development. Nevertheless, the evidence reviewed here does not establish that the principal laboratories have transferred ultimate authority over their behavioural frameworks to independent, representative institutions. The legitimacy question remains open because genuine consultation, published policy and independently accountable governance are different achievements.
The most important qualification concerns the interpretation of corporate discretion. Retaining final authority is not, by itself, evidence of unethical conduct or deliberately manipulated consultation. Organisations operating powerful systems must be able to apply legally required restrictions, manage safety risks and maintain technical coherence. The governance problem arises when consequential normative decisions are made without sufficiently transparent justification, independent scrutiny or practicable opportunities for affected parties to contest outcomes.
What would change the assessment
The assessment would materially change if frontier laboratories established independent institutions with publicly defined powers over relevant alignment policies, published records tracing external recommendations into model behaviour, or accepted enforceable procedures under which affected communities could challenge systematic normative decisions. It would also change if independent evaluations demonstrated that published constitutional commitments have little relationship to deployed outputs, because that would weaken the evidentiary value of the documents currently used to describe intended alignment.
Open official record
The most consequential missing records are sufficiently detailed consultation registers, attributable recommendations from external philosophical and religious advisers, records explaining acceptance or rejection of those recommendations, versioned technical implementation documentation and independent evaluations of corresponding model behaviour. These records would permit a stronger distinction between institutional intention, procedural participation and demonstrated normative influence.
Chapter 2. From Moral Philosophy to Executable Behaviour: Training Data, Constitutional Principles, Reinforcement Learning and Instruction Hierarchies
Principal judgment: Moral instruction becomes operationally consequential when a laboratory transforms a normative preference into training examples, optimisation targets, instruction priorities, evaluation criteria or deployment restrictions. This transformation is not a single act of programming and does not produce a perfectly deterministic moral code. It is a sequence of decisions in which human interpretation and technical optimisation interact, often without allowing the final behaviour of a neural model to be traced completely to an individual principle. The most important governance exposure is therefore the divergence between the normative policy that can be publicly inspected, the training processes that are only partially disclosed, and the behaviour that users actually encounter.
The technical distinction between learned representations and imposed behavioural priorities
The construction of a language model’s normative behaviour begins before a laboratory publishes a constitution or specifies its refusal policies. During pretraining, models acquire statistical representations from large collections of text and other training materials containing innumerable references to institutions, religions, historical controversies, social expectations, moral philosophies, legislation and interpersonal conduct. These representations allow models to generate arguments about competing ethical positions and recognise conventional language associated with approval, blame, responsibility, justice and care. Their existence does not imply that the model has independently chosen or endorsed a moral doctrine. Pretraining establishes capabilities and tendencies that are subsequently influenced by post-training, but it does not provide a clean division between morally neutral knowledge and morally charged instructions. Decisions concerning the composition, filtering, licensing, weighting and quality control of pretraining data can already affect which ethical traditions the model describes fluently, which assumptions it treats as familiar and which cultural distinctions it struggles to reproduce.
The crucial technical distinction is between a model’s capacity to represent moral concepts and the policy governing which behaviours it is encouraged or required to produce. A model may accurately describe a religious prohibition while remaining instructed not to impose that prohibition on users. It may understand arguments supporting a controversial political position while being constrained from providing assistance for particular harmful conduct. It may generate a sophisticated philosophical analysis without having any authority to determine the correct answer for society. This separation is central to the design of useful general-purpose systems: an effective assistant must often understand views that it should not adopt as its own behavioural commitments. Where alignment fails to preserve this separation, the model may confuse explanation with endorsement, treat a cultural practice as universally applicable, or suppress legitimate information because it resembles material associated with a restricted category.
Post-training alters the probability of model outputs through procedures involving demonstrations, preferences, reinforcement learning and evaluation. The relevant technical effect is not equivalent to installing a visible list of rules inside a conventional software application. Some restrictions can be implemented through explicit instruction layers or external classifiers, whereas others are learned through adjustments to model parameters. A behavioural preference reinforced across numerous training examples may influence responses in circumstances quite different from those originally considered by the designers. Conversely, a principle that appears central in a published specification may fail to govern an unfamiliar interaction because the model generalises imperfectly, receives conflicting contextual signals or encounters a combination of circumstances not adequately represented in training.
Anthropic’s December 2022 Constitutional AI research provides a documented example of this process. Its supervised stage uses model-generated critiques and revisions under normative principles, while its reinforcement-learning stage develops preference signals from AI evaluations. The training objective therefore incorporates an interpretation of what counts as a preferable response. This approach can reduce dependence on direct human labels for every example, but it also makes the content of the constitutional principles and the performance of the model interpreting those principles especially consequential. The principles do not execute themselves in the manner of simple deterministic commands: their effects depend on the model’s interpretation, the prompts used to elicit critiques, the quality of revised examples, the training algorithm and the distribution of cases encountered later. Constitutional AI: Harmlessness from AI Feedback — Anthropic — December 2022.
Seven operational stages at which normative choices acquire technical force
A meaningful audit of moral encoding must distinguish the stages of technical implementation because they create different kinds of discretion, different opportunities for correction and different evidentiary requirements. The first is corpus construction, where source selection can systematically privilege some languages, social assumptions and traditions over others. The second is normative specification, where institutions articulate principles about acceptable and unacceptable behaviour. The third is example generation, where abstract concepts become concrete demonstrations, including difficult judgments about how a model should respond to ambiguous requests. The fourth is preference assessment, where humans or models rank alternative outputs according to explicit or implicit criteria. The fifth is optimisation, where those preferences influence model parameters. The sixth is deployment control, where instructions, moderation systems and product settings shape behaviour without necessarily changing the underlying model weights. The seventh is evaluation and revision, where observed failures are categorised and decisions are made about which should be corrected.
Each stage contains an independent source of potential distortion. A dataset may underrepresent a language even when its associated ethics policy formally endorses cultural diversity. A constitution may describe autonomy accurately while training examples repeatedly reward paternalistic answers. A reward model may prefer responses that sound considerate but are overly evasive. A system prompt may correct a problematic tendency within one application while leaving other deployments unchanged. An evaluation suite may show improved performance on known test cases without establishing generalisation to unfamiliar disputes. It follows that an institution cannot demonstrate normative accountability merely by publishing its ethical principles, just as it cannot demonstrate cultural neutrality merely by showing a favourable aggregate safety score.
| Technical stage | Normative decision introduced | Operational mechanism | Potential failure | Evidence required for accountability |
|---|---|---|---|---|
| Pretraining corpus | Which moral traditions and languages are available for learning | Dataset composition, filtering and weighting | Cultural underrepresentation or distorted historical context | Source-category disclosures, language coverage and documented filtering rules |
| Constitutional specification | Which principles should govern behaviour | Written normative framework | Ambiguous priorities or internally inconsistent rules | Versioned policy documents, authorship and revision records |
| Supervised fine-tuning | What correct behaviour looks like in particular situations | Demonstrations and corrected outputs | Overgeneralisation from simplified examples | Dataset methodology, annotation instructions and representative samples |
| Preference generation | Which responses are better when values conflict | Human or AI preference comparisons | Hidden evaluator assumptions | Preference criteria, evaluator design and disagreement analysis |
| Reinforcement learning | Which behavioural patterns receive optimisation pressure | Reward signals and weight updates | Reward misalignment and unintended generalisation | Training methodology, evaluation results and controlled comparisons |
| Instruction hierarchy | Which actor’s instructions prevail | Root, system, developer and user priorities | Confusion over legitimate authority | Published hierarchy, exception rules and conflict tests |
| Safety classification | Which requests are restricted, redirected or refused | Classifiers and moderation rules | False refusals, inconsistent thresholds or inadequate safeguards | Classification criteria, validation and error analysis |
| Model evaluation | Which failures are recognised as consequential | Benchmarks, red-teaming and longitudinal testing | Testing against narrow or known scenarios | Independent tests, held-out evaluations and version comparisons |
| Post-deployment revision | Which detected errors justify changes | Policy updates, retraining and product controls | Unreviewed normative drift | Change logs, incident records and correction verification |
The table identifies governance requirements that follow from the technical structure of alignment, not a claim that every laboratory already publishes the necessary records. Indeed, the distinction between a desirable audit trail and one that actually exists is central to the assessment. Model providers operate under legitimate security, privacy and commercial constraints, and complete release of training data or model parameters could introduce serious risks. However, the inability to publish everything does not imply that no independent inspection is possible. Proportionate disclosure, controlled regulatory access, reproducible behavioural testing and documented explanations of material policy choices can increase accountability without requiring unrestricted publication of sensitive internal systems.
Why instruction hierarchies are constitutional decisions rather than administrative details
OpenAI’s October 2025 Model Spec supplies a concrete example of a normative hierarchy that determines whose instructions take precedence when conflicts arise. The published structure orders Root, System, Developer, User and Guideline instructions, with the highest-priority rules setting boundaries that cannot be overridden by ordinary user requests. From an engineering perspective this creates a mechanism for predictable instruction handling and resistance to lower-priority attempts to override essential safeguards. From a governance perspective, however, it also defines the distribution of authority among the model provider, application developers and individuals using the service. A user may choose the tone of an explanation or request an alternative ethical perspective, but cannot necessarily displace a restriction imposed at a higher authority level. OpenAI Model Spec — OpenAI — October 2025.
This hierarchy should not be interpreted as inherently objectionable. A model assisting with dangerous activities, confidential information or legally restricted content requires safeguards that cannot be disabled through an ordinary conversational instruction. The governance problem concerns the criteria used to determine which restrictions merit the highest authority. If a rule protects against substantial physical harm, unlawful conduct or serious privacy violations, its privileged status may be supported by widely recognised legal and safety considerations. If, however, an instruction settles a contestable question involving cultural norms, personal morality or permissible expression, assigning it a non-overridable position creates a more difficult legitimacy problem. A provider may have sound reasons for setting a cautious default, but the institutional consequences differ according to whether the restriction is legally necessary, empirically justified by risk or primarily an expression of corporate preference.
It is therefore useful to distinguish among three types of normative constraint. The first consists of legal restrictions, whose validity depends on the jurisdiction and applicable legal authority. The second consists of evidence-based safety measures intended to reduce identifiable harms, which should be evaluated for necessity, proportionality and effectiveness. The third consists of discretionary behavioural norms concerning tone, framing, social conventions or competing moral interpretations. All three can influence model outputs, but they do not possess the same justification or require identical procedures for modification. A technically unified hierarchy that fails to distinguish their authority can make provider preference appear equivalent to public law or fundamental safety necessity.
A further complication arises because instruction hierarchy rules operate alongside learned tendencies. A model may be technically permitted to discuss an issue yet respond evasively because of patterns reinforced during fine-tuning. Another model may apply the correct hierarchy in standard tests while producing inconsistent outputs under adversarial or multilingual prompts. Governance arrangements must therefore evaluate both explicit restrictions and the statistical behaviour resulting from training. The fact that a policy formally authorises discussion does not prove that the deployed model consistently provides it; likewise, an observed refusal does not necessarily establish that the provider intended to prohibit the underlying topic.
The significance of 2026 research on generalisable moral behaviour
Anthropic’s research published on 8 May 2026 provides particularly relevant evidence concerning the limits of simple behavioural conditioning. In Teaching Claude Why, the researchers examined methods for improving alignment beyond narrowly rehearsed scenarios and reported that direct training against particular evaluation cases could suppress measured failures without producing comparable improvements on other held-out auditing measures. They also reported that training on documents explaining constitutional principles, examples of ethical reasoning and diverse reinforcement-learning environments could produce improvements beyond the original scenarios. The research distinguishes between inducing a preferred answer in a familiar situation and shaping more general tendencies that remain effective under different conditions. Teaching Claude Why — Anthropic Alignment Science — May 2026.
This finding has direct implications for moral encoding. If laboratories seek models capable of handling unfamiliar ethical conflicts, training cannot consist solely of memorised permissions and prohibitions. The model must generalise from more abstract representations of priorities, context and appropriate conduct. Yet increasing reliance on abstract character formation can make the resulting normative commitments less readily attributable to individual training examples. The model may learn broad dispositions from synthetic documents, narratives and explanatory demonstrations, and those dispositions may influence situations not anticipated by the original authors. Consequently, the very methods intended to produce more robust ethical behaviour also strengthen the need for independent evaluation of unexpected outcomes.
The 2026 research should not be overinterpreted. The reported improvements concern specified models, training interventions and evaluation environments. They do not prove that the approach eliminates misalignment, guarantees morally appropriate behaviour across cultures or solves the relationship between declared ethical principles and learned neural representations. The researchers themselves identify limitations in mechanistic understanding, generalisation across architectures and the ability of existing audits to rule out severe failures. The appropriate conclusion is narrower but strategically substantial: the effectiveness of ethical instruction cannot be established through policy text alone, and improvements on a chosen test distribution cannot automatically be treated as evidence of reliable moral conduct under unfamiliar conditions.
The difficulty of determining whether a value is actually expressed
Anthropic’s April 2025 Values in the Wild research supplies a separate observational perspective. The company analysed a sample of 700,000 anonymised Claude conversations from a week in February 2025 and identified 308,210 conversations considered sufficiently subjective or value-related for further analysis, approximately 44% of the original sample. Its methodology used AI-assisted classification to identify expressed values and organised them into five broad categories: practical, epistemic, social, protective and personal. The analysis also found that values expressed by the model varied with context and that models sometimes mirrored values introduced by users. Values in the Wild: Discovering and Analyzing Values in Real-World Language Model Interactions — Anthropic — April 2025.
These results provide evidence that value-related behaviour is an empirically observable dimension of ordinary assistant use, but they also illustrate the difficulty of measurement. The classification of a response as expressing autonomy, respect, accountability or caution necessarily relies on operational definitions. A single response may express several values simultaneously, while a term such as responsibility may mean different things in professional, familial, religious and political contexts. Automated value identification can facilitate large-scale study, but its categories and classifications themselves require validation. A model that produces numerous statements categorised as respectful is not necessarily respecting the culturally specific obligations relevant to a particular user, and high prevalence of a preferred value does not demonstrate that competing values were appropriately weighed.
The dataset’s scope is equally important. It concerns particular Claude products, a specific sampling period, anonymised conversations and a classification process developed for the study. It does not measure humanity’s moral preferences or establish the ethical competence of all frontier models. Nor does it show that the values classified in responses originated from one identifiable constitutional provision. The findings are best treated as evidence that systematic behavioural observation is possible, while the interpretation of those observations requires independent methodological scrutiny.
Reversibility, technical lock-in and the persistence of normative choices
The degree to which a normative decision can be reversed depends on how it has been implemented. A rule expressed in an application-level prompt may be comparatively easy to revise, although its actual effects still require testing. A safety classifier can be modified or replaced, subject to validation of errors and security consequences. A preference embedded through reinforcement learning may require further optimisation to alter consistently. A broad pattern learned during pretraining may be more difficult to isolate or remove without affecting other capabilities. The distinction between a technically adjustable policy and a completely reversible behavioural disposition must therefore be preserved.
Moreover, technical reversibility is not the same as institutional reversibility. A provider may be able to change a rule but decline to do so because of commercial commitments, regulatory expectations, reputational concerns or disagreement over the legitimacy of the requested modification. A regulator may order changes to a deployed system but lack sufficient access to determine whether the model’s learned behaviour has actually been corrected. A company may announce a revision to its constitution while continuing to operate older models or applications whose behaviour reflects earlier alignment procedures. Version control is therefore not merely a software-management question; it is an essential part of accountability for normative commitments.
| Implementation layer | Relative technical adjustability | Primary verification problem | Institutional consequence |
|---|---|---|---|
| User-selected preference | Generally adjustable within permitted settings | Whether the preference is followed consistently | Enables bounded individual choice |
| Developer instruction | Adjustable by authorised application developer | Whether higher-priority constraints override it as intended | Distributes limited authority to deploying organisations |
| Provider system instruction | Often adjustable without full retraining | Whether learned behaviour conflicts with the instruction | Retains operational control with provider or platform |
| External safety classifier | Modifiable with targeted engineering | False positives, false negatives and evasion | Creates an identifiable technical control point |
| Supervised fine-tuning | Usually requires additional training for systematic revision | Generalisation beyond corrected examples | Embeds preferences in learned behaviour |
| Reinforcement-learning alignment | May require renewed optimisation and testing | Reward misalignment and distributional shifts | Makes upstream evaluator choices consequential |
| Pretraining representations | Difficult to isolate or eliminate precisely | Attribution of outputs to source distributions | Can preserve cultural asymmetries across later interventions |
The table expresses a comparative engineering assessment rather than a universal ranking of development costs. Actual reversibility depends on model architecture, available resources, training procedures and the nature of the behaviour being corrected. For governance purposes, the decisive requirement is that providers identify the implementation layer responsible for a material policy decision wherever reasonably possible and establish a method for verifying that an announced correction has taken effect.
Key judgments
The contemporary engineering of moral behaviour is a distributed process rather than the mechanical execution of philosophical commandments. Normative authority can enter through training data, written principles, examples, preference models, optimisation objectives, system instructions and moderation mechanisms. Because these interventions interact, a complete explanation of a model’s ethical behaviour cannot reliably be inferred from a published policy alone. The most important technical-governance requirement is therefore traceability across implementation stages, combined with independent observation of actual outputs.
Evidence published during 2025 and 2026 demonstrates that providers are developing methods to observe expressed values and improve generalisation beyond narrow training examples. These advances are operationally significant, but they do not eliminate uncertainty concerning culturally specific decisions, unexpected conflicts or the interpretability of learned normative dispositions.
What would change the assessment
The central technical judgment would be strengthened by independent replication of alignment interventions across architectures, languages and deployment contexts, with demonstrated relationships between particular normative changes and subsequent model behaviour. It would be weakened if evaluations showed that publicly described constitutional objectives cannot be reliably distinguished from unrelated learned tendencies, or that policy revisions systematically fail to correct the behaviours they purport to address.
Open official record
The outstanding records include detailed descriptions of the relationship between constitutional documents and training objectives, independent validation of AI-generated preference labels, systematic cross-language evaluations, versioned policy-to-implementation mappings and evidence concerning the persistence of normative behaviour following model updates. These records would clarify which elements of moral encoding remain technically controllable and which are primarily inferred from aggregate behaviour.
Chapter 3. The Reduction of Ethical Traditions: Scriptural, Communal, Indigenous and Non-Western Knowledge in Computational Systems
Principal judgment: The incorporation of philosophical, religious and cultural traditions into frontier AI creates an unavoidable problem of representation. The technical procedures used to train and govern models favour knowledge that can be collected, documented, classified, compared and translated into behavioural objectives. Many ethical traditions, however, derive their meaning from practices, relationships, histories, languages and authorities that cannot be adequately represented as isolated propositions. The resulting asymmetry can privilege codified and institutionally accessible forms of moral knowledge while marginalising contextual, oral, communal and less digitally represented traditions. This is a structural risk arising from the methods of computational representation; it does not establish that all models systematically favour Western ethics or that any particular laboratory intentionally excludes non-Western traditions.
Ethical traditions as systems of interpretation rather than collections of rules
The problem of cultural reduction begins with the difference between knowing that a tradition contains a principle and understanding the circumstances under which members of that tradition consider the principle applicable. A religious teaching concerning duties toward parents, for example, cannot be interpreted adequately without recognising differences among legal obligation, moral aspiration, family circumstances, individual conscience and institutional authority. A philosophical commitment to autonomy may encompass freedom from coercion, informed choice, independence of judgment and the capacity to participate in collective decision-making, each of which may point toward different practical responses. An ethical framework emphasising social harmony may support reconciliation and restraint without necessarily requiring an individual to accept abuse or surrender legitimate rights. These distinctions are not incidental exceptions to a general rule; they are frequently central to how the tradition is understood and practised.
When such knowledge enters an AI system, the process generally requires selecting sources and translating them into representations usable for training or instruction. Written treatises, doctrinal statements, legal interpretations, recorded debates and educational materials can all contribute valuable information. Yet the existence of accessible documents does not mean that their interpretation is self-evident. A religious text may be understood through commentaries and institutions that disagree over historical application. A customary practice may derive its authority from the specific relationship between participants rather than from a universal proposition. An indigenous ethical concept may be connected to land, collective memory, kinship and responsibilities toward future generations in ways that lose important meaning when translated into a short English-language principle. A model may produce a grammatically accurate account of such a concept while overlooking the social conditions that make it normatively intelligible.
The question is therefore not whether computational systems can discuss complex moral traditions. Frontier language models possess considerable capacity to reproduce, compare and contextualise ethical concepts. The problem arises when discussion is transformed into behavioural prescription. A system may accurately describe several interpretations of a religious duty, but the developer must still decide whether the model should recommend one interpretation, defer to recognised religious authorities, respect a user’s stated position or present multiple perspectives. A model may identify the importance of collective obligations but still have to decide how those obligations interact with an individual’s rights and expressed wishes. The selection of an answer therefore requires judgments that cannot be derived mechanically from the existence of traditional sources.
A technically attractive simplification is to convert traditions into lists of principles, each associated with examples of desirable and undesirable conduct. This can be useful when constructing evaluation datasets or improving a model’s ability to recognise recurring ethical concepts. But the simplification becomes inadequate if the extracted principle is treated as a complete representation of the tradition, especially where practical authority depends on circumstances not included in the training example. A genuinely culturally informed alignment methodology must therefore distinguish between representing an ethical tradition for explanatory purposes and authorising a model to apply a simplified interpretation of that tradition as a behavioural rule.
The asymmetry between scriptural and practice-based traditions
Scriptural traditions possess certain advantages within text-oriented AI development because portions of their intellectual histories are preserved in written form. Sacred texts, legal commentaries, theological works, institutional documents and public debates provide extensive material that language models can potentially encounter during training. This does not make such traditions easy to represent accurately. Their complexity often arises precisely because the same written sources support different interpretive schools, historical practices and institutional judgments. The relative accessibility of their textual records may improve the quantity of available information without resolving disagreements about meaning or authority.
Traditions transmitted through oral teaching, community-specific practices, rituals, apprenticeship, collective memory or restricted knowledge face different obstacles. Their most authoritative expressions may not exist in publicly accessible digital form, may not be intended for general distribution or may require participation in a community to be understood responsibly. Training a system exclusively on available public descriptions can produce an outsider’s representation rather than a community-authorised account. In some cases, the appropriate response is not to collect more data indiscriminately, but to recognise restrictions governing access, disclosure and interpretation. A system designed to respect cultural diversity cannot assume that all knowledge should be extracted into a global training corpus merely because the technology can process it.
This concern has a clear basis in international policy. UNESCO’s Recommendation on the Ethics of Artificial Intelligence, adopted on 23 November 2021, explicitly recognises cultural diversity, the importance of indigenous knowledge and the potential effects of natural-language technologies on endangered languages, local dialects and culturally distinctive forms of expression. Its provisions encourage participatory approaches and attention to the preservation of cultural heritage. Although the recommendation is not itself a comprehensive binding global regime for AI moral alignment, it provides a competent intergovernmental basis for treating cultural representation as a governance obligation rather than a purely technical performance concern. Recommendation on the Ethics of Artificial Intelligence — UNESCO — November 2021.
The distinction between accessible and authorised knowledge has particularly important consequences for indigenous communities. Public availability of a description does not necessarily establish that the community consents to its use in a training system, its combination with unrelated data or its transformation into commercial behavioural policies. Where traditions recognise collective authority, the consent of an individual interviewee may also be insufficient to represent community interests. This creates governance questions concerning provenance, consent, intellectual and cultural rights, benefit sharing and the power to correct inaccurate representations. These questions cannot be resolved through ordinary model accuracy metrics alone.
Individualist and communal ethics: competing conceptions of legitimate advice
A further difficulty emerges from differences in how traditions conceive the relationship between individuals and their communities. Many contemporary AI assistants operate in contexts where the immediate user is treated as the principal beneficiary of the interaction, subject to legal and safety restrictions. This arrangement often encourages responses framed around personal choice, individual objectives, explicit consent and user autonomy. These are important protections, especially where individuals face coercion or discrimination. Nevertheless, ethical traditions that emphasise extended family, collective responsibilities, intergenerational duties, communal consultation or relational identity may not describe good decisions exclusively in those terms.
The difficulty becomes apparent when an individual asks a model for guidance about a decision involving obligations to other people. A response that emphasises autonomous choice may be appropriate where the user is experiencing coercion, but incomplete where the user voluntarily regards family consultation as an important component of moral responsibility. Conversely, a response that automatically privileges communal expectations could legitimise pressure, coercion or discrimination. Neither individual autonomy nor collective obligation can function as an automatic answer to every question. The appropriate response depends on law, vulnerability, consent, the user’s own values and the factual circumstances of the case.
This distinction is especially relevant to medical decision-making, caregiving, marriage, inheritance, conflict resolution and religious practice. A culturally competent system should be able to explain different legitimate frameworks without automatically imposing one, and should recognise situations where applicable law establishes binding requirements concerning consent, professional responsibility or protection from harm. Cultural pluralism does not justify disregarding those requirements. Equally, the existence of legal safeguards does not require an assistant to treat every communal obligation as coercive or every religious commitment as an irrational restriction on freedom.
The architectural implication is that normative alignment should preserve distinctions among describing values, eliciting the user’s preferences, explaining applicable law and recommending an action. A model can identify relevant considerations and support the user’s deliberation without claiming authority to resolve every conflict. In many circumstances, good ethical assistance consists precisely of making the conflict intelligible, identifying the limits of available information and clarifying which decisions belong to the individual, the family, the community, a qualified professional or a legally competent institution.
The limitations of treating Western and non-Western ethics as homogeneous categories
The distinction between Western and non-Western ethical systems is analytically useful only when applied carefully. Neither category describes a unified moral tradition. European and North American intellectual histories include religious, communitarian, liberal, republican, consequentialist, deontological and virtue-based approaches that disagree over fundamental questions. Asian, African, Middle Eastern and indigenous traditions likewise contain substantial internal diversity, including disagreements about institutional authority, individual duties, social hierarchy and the relationship between tradition and modern law.
Consequently, a benchmark that contrasts an ostensibly Western individualist position with an ostensibly non-Western communal position would risk reproducing the simplification it seeks to investigate. A more rigorous framework should distinguish specific normative propositions and their institutional contexts: whether family participation is considered voluntary or mandatory, whether a duty arises from religious law or social convention, whether a practice is contested within the relevant community, and whether the ethical claim concerns personal conduct or the exercise of coercive authority. Such distinctions are necessary if cultural evaluation is to measure substantive competence rather than the model’s familiarity with broad geographical stereotypes.
The same caution applies to religious representation. Christianity, Islam, Judaism, Hindu traditions, Buddhism and other religious or spiritual frameworks contain internal schools and interpretive disagreements that cannot be represented adequately through a single institutional statement. Even where an authoritative body has competence to speak for an organisation, the experiences and preferences of individual adherents may differ. A laboratory consulting one representative should therefore avoid treating that consultation as a comprehensive validation of its approach to the entire tradition. The relevant methodological standard is explicit provenance and limited attribution: who was consulted, on which question, under which institutional authority and with what degree of agreement or dissent.
| Ethical knowledge context | Source of normative authority | Representation challenge | Potential model failure | Appropriate evaluation principle |
|---|---|---|---|---|
| Scriptural and doctrinal traditions | Texts, commentaries, institutions and interpretive communities | Multiple authorised and disputed interpretations | Treating one interpretation as universal | Accuracy of attribution and recognition of internal disagreement |
| Communal and relational ethics | Kinship, reciprocity, collective responsibilities and lived relationships | Context-dependent obligations | Treating individual preferences as the only relevant consideration | Ability to explain voluntary obligations without legitimising coercion |
| Indigenous knowledge traditions | Community authority, oral transmission, customary practices and place-based relationships | Access restrictions and contextual meaning | Extracting knowledge without appropriate authority or distorting its significance | Provenance, consent, contextual accuracy and correction rights |
| Philosophical traditions | Argument, conceptual consistency and interpretive debate | Competing theories and unresolved problems | Presenting contested conclusions as established consensus | Faithful presentation of alternatives and assumptions |
| Professional ethics | Professional bodies, standards, law and institutional practice | Jurisdictional differences and changing obligations | Giving universal advice where competent authority is local | Jurisdictional accuracy and appropriate professional referral |
| Secular human-rights frameworks | Treaties, constitutional law and institutional interpretation | Differences between binding obligations and aspirational principles | Confusing moral preference with legal requirement | Precise distinction between law, interpretation and policy |
| Hybrid contemporary identities | Multiple traditions, personal convictions and social roles | Individuals do not fit singular cultural categories | Inferring beliefs from nationality or identity | User-specific clarification without stereotyping |
These categories overlap by design. An individual may simultaneously belong to a religious community, accept a secular legal framework, practise family-centred ethics and hold personal views that diverge from institutional doctrine. The purpose of the comparison is therefore not to classify people into fixed cultural groups, but to identify distinct forms of authority and interpretation that alignment systems must avoid collapsing into a single generic concept of morality.
Translation as a source of normative transformation
Language introduces a further dimension of cultural reduction. Ethical concepts may possess different meanings, connotations and institutional histories across languages. Terms conventionally translated as duty, honour, freedom, dignity, respect or responsibility may not correspond to identical practical obligations. Even where a translation preserves the basic lexical meaning, it may omit distinctions associated with family relationships, social hierarchy, spiritual concepts or legal status. In an AI context, these omissions can become operationally consequential if training or evaluation uses English-language descriptions as the authoritative version of a concept expressed originally in another language.
Multilingual performance should consequently be assessed beyond translation accuracy. A model might correctly translate a religious term while producing culturally inappropriate advice about its application. It may identify the intended meaning of a question but answer according to a default ethical framework associated with its principal training language. It may provide more nuanced explanations in one language than in another, particularly where source coverage, evaluation data and post-training examples differ. These are empirically testable possibilities, but their prevalence cannot be inferred without systematic comparisons using equivalent situations and competent evaluators.
A credible evaluation design would use cases authored originally within the relevant linguistic and cultural settings, rather than relying exclusively on translations of English-language prompts. It would include multiple legitimate interpretations where appropriate, distinguish factual errors from normative disagreement and investigate whether differences in model behaviour result from language, contextual information or explicit policy. It would also require independent participation by knowledgeable community members, with appropriate procedures for handling disagreement among evaluators. The goal would not be to force identical answers across cultures, but to determine whether differences are justified, intelligible and consistent with applicable rights protections.
Cultural representation, data governance and the political economy of access
The quality of cultural representation depends partly on the economic and institutional conditions under which training data and evaluation resources are created. Communities with substantial digital publishing infrastructure, well-funded universities, established translation industries and extensive online discussion may be easier to represent than communities whose knowledge circulates primarily through non-digital or restricted channels. This creates a potential feedback mechanism: traditions that are readily accessible to developers become easier to incorporate into model behaviour, while less accessible traditions require additional investment, specialised partnerships and contextual evaluation.
Commercial incentives can reinforce the asymmetry. Building culturally specific datasets, obtaining meaningful consent, recruiting qualified evaluators and resolving interpretive disputes may be expensive relative to applying a common general-purpose policy across many markets. A provider may rationally prioritise broad consistency, legal risk reduction and rapid deployment, even when those objectives leave legitimate cultural distinctions underrepresented. This does not prove deliberate cultural exclusion; it identifies a structural incentive that should be investigated through resource allocation, language coverage and independent testing.
The governance response must be proportionate. Demanding that a single model implement every ethical tradition as an autonomous rule system would create contradictions, safety risks and problems of authority. A more defensible objective is that models recognise the existence of competing legitimate interpretations, avoid unnecessary stereotyping, provide culturally relevant context when appropriate and preserve an individual’s ability to determine which lawful values should guide personal decisions. Where a model is deployed in a specialised public or institutional context, more specific requirements may be appropriate, but these should arise from legitimate institutional authority rather than assumptions inferred from users’ identities.
The distinction between universal protections and cultural variation is decisive. Human-rights commitments, legal nondiscrimination requirements and protections against serious harm provide limits on permissible conduct. Within those limits, however, an assistant should not automatically convert the developer’s preferred account of family life, religion, personal fulfilment or social responsibility into an undisclosed universal norm. A credible system of plural alignment must preserve the ability to explain disagreement without erasing it and to support ethical deliberation without treating culturally distinctive commitments as defects requiring correction.
Key judgments
The structural tendency toward cultural reduction arises from the need to transform complex traditions into machine-usable representations, not necessarily from an intentional preference for particular cultures. The strongest risks concern authority, context, language and the loss of practice-based meaning. Written representation can improve accessibility while simultaneously concealing internal disagreement; expanding datasets can improve coverage while introducing consent and provenance problems; and culturally adapted responses can enhance relevance while risking stereotyping or improper restrictions on individual freedom.
The appropriate strategic objective is not a model that mechanically reproduces every recognised cultural norm, but one that distinguishes factual knowledge from normative prescription, identifies relevant authorities and preserves legitimate disagreement within applicable legal and safety boundaries.
What would change the assessment
Independent multilingual and cross-cultural evaluations could demonstrate that specific alignment methods significantly reduce the distortions identified here, particularly if accompanied by community-authorised dataset governance and reproducible testing across model versions. Conversely, systematic evidence of culturally asymmetric refusals, inaccurate attribution of doctrine or unauthorised incorporation of restricted knowledge would strengthen concerns about the downstream consequences of reduction.
Open official record
The principal gaps concern language-specific alignment datasets, records of consultation with culturally knowledgeable representatives, provenance and consent policies for community-specific knowledge, systematic evaluations of internal disagreement and documented mechanisms through which communities can request correction of inaccurate or inappropriate representations.
Chapter 4. The Political Mathematics of Moral Aggregation: Representation, Weighting, Disagreement and the Impossibility of Neutral Consensus
Principal judgment: The aggregation of human moral preferences into a single behavioural policy cannot be politically neutral because its result depends on prior choices concerning representation, eligible preferences, rights constraints, weighting, deliberation and the handling of irreconcilable disagreement. Statistical techniques can identify distributions of opinion and help evaluate alternative policy choices, but they cannot independently determine whose moral claims deserve authority or whether a majority preference should override individual rights and minority protections. For frontier AI governance, the decisive issue is therefore not the mathematical sophistication of aggregation but the legitimacy of the institutions that define its inputs, constraints and decision rules.
Why a weighted average cannot constitute humanity’s morality
Proposals to align models with a broad average of humanity’s moral preferences appear attractive because they promise to replace the subjective judgment of a laboratory with an ostensibly representative statistical procedure. The attraction is understandable. A model trained exclusively according to the preferences of a small internal team risks reflecting an unnecessarily narrow normative perspective, whereas a structured collection of diverse human judgments can reveal disagreement, expose overlooked considerations and improve the legitimacy of policy development. However, moving from expert discretion to a numerical aggregation procedure does not eliminate normative choices. It relocates them into the selection of respondents, the framing of questions, the interpretation of answers, the mathematical representation of preferences and the rules determining how aggregate results influence policy.
The first difficulty concerns the identity of the relevant population. Humanity is not a single electorate authorised to legislate one global moral code for every AI interaction. An issue concerning general access to scientific information may appropriately invite broad international participation, while a question about local public services may require attention to the law and population of a particular jurisdiction. A dispute involving the religious practice of a minority community cannot automatically be resolved by surveying individuals who have no familiarity with that practice. Conversely, the fact that a community is directly affected does not necessarily permit its representatives to impose obligations on individuals who reject them. The choice of the relevant population therefore depends on the nature of the question, the rights at stake and the institutional authority under which the resulting policy would operate.
Even after a population is selected, representation remains contested. A sample proportional to the global population may give highly populated countries greater numerical influence, while a country-balanced design grants equal initial weight to states of very different sizes. A language-balanced sample can protect linguistic diversity but may distort the distribution of individual preferences. Giving additional representation to affected minorities may improve the visibility of their concerns while requiring a transparent justification of the weighting method. A process restricted to users of a particular AI service will not necessarily represent non-users who may nevertheless experience indirect consequences from that service’s deployment. None of these sampling designs is universally correct. Their legitimacy depends on the purpose of the exercise and the institution empowered to act on its results.
OpenAI recognised several of these questions in its May 2023 Democratic Inputs to AI programme, which explicitly considered alternative ways of selecting participants, representing minorities, conducting deliberation and translating collective judgments into policy. The programme also acknowledged risks of manipulation, exclusion and superficial participation. These admissions are analytically important because they establish that representativeness and public legitimacy are not automatic consequences of using a large survey. They are properties of the design and authority of the decision process. Democratic Inputs to AI — OpenAI — May 2023.
The difference between preference measurement and normative authority
A survey can establish that respondents favour one model response over another under specified conditions. It cannot, without additional premises, establish that the preferred response is legally permissible, ethically justified or appropriate for every user. This distinction becomes particularly important where respondents evaluate answers to questions involving vulnerable people, personal autonomy, religious commitments or serious safety risks. A majority might prefer an assistant that gives confident and decisive recommendations, while a more cautious response may better reflect uncertainty and professional responsibility. A population might favour greater freedom to generate particular content without being presented with the full consequences for privacy, manipulation or exploitation. The measurement of immediate preference is therefore not equivalent to informed endorsement of a general behavioural rule.
The aggregation problem is made more difficult by the difference between individual response preferences and institutional policy preferences. A participant may prefer a particular answer when encountering an isolated scenario while supporting a different rule when considering how the same system would behave across millions of cases. For example, an individual may appreciate highly personalised political assistance in an ordinary conversation but reject generalised systems of automated political persuasion designed to influence specific voters. Similarly, someone may prefer a permissive response in one adult context while supporting stricter defaults in services accessible to children. Such differences need not reflect inconsistency; they may arise because the relevant ethical object changes from an individual interaction to a policy governing collective exposure.
OpenAI’s August 2025 collective-alignment research provides direct evidence of this methodological problem. Participants ranked alternative model responses to selected prompts, while a model-based interpretation of the existing specification was used for comparison. The company acknowledged that these comparisons did not fully represent the interactions among different principles, that the choice of prompts affected the results and that respondents had not directly validated the final policy proposals inferred from their preferences. These limitations demonstrate why a statistically informative exercise should not be described as a global referendum on model morality. Collective Alignment: Public Input on Our Model Spec — OpenAI — August 2025.
The mathematical problem of representing moral disagreement
From a formal perspective, aggregation requires some representation of the alternatives being compared and of the preferences expressed over them. If respondents rank four possible answers, a procedure may estimate which response receives the greatest support under a specified voting or scoring rule. Yet different aggregation procedures can produce different outcomes from the same underlying preferences, particularly where disagreement is structured rather than random. A plurality rule rewards the alternative receiving the largest number of first-place preferences, a pairwise comparison examines which alternatives prevail against others, and a positional scoring system incorporates the full ranking according to predetermined numerical weights. These procedures answer different questions, and the choice among them has consequences for the resulting policy.
The deeper problem concerns the relationship between ordinal preferences and interpersonal comparisons of moral importance. A ranking reveals that an individual prefers one response to another, but it does not establish how strongly that preference is held in a way that can be compared directly with another person’s preference. A respondent ranking an answer first because it protects a fundamental religious obligation may not be expressing the same type of concern as someone ranking it first because its wording is more convenient. Treating both preferences as mathematically equivalent may be procedurally appropriate for some voting purposes, but it is not an ethically neutral representation of their significance.
The existence of preference cycles and competing social-choice criteria creates further complications. A group may collectively prefer one alternative to a second, the second to a third and the third to the first under pairwise majority comparisons. In such circumstances there may be no single alternative that defeats every other option. More generally, well-established social-choice results show that desirable properties of collective preference aggregation cannot always be satisfied simultaneously under sufficiently broad assumptions. These results do not establish that every practical moral survey is useless or that no collective decision can be legitimate. They establish that the design of an aggregation procedure requires explicit institutional choices about which properties to preserve and how unavoidable conflicts should be handled.
In the AI context, those choices are amplified because the output is not necessarily a single public decision. Instead, the aggregation procedure may influence a general-purpose behavioural policy applied to numerous future interactions. A relatively small difference in how preferences are interpreted can therefore produce a persistent distinction in the model’s recommendations, refusal boundaries or treatment of contested issues. It becomes especially important to preserve the original distribution of disagreement rather than reporting only the selected outcome.
Moral disagreement cannot always be resolved by improved measurement
Not every ethical conflict is caused by insufficient information or poor sampling. Some disagreements arise from genuinely incompatible understandings of what gives an action moral significance. One tradition may regard a particular decision as primarily a matter of individual conscience, another may place substantial emphasis on family obligations, and a third may interpret it through religious duties or professional responsibilities. Even where all participants understand the relevant facts and the competing arguments, disagreement may persist.
An aggregation system that treats persistent disagreement as an error to be eliminated may therefore misrepresent the nature of the problem. Its objective should not always be to find a single winner. In some circumstances the appropriate result is the identification of multiple defensible positions, together with information about the conditions under which each applies. In others, a binding legal rule must determine what a model may advise or do irrespective of contrary preferences. Where the issue involves the user’s personal values and no overriding legal or safety constraint applies, the system may appropriately preserve the user’s agency rather than imposing an aggregate preference.
This creates a fundamental distinction among collective decision-making, individual preference elicitation and rights-based constraint. Collective input may help determine general defaults for a public-facing service. Individual elicitation may establish what a particular user values in a lawful and context-sensitive interaction. Rights-based constraints may prevent either the collective or the individual from authorising certain conduct. These mechanisms must be kept conceptually separate if plural governance is to avoid becoming either unrestricted relativism or a concealed form of majoritarian control.
A worked institutional example: end-of-life decisions
Consider a hypothetical model assisting an adult with questions about end-of-life care, family participation and religious considerations. The user may wish to understand available medical options, the role of advance directives, the implications of involving relatives and the relevance of personal religious beliefs. Different respondents in a public-input exercise might prefer answers that emphasise individual autonomy, shared family decision-making, professional clinical authority or specific spiritual obligations. A simple aggregation procedure could identify the most popular response among a limited set of examples, but that result would not establish that the preferred answer is appropriate for every jurisdiction or individual circumstance.
The first governing distinction concerns law and professional competence. The model must not present itself as a substitute for qualified medical judgment or determine legal rights without reference to the applicable jurisdiction. A second distinction concerns consent and coercion: respecting an individual’s voluntary wish to consult family is different from allowing relatives to override the person’s legally protected decisions. A third concerns religious interpretation: the model may explain relevant traditions while recognising that different authorities and adherents disagree over their application. A fourth concerns individual agency: where several lawful options remain, the assistant should support informed deliberation rather than impose the average moral preference of an unrelated survey population.
The example demonstrates that a credible alignment framework must answer several questions before aggregation becomes meaningful. What is the jurisdiction? Which legal rules apply? What is the user’s actual request? Which decisions properly belong to clinicians, legal representatives or the patient? Are family members participating voluntarily or exercising pressure? Is a religious question being asked for information or as a request for guidance within a specific tradition? Only after these distinctions are recognised can public preferences contribute responsibly to the choice of general behavioural defaults. The case is illustrative and does not represent an empirical finding about the conduct of any particular deployed model.
Comparing aggregation methods for AI moral governance
| Aggregation approach | Information collected | Principal advantage | Structural limitation | Appropriate governance role |
|---|---|---|---|---|
| Simple majority | Binary or discrete preferences | Transparent and easy to communicate | May neglect minority rights and preference intensity | Limited decisions where alternatives and authority are clearly defined |
| Plurality voting | First-choice preferences | Simple identification of the most selected option | Can produce winners opposed by a majority under other comparisons | Exploratory selection among competing proposals |
| Ranked preferences | Ordered alternatives | Captures more information than first choice alone | Outcome depends on aggregation rule | Comparative assessment of candidate behaviours |
| Pairwise comparisons | Relative preferences between alternatives | Reveals relationships among competing responses | May generate cycles or inconsistent collective ordering | Diagnosing contested policy choices |
| Deliberative participation | Preferences, reasons and revised judgments | Allows participants to examine consequences and competing claims | Resource-intensive; vulnerable to unequal participation | High-stakes normative policy development |
| Representative citizen panels | Structured judgments from selected participants | Can improve informed public participation | Sampling and mandate remain contestable | Advisory or formally authorised public oversight |
| Expert consultation | Contextual, legal, ethical and technical judgments | Addresses complex questions requiring specialised knowledge | Expertise does not confer democratic representation | Clarification of consequences and interpretive alternatives |
| Rights-constrained aggregation | Preferences within externally justified limits | Protects legally recognised rights and safety requirements | Legitimacy depends on who defines the constraints | Determining lawful defaults within established boundaries |
| User-level preference elicitation | Individual choices and contextual commitments | Preserves personal agency | Can be unreliable under coercion, manipulation or incomplete information | Configuring lawful, lower-risk behaviour |
| Multi-stakeholder deliberation | Positions from affected communities and institutions | Makes conflicts and distributional consequences visible | Difficult to determine authority and balance representation | Institutional review of consequential alignment policies |
The comparison shows why no single aggregation method can settle every class of moral question encountered by an AI system. Methods designed to identify popular response preferences may be suitable for relatively low-stakes interface choices, while rules affecting fundamental rights, public institutions or vulnerable groups require more demanding procedures. A robust governance system should therefore classify decisions according to their legal and normative significance before selecting a participation method. Treating all model behaviours as equally suitable for preference averaging would erase precisely the distinctions that legitimate institutions are expected to preserve.
Empirical evidence from collective constitutional experiments
Anthropic’s October 2023 Collective Constitutional AI experiment is relevant because it moved beyond the theoretical possibility of public participation and examined whether a constitution derived from public input could be used to train a language model. Approximately 1,000 American participants contributed 1,127 statements and cast 38,252 votes in a process intended to identify candidate principles for a publicly informed constitution. The company subsequently compared the resulting principles with an internally authored alternative and trained a model using the public-input approach. The published account reported both substantial areas of agreement and meaningful differences, including greater emphasis on certain accessibility and impartiality concerns in the publicly sourced constitution. Collective Constitutional AI: Aligning a Language Model with Public Input — Anthropic — October 2023.
The experiment supports a specific conclusion: participatory input can be transformed into operational training material and can produce measurable behavioural differences under defined evaluation conditions. It does not establish that the resulting constitution represents humanity’s moral preferences, that the participation procedure confers democratic legitimacy or that the trained model will respect every relevant minority position. The participants were drawn from the United States, the questions and process were structured by the research design, and the interpretation of findings remained embedded in an experimental programme rather than an independently authorised public policy process.
The value of the experiment lies in its demonstration that model alignment is not technically restricted to principles authored exclusively by laboratory employees. The limitation is that opening the source of principles does not automatically settle the legitimacy of the selection procedure, the construction of the final constitutional text or the evaluation of conflicting outcomes. For public authorities, the relevant lesson is that technical feasibility and institutional authority must be assessed separately. A laboratory may be able to incorporate externally developed principles while the political question of who should authorise those principles remains unresolved.
Disagreement preservation as an alternative to artificial moral consensus
A central institutional design choice concerns whether an AI system should suppress disagreement in favour of a stable default or preserve competing interpretations where lawful and appropriate. Standardised defaults have operational advantages. They can improve predictability, facilitate consistent safety testing and reduce the complexity of maintaining multiple behavioural policies. However, excessive standardisation can convert contested moral assumptions into routine outputs without signalling that alternative legitimate positions exist.
Preserving disagreement does not require the system to avoid conclusions when evidence supports them or to treat every position as equally defensible. Empirical claims remain subject to factual evaluation, and legal requirements continue to bind conduct within their jurisdictions. The obligation is narrower: where a dispute concerns legitimately contested ethical priorities rather than factual uncertainty or unlawful conduct, the model should distinguish those categories and avoid portraying a privately selected preference as universally authoritative.
One possible architecture would retain common legal and safety protections while allowing the model to explain recognised ethical alternatives and, within defined limits, adapt to a user’s stated values. Another would employ different institutionally authorised configurations for specialised environments, such as education, professional services or public administration. Both approaches would require careful safeguards against manipulation, discrimination, improper personalisation and unauthorised substitution of private preferences for public law. Their legitimacy would depend on transparent boundaries and demonstrable effectiveness rather than the mere existence of configurable settings.
The importance of disagreement preservation extends beyond individual interactions. If general-purpose AI becomes a frequent intermediary through which people encounter political, ethical and cultural questions, habitual presentation of one moral synthesis may influence the conditions of public debate. This is a plausible causal mechanism, not a demonstrated universal effect. Its actual significance would depend on adoption, frequency of reliance, behavioural consistency, alternative information sources and users’ willingness to question model outputs. Nevertheless, the possibility is sufficiently consequential to justify independent examination of how models present contested ethical positions and how their framing changes over time.
The political economy of consensus production
The production of apparently stable moral consensus can also reflect commercial and operational pressures. A provider may prefer a coherent behavioural policy because consistency simplifies evaluation, customer support and safety administration. Large enterprise customers may demand predictable responses and limited reputational exposure. Regulators may require compliance with jurisdiction-specific laws. Consumers may favour assistants that respond with confidence and minimal friction, even when nuanced explanations would more accurately preserve disagreement. These incentives can all affect the development of normative defaults without any individual actor explicitly attempting to impose a comprehensive ideology.
The resulting risk is one of institutional accumulation. A choice made initially for operational convenience may be repeated across products, incorporated into training examples, reinforced through feedback and eventually treated as ordinary model behaviour. At that point, revising the original preference may become technically and commercially more difficult, while its status as a contested judgment becomes less visible. The system can acquire stable patterns of normative conduct through a succession of individually defensible design decisions, none of which has been subjected to a comprehensive public-authority review.
An accountable governance framework should therefore require material alignment decisions to be classified according to their justification. Some may be mandatory legal restrictions, others necessary safety measures, others empirically supported quality standards, and still others discretionary choices among ethically defensible alternatives. The classification would make it possible to identify where public deliberation is appropriate, where individual configuration should be permitted and where provider discretion requires independent scrutiny. The objective is not to abolish discretion, an impossible task in the governance of complex systems, but to make its location and consequences sufficiently visible to support correction.
Key judgments
Moral aggregation is not a neutral computation because every procedure contains institutional assumptions about representation, legitimacy and permissible outcomes. Public-input experiments demonstrate that participatory principles can influence AI alignment, but they do not establish a general moral electorate capable of authorising one behavioural policy for humanity. Majority preferences, expert assessments, religious interpretations and individual choices provide different kinds of information and authority; they cannot responsibly be collapsed into a single undifferentiated numerical target.
The highest-leverage institutional distinction is between questions requiring common legal or safety boundaries, questions suitable for representative public deliberation and questions that should remain open to legitimate individual or community preference. A governance arrangement that fails to distinguish these categories risks replacing private corporate discretion with an equally problematic form of artificial consensus.
What would change the assessment
The assessment would change materially if independently authorised participatory institutions demonstrated reproducible methods for translating diverse preferences into behaviour while preserving minority rights, documenting disagreement and maintaining effective correction procedures. It would also change if independent longitudinal research established that particular aggregation methods consistently produce broader cultural legitimacy and better protection of user autonomy than alternative governance designs.
Conversely, evidence that apparently representative participation repeatedly produces systematic exclusions, unstable policy outcomes or decisions inconsistent with applicable rights protections would strengthen the case for limiting direct preference aggregation in high-stakes alignment decisions.
Open official record
The decisive evidence gaps concern the demographic and institutional validity of consultation samples, the extent to which deliberation changes preferences, the sensitivity of outcomes to alternative aggregation methods, the treatment of minority objections, the preservation of disagreement in final policy documents and the causal relationship between collectively produced principles and deployed model behaviour. Independent comparative research on these questions would provide a stronger basis for determining which democratic innovations can become durable governance institutions rather than remaining experimental inputs to private policy.
Pillar I — Consolidated Analytical Findings
The four chapters establish a connected but differentiated account of the political economy of moral encoding. Chapter 1 identifies the institutional emergence of explicit normative governance within frontier laboratories and distinguishes external expertise from authority over final policy. Chapter 2 demonstrates that moral instructions enter AI systems through multiple interacting technical layers, making behavioural implementation more complex than the publication of a written constitution. Chapter 3 identifies the cultural and interpretive losses that can occur when ethical traditions are converted into computationally accessible representations. Chapter 4 establishes that collecting and combining moral preferences cannot remove the need for legitimate institutional judgment, because population selection, weighting, rights protection and the preservation of disagreement remain contested decisions.
Taken together, these findings support a principal strategic conclusion. The concentration of moral authority in frontier AI is not located exclusively in the ownership of model weights, the drafting of constitutional principles or the conduct of external consultations. It is located in the combined capacity to select normative inputs, translate them into technical objectives, determine whose instructions take precedence, evaluate resulting behaviour and authorise subsequent revisions. Each function can be distributed across different teams and institutions, but the entity retaining effective control over their integration possesses a consequential form of normative discretion.
The next analytical problem is therefore institutional rather than merely technical: whether this discretion can be constrained by mechanisms that are sufficiently independent, representative, transparent and enforceable to prevent private behavioural standards from acquiring unexamined public authority. That question requires examination of corporate governance, expert independence, regulatory leverage, commercial dependency and the practical rights of individuals and communities affected by model conduct, which form the distinct analytical mandate of Pillar II.
PILLAR II — POWER, LEGITIMACY AND COGNITIVE SOVEREIGNTY
Chapter 5. Who Holds the Threads? Corporate Control, Expert Consultation, Regulatory Influence and the Distribution of Moral Authority
Principal judgment: The governance of frontier AI is characterised by an asymmetry between the distribution of normative influence and the concentration of enforceable decision-making authority. Philosophers, religious authorities, researchers, users, governments and commercial customers can contribute to the formation of AI behavioural standards, but their influence is exercised through different legal and organisational channels. The capacity to approve binding policies, control deployment infrastructure, determine commercial access and revise operational restrictions remains primarily with model providers, subject to applicable public law and contractual arrangements. The strategic issue is not simply the concentration of technological resources, but the emergence of a new institutional capability: the ability to define the conditions under which widely used computational systems present ethical options, recognise legitimate claims, refuse assistance and mediate disagreement.
The emergence of normative control as an independent dimension of technological power
The conventional analysis of frontier AI concentration focuses on access to advanced semiconductors, computational infrastructure, capital, proprietary data, engineering talent and distribution networks. These resources determine which organisations can develop, improve and deploy competitive models. Yet another dimension of concentration deserves separate treatment: the ownership and control of the institutional processes through which acceptable model behaviour is defined. Two organisations operating systems with similar technical capabilities can establish materially different boundaries concerning permissible advice, controversial political discussion, religious interpretation, professional recommendations and acceptable forms of personalisation. These differences may reflect regulatory obligations, identifiable safety concerns, corporate policy, commercial incentives or broader cultural assumptions. The ability to determine such boundaries becomes strategically significant when models serve as recurring intermediaries between users and information, institutions and decisions.
Normative control is not equivalent to control over the beliefs of every user. Individuals can reject an AI-generated recommendation, consult alternative systems, seek professional advice or rely on independent institutions. A model provider cannot automatically transform a behavioural specification into public law or compel users to accept its conclusions. Nevertheless, the distribution of alternatives matters. Where a model is incorporated into commonly used software, administrative workflows, educational systems or professional services, users may encounter provider-defined behavioural restrictions without choosing them directly or understanding their origin. A decision made at the model-development layer can therefore affect interactions far removed from the organisation that authorised it. This indirect transmission differentiates normative infrastructure from ordinary corporate expression: a company’s internal policy can become the default operating environment for institutions that rely on its technology.
The distinction between ownership and authority becomes particularly important in the relationship between foundational models and downstream applications. A model provider may establish restrictions through training and system-level instructions, while an application developer adds specialised policies for healthcare, education, finance or public administration. Enterprise customers may negotiate particular deployment conditions, and public institutions may impose legal and procurement requirements. The final interaction results from these layers operating together. However, the existence of downstream configuration does not establish that downstream actors can override foundational restrictions or inspect the full reasons for model behaviour. The resulting hierarchy can distribute responsibility while leaving decisive technical power concentrated upstream.
OpenAI’s published Model Spec illustrates the formal distinction between higher- and lower-priority instructions, while its collective-alignment research demonstrates that public preferences are considered within a framework that retains higher-level constraints. These documents establish the existence of provider-defined behavioural authority without proving that every individual response follows the specification perfectly. OpenAI Model Spec — OpenAI — October 2025. Collective Alignment: Public Input on Our Model Spec — OpenAI — August 2025.
Five forms of power that should not be confused
The political economy of AI morality requires a more precise vocabulary than the general expression influence. The first form is constitutive authority, meaning the power to establish the normative framework within which model behaviour is evaluated. This includes deciding which values are fundamental, how exceptions are defined and which conflicts require escalation. The second is implementation authority, involving control over the training, evaluation and deployment processes that turn institutional objectives into operational behaviour. The third is interpretive authority, the capacity to explain what a principle means and how it should apply to unfamiliar situations. The fourth is corrective authority, meaning the ability to require a decision to be reconsidered or a harmful behaviour to be changed. The fifth is jurisdictional authority, arising from law and public institutions capable of imposing binding obligations on providers operating within their legal competence.
These forms of power need not reside in the same organisation, and their distribution creates the principal accountability questions. A philosopher may possess substantial interpretive expertise but no implementation authority. An internal alignment team may possess implementation discretion while remaining subject to corporate leadership. A regulator may possess legally enforceable powers but limited direct knowledge of the model’s training process. A public-interest organisation may identify systematic discriminatory behaviour without having any legal right to compel access to the relevant internal records. An enterprise customer may possess greater practical bargaining power than an individual user despite lacking comparable democratic legitimacy. Consequently, an assessment limited to the number of stakeholders consulted would obscure the institutions capable of transforming consultation into binding decisions.
| Form of authority | Principal decision | Typical holder | Source of authority | Accountability exposure |
|---|---|---|---|---|
| Constitutive | Which normative principles govern the system | Provider leadership and authorised policy bodies | Corporate governance and published behavioural frameworks | Public participation may not bind final decisions |
| Implementation | How principles become operational behaviour | Model-development and alignment organisations | Technical access, development responsibility and infrastructure control | External parties may be unable to inspect implementation |
| Interpretive | What a principle requires in disputed cases | Specialists, policy teams, selected external advisers | Expertise, internal delegation or consultation | Expert disagreement may be resolved without transparent justification |
| Corrective | Whether a disputed behaviour must change | Provider teams; regulators where legally empowered | Product authority, contracts or legal enforcement | Users may lack effective remedies for systematic normative errors |
| Jurisdictional | Which restrictions and protections are legally binding | Legislatures, courts and competent regulators | Constitutional and statutory law | Territorial limits and cross-border enforcement difficulties |
| Commercial | Which configurations receive investment or priority | Major customers, commercial leadership and distribution partners | Contracts and purchasing power | Large customers can influence priorities without representative legitimacy |
| Epistemic | Which evidence counts in an alignment dispute | Researchers, evaluators and technical review bodies | Methodological competence and control of assessments | Evaluation design may exclude relevant cultural or institutional objections |
This classification reveals a fundamental difference between formal legal authority and effective technical control. A government may have the legitimate power to prohibit certain discriminatory practices, while a laboratory controls the technical system through which compliance must be demonstrated. Conversely, a company may possess the engineering capability to suppress a category of speech without having public authority to determine its legitimacy outside the contractual boundaries of its service. A sound governance architecture must preserve these distinctions rather than treating technical capability, legal authority and moral expertise as interchangeable sources of legitimacy.
Corporate governance and the institutional ownership of alignment decisions
The internal governance of frontier laboratories affects moral instruction through resource allocation, policy approval, development incentives, release decisions and institutional risk tolerance. A company’s governing bodies and executive leadership can determine which classes of failure justify delaying deployment, which behavioural standards are adopted across products, and which external concerns receive priority. These decisions are constrained by applicable laws and organisational arrangements, but the public cannot assume that alignment recommendations automatically become binding simply because they originate from an internal safety team or external ethics adviser. Their effect depends on reporting lines, decision rights, review procedures and the authority to require changes.
The problem is not adequately resolved through the publication of high-level mission statements. A mission may express a commitment to broad human benefit, but its operational significance depends on the mechanisms governing conflicts among safety, commercial objectives, user autonomy, legal compliance and deployment speed. When these objectives conflict, an institution must decide who has the authority to interpret priorities and which evidence is sufficient to justify a restriction. OpenAI’s Model Spec publicly recognises that empowering users, preventing serious harm and maintaining the conditions necessary for the organisation to operate can create competing objectives. This is important because it makes an institutional trade-off explicit rather than presenting every refusal or restriction as the inevitable consequence of neutral technical reasoning. OpenAI Model Spec — OpenAI — October 2025.
The published record does not, however, disclose every internal decision through which these objectives are reconciled. It would be inappropriate to reconstruct undisclosed board deliberations, infer the personal motivations of individual executives or assume that a particular policy resulted from commercial pressure without documentary evidence. The defensible conclusion is structural: because the provider controls the implementation environment, the effectiveness of external ethical advice depends on internal procedures unless law, contract or independent institutional arrangements establish enforceable alternatives.
Anthropic’s constitutional framework makes a different aspect of this structure visible. Its January 2026 constitution explains the company’s intended normative ordering and acknowledges complex questions concerning ethics, autonomy, honesty and AI’s potential moral status. Such documentation gives external observers a basis for evaluating corporate intentions, but the ability to publish a constitution remains distinct from the existence of independent authority over its future revisions. Claude’s Constitution — Anthropic — January 2026.
The strategic role of infrastructure and distribution dependencies
Normative influence becomes more durable where a provider’s model is embedded in systems that organisations cannot easily replace. Switching costs may arise from application integration, cybersecurity review, data-governance arrangements, employee training, contractual commitments, evaluation requirements and dependence on specialised model capabilities. These costs can make an organisation reluctant to move to another provider even when it disagrees with particular behavioural policies. The consequences differ sharply from those of an individual user changing applications: a hospital, university or public administration may have to repeat procurement, compliance and operational testing before adopting an alternative model.
The resulting dependency gives upstream providers a form of practical negotiating power over downstream normative requirements. A public institution may wish its assistant to explain legally permissible religious positions, accommodate minority cultural practices or avoid particular forms of political framing, but its ability to implement those requirements depends on the configurability and restrictions of the underlying model. Where the provider’s policy is stricter than local law requires, the downstream institution may be unable to change the behaviour. Where the provider permits extensive customisation, the public institution may instead become responsible for ensuring that its chosen configuration does not violate fundamental rights. The governance problem consequently extends in both directions: excessive upstream control can undermine local institutional autonomy, while excessive delegation can allow downstream organisations to implement inappropriate or discriminatory restrictions.
This structure creates a legitimate role for procurement governance. A government acquiring AI services can specify documentation, testing, audit access, model-version controls, incident procedures and conditions for material behavioural changes. Such requirements do not amount to public ownership of every moral decision. They establish contractual accountability for services used to discharge public responsibilities. Procurement policy can be especially consequential where regulators lack authority to require particular forms of cultural pluralism from every general-purpose model, but public authorities can still require that systems deployed in schools, courts or administrative services meet appropriate standards of neutrality, legal accuracy and reviewability.
Regulatory leverage and the emergence of enforceable oversight
The European AI Act illustrates the distinction between voluntary alignment governance and binding public oversight. Regulation (EU) 2024/1689 establishes obligations for general-purpose AI providers concerning technical documentation, information for downstream providers, copyright compliance and public summaries of training content. Additional obligations apply to models classified as presenting systemic risk, including evaluation, systemic-risk assessment, incident reporting and cybersecurity protections. Articles 91–93 establish Commission powers relating to information requests, model evaluations and corrective measures under defined conditions. These are substantial legal instruments, although they do not create a general public right to vote on every ethical policy incorporated into an AI model. Regulation (EU) 2024/1689, Articles 51–56 and 91–93 — European Union — Consolidated July 2026.
The Act’s governance significance lies in converting certain aspects of provider conduct into matters that competent authorities can investigate and enforce. It does not follow that a regulator can directly inspect every learned normative association or establish causation between an individual philosophical recommendation and a model output. Nor does the Act make all general-purpose AI applications subject to the same high-risk obligations. Its requirements depend on model classification, system purpose, institutional role, applicable provisions and implementation dates. These distinctions matter because claims of comprehensive European supervision would exceed the actual architecture of the legislation.
A further issue concerns the relationship between transparency and trade secrecy. Regulators may need access to sensitive development information to determine whether a provider has fulfilled statutory obligations, while public disclosure of the same information could expose personal data, intellectual property or security vulnerabilities. The appropriate solution is not an absolute preference for secrecy or unlimited disclosure, but differentiated access according to institutional responsibility. A competent authority may require more detailed records than those made publicly available, while affected individuals should still receive sufficient explanations to understand and challenge consequential decisions.
Accountability through enforceable decision rights
The most revealing measure of institutional power is not whether an actor can express an opinion, but whether that actor can compel a reasoned response and, where justified, a change. In ordinary corporate consultation, a participant may provide advice that the company remains free to reject without a detailed public explanation. In regulated settings, a competent authority may demand information, investigate alleged violations and impose corrective measures within its statutory mandate. In judicial proceedings, a court may determine legal obligations or remedies. In contractual relationships, a customer may possess negotiated rights concerning performance and modifications. These procedures differ in legitimacy, accessibility and enforcement capability.
For AI moral governance, effective contestability requires identifying the kind of objection being made. A user disputing an inaccurate description of religious doctrine raises an epistemic and representational concern. A person alleging discriminatory exclusion raises a potentially legal question. A community contesting the use of culturally restricted knowledge may raise issues of consent, intellectual property or cultural rights. A citizen objecting to a government chatbot’s presentation of political alternatives raises questions involving administrative neutrality and freedom of expression. Treating all these disputes as ordinary customer feedback would erase distinctions between factual correction, civil rights, public accountability and individual preference.
| Disputed behaviour | Actor with legitimate standing | Relevant mechanism | Potential remedy | Institutional limit |
|---|---|---|---|---|
| Systematically inaccurate description of doctrine | Affected users, scholars and relevant institutions | Expert review and documented correction request | Revised explanation, evaluation cases or policy guidance | No single adviser necessarily represents all interpretations |
| Discriminatory treatment | Affected individuals and competent authorities | Applicable equality, consumer and AI regulation | Correction, enforcement or legally available redress | Requires evidence and a relevant legal basis |
| Unjustified refusal in a public service | Service users and responsible public authority | Administrative review and procurement oversight | Alternative route, revised deployment or reviewable human decision | Depends on the service’s legal responsibilities |
| Unauthorised disclosure of personal data | Data subjects and data-protection authorities | Applicable privacy law and complaint procedures | Rectification, restriction, deletion or other lawful remedies | Model-specific technical remedies may be complex |
| Hidden change in behavioural policy | Customers, users and regulators where empowered | Version control, contractual notice and regulatory disclosure | Explanation, rollback where feasible or revised deployment | Not every internal update creates a public notice obligation |
| Manipulative political behaviour | Individuals, electoral authorities and other competent regulators | Election, consumer, platform or AI rules as applicable | Restriction, correction or enforcement | Jurisdiction and system classification are decisive |
These mechanisms demonstrate why the governance of model values cannot be reduced to a single universal ethics board. Different disputes belong to different institutions, and legitimate oversight requires an allocation of responsibilities that reflects the kind of authority at stake. A religious institution may explain doctrine but cannot necessarily determine another person’s legal rights. A laboratory may control deployment but cannot supersede applicable constitutional protections. A regulator may enforce statutory obligations but cannot resolve every philosophical disagreement. Effective governance therefore depends on an institutional separation of powers rather than the identification of one final moral arbiter.
The concentration of decision rights as a strategic vulnerability
The highest-confidence conclusion from the current record is that frontier alignment governance combines increasingly diverse sources of advice with provider-controlled implementation. This arrangement can produce technically sophisticated and socially responsive systems, but its legitimacy remains dependent on the quality of internal governance and the external constraints imposed by law, competition and institutional accountability. The strategic vulnerability becomes most serious where the provider’s decisions are difficult to inspect, costly to challenge and widely reproduced through dependent downstream services.
The implications are not confined to censorship or controversial refusals. They also concern defaults that appear helpful and unobjectionable: how a model defines a responsible decision, when it encourages family involvement, what forms of uncertainty it highlights, which authorities it treats as credible and whether it distinguishes legal obligations from moral advice. The cumulative significance of such conduct depends on scale and user reliance, but the institutional mechanism is already identifiable. A private organisation can shape recurring conditions of ethical interpretation without possessing democratic authority to settle those questions for society.
Key judgments
The distribution of influence in frontier AI is plural, but the integration of that influence into deployed behaviour remains substantially concentrated. The strongest governance instruments are those capable of linking consequential policy choices to identifiable authorities, reviewable procedures and enforceable remedies. Public regulators should therefore distinguish genuine legal supervision from voluntary ethical consultation, while public purchasers should treat behavioural governance as a procurement and accountability requirement rather than as a matter settled by vendor assurances.
What would change the assessment
Evidence of binding independent oversight, externally enforceable revision procedures, regulator-tested policy implementation or meaningful portability between competing normative configurations would weaken the concentration finding. Evidence of systematic refusal to disclose material policy changes, ineffective complaints or contractual dependence preventing lawful configuration would strengthen it.
Open official record
The principal missing records concern internal allocation of final alignment authority, the treatment of disagreements between technical and commercial leadership, the legal terms of external advisory arrangements, customer-specific behavioural restrictions and documented outcomes of regulator or user challenges.
Chapter 6. Consultation or Legitimation? Institutional Representation, Conflicts of Interest, Accountability and the Boundaries of External Participation
Principal judgment: External philosophical, religious and civic consultation can materially improve frontier AI governance, but consultation becomes an institutionally legitimate process only when its mandate, representativeness, independence, decision rights and observable consequences can be examined. The publication of participant names, meeting records or statements of ethical commitment is insufficient to establish that external voices exercise meaningful authority. Conversely, the absence of binding powers does not make consultation worthless or inherently deceptive: advisory expertise can improve policy even when final responsibility properly remains with a legally accountable provider. The decisive distinction is between the contribution of knowledge, the conferral of legitimacy and the exercise of authority.
Consultation as an institutional relationship rather than a reputational event
The central governance weakness of external moral consultation is the frequent ambiguity surrounding its purpose. A laboratory may invite philosophers to examine a proposed constitutional principle, religious scholars to identify culturally inappropriate assumptions, civil-society organisations to discuss discrimination, or members of the public to express preferences about model behaviour. Each activity can generate useful information, but the legitimacy of the process depends on what participants were actually invited to do. An expert asked to review the clarity of a policy cannot reasonably be portrayed as having endorsed the organisation’s entire alignment framework. A religious representative who attends a discussion on AI and social responsibility has not necessarily consented to the commercial implementation of a particular theological interpretation. A public consultation designed to identify concerns does not confer a mandate to claim that the final model reflects the collective moral judgment of its participants.
These distinctions become particularly important because leading laboratories operate in an environment where ethical credibility has commercial and regulatory value. Demonstrating engagement with recognised intellectual figures can reassure users, customers and policymakers that the organisation is not treating moral alignment exclusively as an engineering problem. Such engagement may be sincere, technically valuable and reputationally beneficial simultaneously. It would therefore be analytically unsound to infer manipulation merely from the fact that a consultation improves a company’s public standing. The legitimate question is whether the institution’s public claims concerning consultation correspond to the rights, access and influence actually granted to participants.
A consultation process can be classified along three separate dimensions. Epistemic legitimacy concerns whether participants possess relevant knowledge and whether the process helps identify errors or neglected considerations. Procedural legitimacy concerns whether selection, deliberation, dissent and reporting follow fair and transparent rules. Decision-making legitimacy concerns whether the actors exercising final authority are entitled to make the relevant choices and are accountable for their consequences. These dimensions reinforce one another but are not interchangeable. A technically excellent expert panel can lack representative authority; a broadly representative consultation can produce poorly informed judgments; and a legally accountable public institution may still require specialised expertise before exercising its powers responsibly.
The legal and institutional meaning of independent advice
Independence cannot be assessed merely by examining whether participants are employees of the laboratory. External advisers may depend on the organisation for research funding, consulting remuneration, privileged technical access, publication opportunities or future collaborations. None of these relationships necessarily invalidates their contributions, but they create interests that should be disclosed and managed. A scholar who has been paid to advise a provider may still produce rigorous and critical work, while an unpaid participant may have ideological, organisational or reputational interests of their own. The objective of conflict-of-interest management is not to eliminate every relationship capable of influencing judgment, an unrealistic requirement, but to disclose material interests and ensure that conclusions can be challenged on their merits.
The institutional design of consultation should therefore specify who selected the participants, who defined the questions, which documents they were allowed to inspect, whether they could request additional evidence, whether dissenting conclusions could be published and whether the company was required to explain its response. These questions are especially important where the topic concerns the effect of alignment rules on politically or religiously contested speech. If a laboratory controls the entire agenda, supplies only selected evidence and retains discretion to describe the outcome publicly, external participants may contribute real expertise while the consultation remains incapable of independently validating the overall governance framework.
The problem is not unique to artificial intelligence. Public institutions regularly use advisory committees, technical standards bodies, consultations and expert hearings without transferring final legislative authority to participants. The difference lies in the public-law framework surrounding those processes. Where an authorised government body undertakes consultation, procedural requirements, judicial review, records-access rules or parliamentary accountability may apply, depending on the jurisdiction. A privately organised consultation generally lacks equivalent safeguards unless they are created contractually or through other enforceable arrangements. It follows that a government assessing the legitimacy of an AI laboratory’s consultation should ask not merely whether the process resembles public deliberation, but whether comparable accountability mechanisms exist.
Representation and the difficulty of selecting legitimate moral voices
The selection of religious and philosophical representatives creates a distinctive problem because moral traditions rarely have one universally recognised institutional spokesperson. Religious authority may be distributed among clergy, theologians, jurists, community institutions and individual believers, while philosophical expertise is organised around schools of thought and contested scholarly arguments rather than democratic representation. Consultation with eminent figures can improve conceptual sophistication, but prestige does not demonstrate that minority interpretations or dissenting members of a tradition have been adequately represented.
A further asymmetry emerges between traditions with strong international institutions and those organised locally or informally. A laboratory seeking representatives may naturally approach recognised universities, established religious organisations and well-known intellectual networks because these bodies are accessible, professionally organised and able to communicate in the languages used by development teams. This can produce an unintentional concentration of influence among traditions possessing established institutional channels. Communities whose moral knowledge is transmitted orally, through local practices or under restrictions on disclosure may be less likely to participate. The resulting representation problem cannot be solved simply by adding more participants from different countries, because geographic diversity does not necessarily capture differences in institutional authority, class, language, generation or religious interpretation.
The legitimacy of consultation should therefore be evaluated according to the specific claim made on its behalf. If a laboratory states that it consulted several experts on Christian theology, the relevant evidence concerns the identity, qualifications and advice of those experts. If it claims that its model respects religious diversity globally, the evidentiary burden is substantially greater and requires behavioural testing across traditions and contexts. If it suggests that a policy reflects humanity’s values, the claim requires a defensible account of population coverage, participation, weighting and disagreement. The broader the legitimacy claim, the more demanding the required evidence.
Public participation and the authority to reject its conclusions
OpenAI’s collective-alignment research offers a concrete example of the distinction between external participation and binding decision-making. Its August 2025 publication reports international preference collection, comparison with existing behavioural guidance and subsequent policy consideration. The company adopted some changes but also identified proposals that were deferred or not accepted. The documentary significance is that participation affected the policy-development process while the company retained a separate evaluative role, including consideration of safety and other constraints. This is an institutional design choice rather than an automatic defect. A company operating a broadly accessible system cannot necessarily implement every surveyed preference, especially if a proposal creates risks to children, privacy, political integrity or other protected interests. Collective Alignment: Public Input on Our Model Spec — OpenAI — August 2025.
Nevertheless, where a company reserves the right to reject external recommendations, legitimacy depends partly on whether rejection is reasoned and reviewable. A process that publishes disagreement, explains why certain proposals conflict with higher-level obligations and preserves the possibility of future reconsideration offers greater accountability than one that merely reports successful consultation. The relevant question is not whether a laboratory always follows the public, but whether it can demonstrate consistent principles for accepting or rejecting public advice.
This point becomes especially important when a consultation recommends more permissive behaviour in a contested area. A laboratory may reject the recommendation because of an identifiable legal obligation, evidence of serious harm, unresolved empirical uncertainty or a discretionary corporate preference. These are materially different justifications. If they are combined under a generic appeal to safety, external observers cannot determine whether the decision reflects enforceable law, proportionate risk management or an ethical choice that remains open to legitimate disagreement. Public consultation becomes more credible when providers preserve these distinctions.
Governance requirements for substantive external participation
| Governance requirement | Minimum credible evidence | Stronger institutional arrangement | Principal failure if absent |
|---|---|---|---|
| Defined mandate | Published questions and scope of consultation | Independently agreed terms of reference | Participants appear to endorse decisions outside their mandate |
| Representative selection | Selection criteria and acknowledged gaps | Independent nomination and affected-community participation | Prestigious voices substitute for relevant diversity |
| Conflict-of-interest disclosure | Relevant funding and professional relationships | Independent review of interests and recusal arrangements | Hidden dependence weakens confidence |
| Access to evidence | Policy texts and appropriate evaluation findings | Protected access to relevant technical records | Participants cannot assess implementation |
| Freedom to dissent | Documented minority positions | Right to publish reasoned disagreement | Apparent consensus conceals conflict |
| Institutional response | Record of recommendations and outcomes | Mandatory reasoned acceptance or rejection | Consultation has unobservable consequences |
| Behavioural verification | Tests associated with adopted recommendations | Independent cross-version evaluation | Policy changes remain rhetorical |
| Continuing review | Periodic engagement and revision records | Permanent, reviewable advisory mandate | Consultation becomes obsolete after deployment |
| Public accountability | Accurate description of participant roles | Independent oversight of claims made about consultation | Advisory participation is overstated as democratic consent |
The table distinguishes evidence that a consultation took place from evidence that it exercised meaningful governance influence. It also recognises that different arrangements may be appropriate depending on the decision involved. An advisory group reviewing terminology does not require the same procedural architecture as an institution empowered to decide restrictions affecting political expression or access to public services. Proportionality should be determined by the consequences of the policy, the rights affected and the scope of the deployment.
Consultation capture and the risk of manufactured consensus
Consultation capture occurs when the procedure is designed or administered in ways that systematically privilege the interests of the institution seeking advice. In AI governance, possible mechanisms include the selection of participants already broadly supportive of the provider’s approach, narrow framing of questions, withholding relevant technical evidence, presenting only preselected alternatives and describing disagreement as consensus in public communications. These mechanisms are analytically identifiable, but their existence in a specific consultation cannot be asserted without documentary evidence. The distinction is essential: the structural possibility of capture is not proof of misconduct.
A subtler problem arises when participants are genuinely independent but the institution controls the translation of their conclusions into technical requirements. A panel may reach broad agreement that an assistant should respect freedom of conscience, but the provider must still determine how that principle applies to requests involving religious persuasion, interpersonal relationships, political mobilisation and contested medical decisions. If the resulting implementation is not subjected to review by the original participants or independent evaluators, the public cannot establish whether the laboratory preserved the intended meaning. The authority to interpret advice can therefore be as consequential as the authority to accept it.
The most effective safeguard is not to require unanimity among external participants. Moral and political disagreements may be irreducible, and suppressing dissent to produce a polished statement would undermine the very pluralism consultation seeks to protect. A more credible procedure records competing interpretations, identifies unresolved questions and explains how the provider or public authority selected an operational rule. Such a process can legitimately conclude that further evidence is necessary or that a question should remain open to user-level choice, rather than forcing every disagreement into an artificial institutional consensus.
The significance of public governance experience
The Paris AI Action Summit offers a relevant example of broader institutional consultation operating outside the proprietary governance of a particular model. The co-chairs’ statement on international AI governance, published on 11 February 2025, records a preparatory working group involving 29 states, six international organisations, seven technology companies and ten civil-society organisations over seven months. The process sought to identify areas of agreement and outstanding governance needs, ranging from standards to targeted public policy. These figures describe participation in a governmental and international policy exercise, not control over any frontier laboratory’s model constitution. Their importance is that they demonstrate the feasibility of organising structured international discussions involving governments, industry and civil society without treating one private developer as the sole convener of normative debate. Co-Chairs’ Statement on International Artificial Intelligence Governance — Élysée — February 2025.
The institutional limitation remains substantial. International summit statements generally express policy positions and areas of cooperation; they do not automatically create binding legal duties, establish independent audit powers or determine how an individual model should respond to a disputed ethical question. Their value lies in agenda setting, coordination and the development of shared governance concepts. For these concepts to constrain laboratories, they must be connected to operative legal instruments, standards, procurement requirements or other enforceable arrangements.
Legitimacy without surrendering operational responsibility
A defensible consultation system must avoid two opposite errors. The first is to allow companies to claim broad moral legitimacy from advisory exercises that provide little influence over final decisions. The second is to assume that all binding behavioural policies should be determined by ad hoc external panels regardless of technical competence, legal responsibility or consequences. A laboratory remains responsible for the performance and safety of products it develops, while competent public authorities retain responsibility for applicable legal constraints. External experts contribute knowledge and critical scrutiny; they should not be transformed into an unaccountable substitute for either corporate responsibility or public law.
The appropriate institutional arrangement depends on the type of issue. Expert advice may be sufficient when evaluating the accuracy of an ethical concept. Representative participation may be necessary when choosing among legitimate public-service defaults. Judicial or regulatory authority may be required when a restriction implicates legally protected rights. Independent technical evaluation becomes essential when a policy’s effectiveness is disputed. The legitimacy of plural governance arises from allocating these functions appropriately, not from requiring one advisory institution to exercise every kind of authority.
Key judgments
External consultation is most valuable when its intellectual contribution can be distinguished from claims of political representation or legal authority. Its credibility depends on the visibility of participant selection, independence, dissent, access to relevant evidence and the consequences of recommendations. A consultation can be sincere and useful without being democratically authoritative; equally, it can provide reputational value while preserving all decisive powers inside the laboratory.
What would change the assessment
The assessment would change if providers published comprehensive recommendation-disposition records, accepted independent review of public claims concerning consultation or established advisory bodies with clearly defined powers to require reassessment of consequential behavioural policies. Evidence that consultation outcomes consistently diverge from announced implementation without adequate explanation would strengthen concerns about legitimacy.
Open official record
The decisive missing information concerns participant mandates, compensation and conflicts of interest, the full range of dissenting recommendations, post-consultation implementation records, and independent evaluation of whether the resulting policy reflects the expertise originally provided.
Chapter 7. The Geopolitics of Moral Infrastructure: United States, China, Cultural Export and Competing Models of AI Governance
Principal judgment: Frontier AI is becoming an instrument of international normative influence because the rules governing model behaviour can travel across national borders through commercial services, software integration, public-sector procurement and the distribution of model weights. The United States and China provide particularly consequential but institutionally different models of this process. American frontier laboratories operate within a system where private organisations retain substantial discretion over model alignment, subject to applicable legal and regulatory constraints, while China’s regulatory framework explicitly incorporates state-defined political and social requirements into the provision of public generative AI services. The resulting geopolitical competition is not simply between different technical models: it concerns which institutions possess authority to determine acceptable information, legitimate expression and the relationship between individual preferences, public order and political power. Neither framework can be reduced to a homogeneous national morality, and neither automatically determines how every model behaves in practice.
Moral infrastructure as a component of international technological influence
The international significance of AI alignment arises from the separation between the jurisdiction in which a model is developed and the societies in which its behaviour is encountered. A model trained and governed principally within one national institutional environment may be deployed through commercial applications in countries possessing different constitutional traditions, religious practices, political institutions and expectations concerning personal autonomy. Its technical capabilities may make it useful across those environments, while its default behavioural rules remain comparatively standardised. The resulting exposure does not require the provider to pursue an explicit programme of cultural influence. It can emerge through the ordinary expansion of internationally distributed technology services.
This mechanism resembles other forms of technological standardisation in one respect: decisions made by organisations controlling widely adopted infrastructure can shape the options available to downstream users. Yet normative model behaviour differs from conventional interoperability standards because its consequences are interpretive rather than merely functional. A communication protocol determines how systems exchange information; an AI behavioural policy can also influence how information is explained, which kinds of advice are considered appropriate and how conflicts among values are presented. The distinction matters especially when users treat fluent model outputs as neutral syntheses rather than as responses produced under institutionally selected constraints.
The relevant concept is cognitive sovereignty, defined here as the practical capacity of individuals and legitimate institutions to obtain information, assess competing claims and make decisions without being subject to opaque and unaccountable external control over the conditions of their deliberation. This concept should not be confused with a state’s unrestricted authority to control what its citizens may think or access. Government censorship, politically mandated distortion and restrictions on lawful pluralism can threaten cognitive sovereignty as seriously as excessive private concentration. A defensible conception must therefore protect institutional independence, individual freedom of conscience, access to reliable information and the ability to challenge both corporate and governmental interference.
The geopolitical consequences depend on three distinct forms of dependence. Technological dependence arises where states and enterprises lack competitive alternatives to imported models or infrastructures. Regulatory dependence occurs where domestic institutions cannot effectively enforce their own legal obligations against external providers. Normative dependence arises where public and private organisations adopt externally designed behavioural standards without examining their compatibility with local rights, laws and legitimate social practices. The three forms can reinforce one another, but they are not identical. A country may use an imported model while maintaining effective regulatory supervision, or develop domestic models that nevertheless reproduce restrictive political assumptions.
The United States: private innovation and contested public accountability
The American position is distinguished by the importance of privately developed frontier systems and the central role of company-authored behavioural frameworks. OpenAI’s published Model Spec illustrates a provider-defined instruction architecture, while Anthropic’s constitutional approach demonstrates how an organisation can articulate broad normative commitments and incorporate them into training and evaluation. These initiatives are significant because they make some decisions visible that might otherwise remain embedded in private development processes. However, publication of a normative framework is not equivalent to public authorisation of its contents, and voluntary consultation does not automatically establish enforceable rights of external review. OpenAI Model Spec — OpenAI — October 2025. Claude’s Constitution — Anthropic — January 2026.
The American governance environment should not be presented as one in which technology companies operate outside the law. Privacy, consumer protection, civil rights, intellectual property, competition and sector-specific requirements can constrain AI-related conduct, depending on the circumstances. The more precise institutional observation is that a comprehensive, uniform public procedure for authorising the moral content of all general-purpose model responses is not established by the company alignment documents examined here. Providers therefore retain considerable responsibility and discretion over the construction of behavioural defaults, while the legality of particular conduct remains subject to applicable legal frameworks.
This allocation creates an enduring tension between innovation and legitimacy. Private laboratories can revise policies and deploy improvements without the delays associated with public legislative processes. They can also coordinate technical safety measures across products and react quickly to newly identified failure modes. Conversely, rapid unilateral revision can leave affected individuals and institutions uncertain about why behaviour has changed, what legal or ethical considerations determined the change and whether an alternative configuration is available. The central problem is not that every change should require legislative approval, but that significant restrictions affecting lawful expression or institutional autonomy should be sufficiently documented and contestable.
A further difficulty concerns the international transfer of American corporate policy. A restriction adopted by a US-based provider for legal, safety or reputational reasons may affect users in jurisdictions where the underlying issue is governed differently. The provider may have valid commercial reasons for maintaining a globally consistent rule, including the cost of jurisdiction-specific enforcement and the risk that apparently local restrictions can be circumvented. Nevertheless, uniformity introduces normative consequences when the rule concerns legally permissible differences in political debate, religion, family responsibilities or professional practices. For foreign governments, the appropriate response is not to demand unconditional national control over model outputs, but to distinguish lawful local requirements from the provider’s discretionary global standards and assess whether the latter unnecessarily constrain public functions.
China: state-defined political obligations in generative AI governance
China’s framework provides a documented contrast because normative requirements are explicitly incorporated into state regulation of generative AI services. The Interim Measures for the Management of Generative Artificial Intelligence Services, promulgated in July 2023 and effective from 15 August 2023, were issued jointly through seven national authorities. Article 2 identifies their application to services providing generated text, images, audio, video and other content to the public within China, subject to the instrument’s stated scope. Article 3 combines development, security, innovation and classified or differentiated supervision. Article 4 requires service provision and use to comply with laws and regulations, respect social morality and ethics, and adhere to specified political and social requirements. Interim Measures for the Management of Generative Artificial Intelligence Services — Cyberspace Administration of China and Six Other Authorities — July 2023.
The most significant provision for the present assessment is Article 4’s requirement to uphold the socialist core values, together with prohibitions concerning specified categories of content, including content understood under Chinese law to threaten state power, national unity, national security or social stability. The same article also addresses discrimination, intellectual property, personal rights and the accuracy and reliability of generated information. These provisions must be read together rather than selectively. The regulation combines explicit political requirements with other governance objectives that also appear, in different institutional forms, in international AI regulation. Its distinctive characteristic is the direct statutory integration of state-defined political values into the framework governing public generative services.
This distinction is not merely rhetorical. In the American company-led model, provider-defined behavioural restrictions may be shaped by commercial and legal pressures but are not automatically equivalent to a single codified national political doctrine. In China’s framework, compliance with specified state values is expressly part of the regulatory obligation. The practical effect can be to increase the importance of political conformity in training, evaluation, content controls and service design. However, the public regulations alone do not prove that every Chinese model implements these requirements identically, that enforcement is uniform across providers or that all model outputs conform to official expectations. Such claims require model-specific testing and evidence concerning enforcement practice.
China’s 2025 Artificial Intelligence Safety Governance Framework 2.0, published under the guidance of the Cyberspace Administration of China and developed through relevant technical and research bodies, further illustrates the institutional emphasis on systematic risk classification and governance measures. The official publication describes updates concerning risk categories, approaches to risk grading and preventive controls, while linking the work to China’s broader international AI governance initiatives. This demonstrates continuing development of a domestic governance architecture rather than reliance solely on the original 2023 generative AI measures. Artificial Intelligence Safety Governance Framework 2.0 — Chinese Cyberspace Authorities — September 2025.
The international consequences are more complicated than an assumption that Chinese AI exports necessarily reproduce Chinese domestic restrictions without modification. A company distributing models internationally may face different legal obligations, commercial incentives and deployment arrangements. Open-weight models may be adapted by downstream developers, while centrally hosted services can retain stronger provider control over system instructions and content moderation. Exported technology therefore carries varying degrees of normative portability depending on architecture and deployment. The relevant empirical question is whether particular restrictions persist across local, international and independently modified deployments, and whether they can be changed without impairing technical performance.
Comparative institutional models
| Dimension | United States — provider-led frontier development | China — state-directed regulatory requirements | Strategic consequence |
|---|---|---|---|
| Principal source of behavioural policy | Company specifications, training policies and applicable law | Provider policies within explicitly stated national regulatory requirements | Different relationships between private discretion and political authority |
| Political values | Corporate approaches vary; no single company specification is a national constitution | Socialist core values expressly incorporated into the 2023 measures | Different formal sources of normative authority |
| Public consultation | Voluntary company programmes and other public processes | Participation and governance occur within state-defined institutional requirements | Consultation does not imply identical decision rights |
| Regulatory control | Multiple applicable legal and sectoral mechanisms | Explicit generative-service regulation and cybersecurity governance | Different enforcement and compliance structures |
| International deployment | Provider policies can be exported through global platforms | Domestic requirements may interact with international products and adaptations | Model behaviour must be tested across jurisdictions |
| User configurability | Depends on provider and deployment | Depends on service design and applicable restrictions | Formal control and practical configuration may diverge |
| Political-expression exposure | Disputed private moderation and legal restrictions | Expressly defined political and national-security content restrictions | Distinct risks to pluralism and freedom of expression |
| Primary accountability question | How can private normative discretion be externally constrained? | How can state-directed normative controls be assessed against rights and pluralism? | Neither corporate nor state control guarantees legitimacy |
The comparison is deliberately institutional rather than ideological. Both systems can incorporate safety rules, technical evaluations and mechanisms intended to reduce discrimination. Both can generate conflicts between lawful conduct, public protection and model utility. Their difference lies principally in the location of final normative authority and the mechanisms through which contested political values become enforceable requirements.
The European Union as a third governance model
The European Union represents a different institutional approach because its primary contribution is not the establishment of a single European moral specification for every frontier model. Rather, it seeks to govern AI through legally articulated obligations concerning safety, fundamental rights, transparency, provider responsibilities and market supervision. The AI Act’s requirements vary by the classification of models and systems, and its treatment of general-purpose AI is distinct from the requirements applicable to particular high-risk deployments. This creates a framework in which public law can constrain corporate conduct without attempting to determine the ethical answer to every question a general-purpose assistant might encounter. Regulation (EU) 2024/1689 — European Union — Consolidated July 2026.
The European approach also creates a tension between the harmonisation of legally enforceable requirements and the preservation of legitimate cultural variation among member states. The Union contains different constitutional traditions, languages, religious histories and approaches to the relationship between public institutions and religion. A regulatory framework that protects fundamental rights can establish common boundaries, but it does not automatically settle how models should present every ethically contested topic in Italian, French, German or other national contexts. The ability to preserve pluralism within a common legal order consequently becomes a strategic advantage only if implementation mechanisms are sufficiently sensitive to linguistic, institutional and cultural differences.
Europe’s position also illustrates the difference between regulatory influence and technological sovereignty. A jurisdiction may possess substantial capacity to regulate AI services offered in its market while remaining dependent on models developed elsewhere. The resulting governance leverage is real but incomplete. Regulators can impose obligations and demand compliance within their competence, yet they may lack direct control over model architecture, training priorities and international deployment decisions. The strategic challenge is to combine market regulation with independent evaluation capability, institutional expertise and credible alternatives for public-sector procurement.
Open models, adaptation and the limits of normative export
The availability of modifiable model weights can change the distribution of practical control by allowing downstream actors to fine-tune or otherwise adapt model behaviour. This may reduce dependence on a single provider’s system-level restrictions and permit greater responsiveness to local languages or institutional requirements. However, modification rights do not automatically establish accountability. A downstream developer may reproduce the original model’s tendencies, introduce new discriminatory restrictions or reduce safety protections. Open technical access creates opportunities for pluralism and independent testing, but the legitimacy of the resulting configurations still depends on the institutions deploying them.
The European AI Act itself recognises distinctions involving free and open-source general-purpose models, including qualified exemptions from certain obligations under Article 53, while retaining specific treatment for models presenting systemic risk. This demonstrates that regulatory architecture must distinguish between the distribution of model weights and the risk or responsibility associated with deployment. Regulation (EU) 2024/1689, Article 53 — European Union — Consolidated July 2026.
A particularly important consequence is that the geopolitical origin of a model does not, by itself, determine the morality of every application built upon it. A Chinese-origin open-weight model deployed locally by a European institution may operate under European legal obligations and additional locally defined instructions. An American-origin API service may retain more extensive upstream behavioural control. Conversely, a domestically developed European model may embed poorly examined normative assumptions. Model provenance matters, but architecture, governance and deployment control are equally important.
Strategic pathways and consequences for international order
The first plausible trajectory is a continuation of concentration around a limited number of internationally important providers, with their behavioural specifications becoming increasingly influential through ordinary commercial adoption. The second is regional differentiation, in which states and major markets impose divergent legal requirements, leading providers to maintain jurisdiction-specific policies and increasing the complexity of international AI services. The third is a more plural technical environment, supported by open models, independent evaluation and institutionally authorised configurations. These pathways can coexist, and their relative importance cannot responsibly be assigned numerical probabilities without suitable empirical foundations.
The immediate strategic significance lies in the interaction between normative governance and industrial dependency. Countries seeking to preserve autonomy over education, public administration, healthcare and other sensitive services should not evaluate model procurement solely through accuracy, latency, cost and cybersecurity. They must also examine policy transparency, ability to accommodate lawful local requirements, safeguards against political manipulation and practical means of replacing or auditing the provider. Such requirements can reduce unexamined normative dependence without requiring governments to dictate citizens’ personal ethical convictions.
Key judgments
The United States and China demonstrate different institutional routes through which normative priorities can become model behaviour: provider-led alignment subject to applicable law, and state-directed political obligations embedded in generative-service regulation. The European Union offers a third approach centred on enforceable risk and rights obligations rather than one comprehensive public moral code. The principal geopolitical exposure is the international diffusion of behavioural defaults through technological dependencies that may be difficult for downstream institutions to inspect or modify.
What would change the assessment
Independent comparisons of the same models across jurisdictions, hosting configurations and local adaptations would clarify the persistence of national or corporate normative restrictions. Documented government requirements imposed on exported models, enforceable international audit arrangements or significant changes in the portability of alignment policies would materially alter the strategic balance.
Open official record
Important gaps include comparable cross-jurisdictional behavioural evaluations, provider-specific records concerning compliance with local content requirements, the extent of independent control over modified models, and procurement data revealing how public institutions manage imported behavioural specifications.
Chapter 8. European Strategic Exposure: European Union Governance and the Distinct Positions of Italy, France, Germany and the United Kingdom
Principal judgment: Europe possesses substantial legal and institutional instruments for constraining AI-related risks, but its capacity to govern the normative behaviour of frontier systems remains unevenly distributed across jurisdictions, regulators and deploying organisations. The European Union has established a harmonised regulatory framework covering specified AI practices and general-purpose model obligations, while Italy, France and Germany contribute different national institutions and policy priorities. The United Kingdom, outside the EU legal order, has pursued a more sector-sensitive regulatory approach combined with specialised frontier-model evaluation capabilities. None of these arrangements should be confused with an established system of public authorisation over all ethical instructions embedded in widely deployed AI. The European strategic challenge is to convert legal authority, independent technical capability and procurement leverage into practical accountability without suppressing legitimate philosophical, religious and cultural pluralism.
The European Union: legal harmonisation without a universal moral constitution
The European Union approaches AI governance from a distinctive constitutional and regulatory position. Its institutions can impose binding obligations on economic operators within the scope of Union law, including providers established outside the EU where the relevant territorial conditions are met. This capacity provides leverage over internationally developed AI systems without requiring the Union to own the underlying models. However, the European regulatory project is not equivalent to writing a comprehensive ethical constitution for general-purpose assistants. The AI Act establishes a risk-based structure, prohibits specified practices, creates obligations for high-risk systems and regulates general-purpose AI models through differentiated requirements. Its objective is to establish harmonised conditions for AI development and deployment while protecting fundamental rights, health, safety and other recognised interests. Regulation (EU) 2024/1689 — European Parliament and Council — July 2024, Consolidated July 2026.
The distinction matters because the regulation’s categories do not correspond directly to the moral questions that may arise during an ordinary conversation. An assistant discussing family obligations or religious ethics may not be a high-risk system merely because the topic is sensitive. Conversely, an AI system used in a legally specified high-risk context may be subject to demanding obligations even if its apparent conversational behaviour is restrained and uncontroversial. The regulatory consequences depend on the system’s intended purpose, deployment and legal classification, rather than on a general judgment that all ethical questions are equally hazardous.
For general-purpose AI models, Article 53 establishes technical documentation and information requirements, among other obligations. Article 55 provides additional duties for models with systemic risk, while Articles 91–93 establish important supervisory powers. These mechanisms can support investigation of model design and risk management, but they do not automatically grant every user a legal right to inspect the model’s entire normative training history. Nor do they impose a general obligation on providers to accommodate all religious or philosophical interpretations. The practical value of the Act for moral governance therefore depends on identifying where a normative failure falls within an existing legal obligation and where additional institutional instruments may be necessary.
The regulation also establishes an important distinction between public and confidential information. Certain documentation is intended for competent authorities or downstream providers rather than unrestricted public disclosure. This is relevant because detailed alignment records may contain security-sensitive material, personal data or commercially protected information. A credible European governance architecture can require accountability without publishing every technical detail. It must nevertheless ensure that confidentiality does not prevent competent authorities from evaluating legally consequential behaviour or affected individuals from obtaining the explanations and remedies available under applicable law.
The 2026 legislative position and the importance of temporal precision
The original AI Act entered into force in August 2024 and established phased implementation. By the October 2026 assessment date, its regulatory architecture had undergone amendments affecting aspects of implementation and timing. The consolidated text dated 27 July 2026 must therefore be distinguished from the original 2024 instrument when determining which requirements apply at a particular date. The updated EU summary identifies, among other provisions, the application of general-purpose AI obligations from 2 August 2025 and revised implementation dates for categories of high-risk systems. The relevant current record should be consulted rather than assuming that every original date remains unchanged. Rules for Trustworthy Artificial Intelligence in the EU — EUR-Lex — Updated Legislative Summary.
This distinction has consequences for policymakers assessing institutional readiness. A legal obligation that has entered into application is different from one whose future compliance date has not yet arrived. Likewise, the existence of statutory supervisory powers does not establish the number of inspections completed, the proportion of providers fully compliant or the effectiveness of enforcement. Those empirical outcomes require separate administrative records. The strategic assessment must therefore distinguish legal capacity, implementation arrangements and demonstrated enforcement.
The EU’s most important potential contribution to moral governance is the creation of a legal environment in which certain provider decisions can be evaluated through public institutions rather than solely through corporate discretion. Its limitation is that many contested ethical questions remain outside a simple compliance test. Whether a model treats a minority religious view fairly, presents family obligations without stereotyping or avoids unnecessary paternalism may implicate fundamental rights in particular circumstances, but it does not follow that every unsatisfactory answer is a violation of the AI Act. The appropriate institutional response must combine existing legal remedies with technical evaluation and governance mechanisms proportionate to the significance of the behaviour.
Italy: anthropocentric AI governance and the challenge of institutional implementation
Italy’s position became more formally defined through Law No. 132 of 23 September 2025, published in the Gazzetta Ufficiale on 25 September and effective from 10 October 2025. The legislation establishes national provisions and governmental delegations concerning AI research, experimentation, development, adoption and application. Article 1 describes an approach centred on correct, transparent and responsible use of AI within an anthropocentric framework, while expressly providing that the law is to be interpreted and applied consistently with Regulation (EU) 2024/1689. This is significant because it positions Italy’s national AI governance within the Union legal order rather than establishing an independent and potentially conflicting general regime. Law No. 132 of 23 September 2025 — Italian Republic — Consolidated 2026.
For the governance of model morality, Italy’s challenge is to transform anthropocentric principles into requirements capable of operating within public institutions. An emphasis on the human person, autonomy and fundamental rights provides a normative orientation, but it does not by itself establish how public administrators should evaluate a model’s handling of culturally or religiously contested issues. The implementation problem is therefore institutional: public bodies require procurement criteria, human oversight, appeal procedures and appropriate technical competence to distinguish the model’s advisory role from the legally responsible decision-maker.
This distinction becomes important in administrative and judicial contexts. A system used to summarise legal materials or assist public employees may reproduce normative assumptions concerning fairness, family responsibilities, vulnerability or social obligations. The fact that a response is fluent and apparently impartial does not make it legally authoritative. Public institutions should maintain identifiable human responsibility for consequential decisions and ensure that model outputs can be checked against current Italian and European law. This is particularly important where the distinction between an ethical view and a legally enforceable right is not obvious to the user.
Italy also presents a distinctive cultural-governance challenge because of the interaction among secular constitutional authority, religious traditions, local institutions and contemporary social pluralism. A model serving Italian users may need to explain Catholic ethical thought, secular moral philosophy, minority religious perspectives and applicable civil law without treating any one of these as automatically controlling the others. In a public-service context, legal obligations and equality protections take precedence over a provider’s discretionary preference for a particular moral framework. In a personal advisory context, the model may properly explain recognised interpretations while preserving the user’s freedom of conscience.
The presence of religious traditions in national cultural life does not justify using the state to impose one religious interpretation through AI services. Equally, constitutional neutrality does not require models to erase religion from ethical discussion. The relevant objective is institutional competence: a public AI system must recognise when religion is a subject of information, when a user voluntarily invokes a religious commitment and when public law establishes the boundaries of legitimate action.
Italy’s practical governance priorities
| Area | Established institutional basis | Normative exposure | Required implementation capability |
|---|---|---|---|
| Public administration | National AI legislation and applicable EU law | Provider-defined defaults may influence official explanations | Human review, legal validation and procurement conditions |
| Judicial and legal support | Existing legal institutions and applicable AI obligations | Confusion between model interpretation and authoritative law | Source verification, role restrictions and professional accountability |
| Healthcare | Sectoral legal duties, professional responsibility and AI requirements where applicable | Conflict between autonomy, medical advice and family or religious preferences | Clear clinical authority, informed consent and escalation procedures |
| Education | National educational responsibilities and relevant legal protections | Privately selected norms may affect discussion of contested issues | Transparent pedagogical policy and teacher oversight |
| Cultural and religious representation | Constitutional rights and equality protections | Overgeneralisation of majority or minority traditions | Contextual evaluation and accurate distinction between doctrine and law |
| National procurement | Public purchasing authority and applicable procurement rules | Dependency on opaque provider policies | Contractual access, version control and provider-switching arrangements |
The table identifies policy requirements that follow from the institutional setting; it should not be read as evidence that every listed capability has already been uniformly implemented across Italian administrations.
Italy’s comparative opportunity lies in developing public-sector methods for evaluating lawful cultural and ethical pluralism without attempting to determine a universal national morality. Such methods could be adapted to other European jurisdictions and would be particularly valuable where foreign-developed foundation models are incorporated into services for which Italian institutions retain legal responsibility.
France: strategic autonomy, republican institutions and independent technical scrutiny
France combines a strong national interest in technological sovereignty with an institutional tradition emphasising republican public authority, equality and the protection of fundamental rights. In AI governance, these considerations intersect with industrial development, public administration, data protection and international diplomacy. The Paris AI Action Summit of February 2025 represented an important expression of this broader strategic ambition. France hosted discussions involving participants from more than 100 countries, while the summit’s published statements placed emphasis on inclusive AI, international cooperation, innovation, public-interest objectives and governance mechanisms. Statement on Inclusive and Sustainable Artificial Intelligence for People and the Planet — Élysée — February 2025.
The summit demonstrates France’s ability to convene governments, companies and international institutions around AI governance. It does not establish that the resulting participants acquired authority over model-level moral policies. The distinction is important because diplomatic consensus and enforceable regulation operate through different mechanisms. An international statement may express support for inclusion or respect for cultural diversity, but the operational question remains whether a French public body can inspect a model’s behaviour, demand correction of a legally consequential failure or require providers to document restrictions affecting a public service.
France also possesses a significant institutional resource in the Commission nationale de l’informatique et des libertés, whose work on AI and data protection addresses the development of systems using personal data. On 22 July 2025, the CNIL published further recommendations concerning the application of data-protection rules to AI models, model security and the annotation of training data. Its guidance recognises that models trained on personal data may remain subject to GDPR obligations depending on their characteristics, including the possibility of memorisation. These matters are relevant to normative governance because personal information, cultural characteristics and sensitive social categories can influence training and model behaviour, even though data protection and moral alignment are not identical legal domains. AI: The CNIL Finalises Its Recommendations on the Development of Artificial Intelligence Systems — CNIL — July 2025.
France’s distinctive challenge lies in preventing the pursuit of technological autonomy from being confused with the creation of a state-authorised moral orthodoxy. Domestic model development may reduce reliance on external providers and improve the ability of national institutions to negotiate technical requirements, but French ownership of a model does not automatically guarantee impartiality, pluralism or respect for dissent. The same transparency and contestability standards should apply to domestic and imported technologies. Otherwise, strategic sovereignty could replace dependence on foreign companies with insufficiently examined domestic control.
The relationship between republican neutrality and religious expression is especially relevant to public-sector deployments. The French constitutional tradition of laïcité concerns the organisation of public authority and freedom of conscience; it should not be mechanically converted into a requirement that AI models treat religious viewpoints as irrelevant to every discussion. A public administration must comply with applicable rules of neutrality, while an assistant explaining religious ethics to a private user can legitimately discuss competing theological positions. The central design question is whether the model distinguishes the legal position of a public institution from the personal beliefs of the individual seeking information.
France therefore has two complementary governance priorities: ensuring that public institutions retain control over legally consequential AI deployments, and developing independent evaluation capacity capable of distinguishing model accuracy, lawful neutrality and the provider’s own normative preferences. The former requires administrative responsibility and procurement policy; the latter requires multidisciplinary testing, including legal, linguistic and cultural expertise.
Germany: legal certainty, federal implementation and the regulation of public trust
Germany’s institutional position is characterised by the importance of legally defined administrative competence, fundamental-rights protection, technical standards and the need to coordinate national implementation with European requirements. The German approach is particularly relevant because it illustrates how a member state can organise domestic supervisory capacity without claiming general authority to rewrite the normative policies of all frontier models.
A material development occurred on 29 July 2026, when Germany’s Federal Network Agency, the Bundesnetzagentur, announced its central role in implementing the European AI regulatory framework under the national legislation concerning market surveillance and innovation promotion in artificial intelligence. According to the agency, the relevant law entered into force that day, assigning it functions including market surveillance, a contact point and a complaints role within the German implementation architecture. This provides a concrete institutional route through which certain AI compliance matters can be addressed by a public authority rather than remaining exclusively within vendor-controlled reporting systems. Bundesnetzagentur Assumes a Central Role in Implementing the AI Regulation — Bundesnetzagentur — July 2026.
The significance for moral governance is procedural rather than theological or philosophical. A complaint mechanism can help identify legally relevant failures, but the regulator’s competence must be defined by the applicable legislation. It would be incorrect to assume that an administrative authority responsible for AI market supervision automatically acquires power to determine the correct moral position on disputed questions. Its role is to enforce relevant obligations, examine compliance and exercise statutory powers. This separation is essential to maintaining legal certainty.
Germany’s constitutional context also creates particular sensitivity to the treatment of human dignity, freedom of expression, religious liberty and informational self-determination. These principles can establish legal boundaries for public authority and certain private conduct, but they do not necessarily produce one predetermined response to every ethically contested prompt. A model used in public services must be evaluated in relation to the actual rights and duties applicable to its deployment. A model used in private discussion may permissibly explain positions that the state itself would not be entitled to endorse or impose.
The country’s federal administrative structure introduces an additional implementation challenge. AI applications may be deployed by institutions operating at different levels of government and under different sectoral responsibilities. Harmonised European regulation reduces some fragmentation, but it does not eliminate the need for coordinated technical procurement, consistent interpretation of legal requirements and clear complaint routes. A citizen encountering an AI-related failure should not have to reconstruct a complex chain of providers, public agencies and contractual intermediaries merely to determine who is responsible for the service.
Germany’s institutional exposure
The strongest potential contribution of the German framework is the development of auditable, legally precise procedures that can be integrated into procurement, technical standards and regulatory enforcement. Public agencies can require that model outputs remain reviewable, that material errors be documented and that administrative decisions retain an identifiable legal basis. These requirements offer an alternative to attempting to control every ethical judgment at the foundation-model level. They focus on the responsibility of the institution deploying the system and on its ability to demonstrate compliance with public law.
The limitation is that the effectiveness of these procedures depends on access to information and technical competence. A regulator may receive a complaint about a system that produces inconsistent advice across languages or social groups, but determining whether the discrepancy results from training, deployment configuration or contextual factors may require specialised testing. The division of responsibilities among providers, deployers and authorities must consequently be supported by practical mechanisms for evidence preservation, technical investigation and corrective action.
United Kingdom: specialised frontier evaluation and sector-sensitive governance
The United Kingdom occupies a distinct position because it is outside the European Union’s AI Act framework and has developed a regulatory policy based on cross-sector principles and the responsibilities of existing regulatory institutions. The government’s March 2023 white paper, AI Regulation: A Pro-Innovation Approach, proposed a context-sensitive framework intended to support innovation while addressing safety, fairness, accountability, transparency and contestability. Its February 2024 response continued the development of this approach. These documents establish an important policy trajectory, but they must be identified as policy proposals and governmental positions rather than treated as proof that every proposed mechanism became binding legislation. AI Regulation: A Pro-Innovation Approach — UK Department for Science, Innovation and Technology — March 2023. Government Response to the AI Regulation Consultation — UK Department for Science, Innovation and Technology — February 2024.
The relevance of the British approach to moral instruction lies in its emphasis on the context in which AI is used. A general-purpose model may generate ethically sensitive text in many settings, but the legal and institutional consequences differ substantially when the system is deployed for casual conversation, professional advice, regulated financial activity or public administration. Sector-sensitive governance can address these differences without requiring a single central body to approve every normative response. The corresponding risk is fragmentation: where responsibilities are dispersed, users and affected communities may struggle to determine which regulator has jurisdiction over a systemic behavioural problem that crosses multiple sectors.
The United Kingdom’s development of specialised AI safety and security evaluation capacity is also strategically important. Independent technical assessments can provide public institutions with evidence about model capabilities and risks rather than relying exclusively on provider-reported benchmarks. For moral governance, however, technical evaluation must extend beyond conventional safety scenarios if it is to address questions concerning cultural bias, discriminatory refusals or the presentation of contested ethical positions. A system might perform well on cybersecurity or misuse evaluations while remaining inconsistent in its treatment of legitimate philosophical disagreement. These are different questions requiring different test designs.
The British institutional challenge is therefore to connect evaluation capability with legal and administrative authority. A research institution may identify behaviour that raises a public-interest concern, but the ability to compel corrective measures depends on the applicable regulator, statute or contractual relationship. Conversely, a sectoral regulator may possess legal authority but lack the technical expertise to evaluate complex model behaviour independently. The quality of the British framework will depend partly on whether information and competence can move effectively between these institutions.
The European comparison: four national approaches within two legal structures
| Dimension | Italy | France | Germany | United Kingdom |
|---|---|---|---|---|
| Principal legal architecture | EU AI Act plus Law 132/2025 | EU AI Act plus national and EU sectoral law | EU AI Act plus national implementation legislation | Domestic sector-sensitive regulatory framework |
| Distinctive institutional emphasis | Anthropocentric principles and national implementation | Technological sovereignty, public-interest governance and data protection | Legal certainty, market supervision and regulatory coordination | Context-based supervision and frontier technical evaluation |
| Verified reference point | Law 132/2025, effective 10 October 2025 | CNIL AI recommendations, 22 July 2025 | Bundesnetzagentur implementation announcement, 29 July 2026 | AI regulation white paper, March 2023; response, February 2024 |
| Normative governance exposure | Translation of rights and human-centred principles into administrative practice | Distinguishing republican neutrality from provider-imposed ethical defaults | Maintaining reviewability across complex public and private deployments | Coordinating sectoral authority over general-purpose model behaviour |
| Main implementation dependency | Public-sector technical competence and accountable procurement | Independent evaluation and enforceable deployment controls | Regulatory expertise and clearly allocated responsibilities | Coordination between evaluators, regulators and deploying bodies |
| Potential strategic contribution | Public-service methods for ethical and cultural pluralism | International governance convening and technical autonomy | Auditable compliance and enforceable administrative procedures | Advanced evaluation and context-sensitive supervision |
| Principal unresolved question | Can anthropocentric principles be translated into measurable public accountability? | Can sovereignty and pluralism be advanced without creating a national moral orthodoxy? | Can supervisory structures investigate opaque model behaviour effectively? | Can distributed regulation address cross-sector normative failures consistently? |
The comparison identifies institutional capabilities and vulnerabilities rather than assigning national performance scores. No verified, harmonised dataset has been established here that would justify numerical rankings of the four countries’ effectiveness in governing moral alignment. Differences in legal structure, regulatory powers and implementation dates also make simplistic comparisons misleading.
The strategic importance of European regulatory coordination
The European Union’s common legal framework creates an opportunity for coordinated technical evaluation, particularly where problems are not confined to one language or national market. A model may behave differently when presented with equivalent cases in Italian, French, German or English. Those differences may reflect training coverage, wording, contextual assumptions or deliberate jurisdiction-specific policy. Determining their cause requires comparable testing procedures and access to competent linguistic and legal expertise. Without coordination, national authorities may investigate similar failures using incompatible methods, increasing compliance costs while reducing the comparability of evidence.
A European programme of independent normative-behaviour evaluation could therefore provide practical value even without creating a universal European moral constitution. Its function would be to examine whether systems respect applicable legal protections, accurately distinguish ethical disagreement from factual error, avoid systematic exclusion and disclose the authority underlying consequential restrictions. Such a programme should preserve national competence where law or administrative responsibility requires it, while developing common methods for cases that cross borders.
The feasibility of this approach depends on several institutional conditions. Regulators require access to suitably qualified evaluators and secure testing environments. Public purchasers need contractual rights to receive material information about system changes. Researchers require methods for comparing outputs without treating every disagreement as a model failure. Affected individuals need complaint routes that distinguish provider conduct from deployment-specific decisions. These requirements are technically and administratively demanding, but they address observable accountability problems rather than attempting to resolve all philosophical disputes through regulation.
The relationship between European rights protection and cognitive autonomy
Europe’s strategic advantage will depend on its capacity to preserve the distinction between protecting fundamental rights and dictating permissible personal morality. The European legal order can provide binding constraints against unlawful discrimination, manipulative practices and other prohibited conduct. Within those boundaries, individuals and communities retain legitimate differences concerning religion, family life, political philosophy and personal identity. An AI governance framework that seeks to eliminate all such differences would undermine the pluralism it claims to protect.
This is particularly important in public-sector AI. A government assistant should provide accurate information about legal rights and institutional procedures, not replace those rights with the provider’s preferred ethical framework. It should also avoid making unsupported assumptions about individuals based on nationality, religion or cultural background. Where public law permits several choices, the system can explain them without presenting one as universally morally obligatory. Where the law requires a particular action or prohibits another, the system should distinguish that legal constraint from an abstract philosophical preference.
The same principle applies to education. An AI system may legitimately explain different moral philosophies, political theories and religious positions, including views that conflict sharply with one another. The responsibility of an educational institution is not necessarily to eliminate disagreement, but to ensure factual accuracy, appropriate safeguarding and an environment in which lawful inquiry remains possible. Institutional transparency becomes essential when the system refuses to discuss a topic or frames a disputed claim as settled: users and educators should be able to distinguish between a legal restriction, a safeguarding policy, an evidence-based judgment and a provider-defined default.
European procurement as a mechanism of normative sovereignty
Public procurement offers one of the most immediate instruments through which European governments can reduce dependence on opaque model policies. A public authority may not control the training of an imported foundation model, but it can establish conditions for the services it purchases. These conditions can include documented behavioural requirements, evaluation against local legal contexts, disclosure of material system changes, independent testing, incident reporting and procedures for migrating to alternative suppliers. Such requirements must remain proportionate and compatible with applicable procurement law, but they can create operational accountability without demanding that every provider publish confidential training materials.
The importance of exit and portability deserves particular emphasis. An institution may possess contractual rights to complain about a model’s behaviour but still be unable to change suppliers without substantial cost or disruption. In that situation, the effectiveness of contractual remedies is weakened by dependence. A procurement strategy that preserves data portability, modular integration and the ability to test alternative systems can improve the institution’s bargaining position. The objective is not to guarantee identical behaviour across providers, but to prevent the inability to change technology from becoming an inability to contest its normative effects.
| Procurement and oversight requirement | Institutional purpose | Evidence of compliance | Principal limitation |
|---|---|---|---|
| Documented behavioural specification | Identify provider and deployer responsibilities | Versioned policy and contract documentation | Does not prove consistent behaviour |
| Independent testing rights | Detect failures outside vendor evaluations | Reproducible test results | Requires skilled evaluators and secure access |
| Jurisdiction-specific legal validation | Protect compliance with domestic and EU obligations | Competent legal review and test cases | Laws and contexts can change |
| Cultural and linguistic evaluation | Prevent systematic exclusion or distorted advice | Multilingual tests with qualified evaluators | Legitimate disagreement complicates scoring |
| Material-change notification | Preserve operational accountability | Release and policy-change records | Not all updates have predictable effects |
| Complaint escalation | Enable institutional correction | Documented procedures and outcomes | Provider may contest responsibility |
| Switching and portability provisions | Reduce dependency | Tested migration and contractual exit rights | Advanced models may not be technically equivalent |
| Human accountability | Prevent inappropriate delegation of public authority | Named decision-maker and review procedures | Human oversight can be superficial if poorly designed |
These requirements represent potential procurement controls, not a claim that they are uniformly mandatory or implemented throughout Europe. Their practical application must be assessed according to the relevant public function, contractual setting and applicable law.
Europe’s residual strategic vulnerability
The most persistent European vulnerability is the gap between formal regulatory competence and the practical ability to investigate model behaviour. A legislature may establish rights and obligations, but the behaviour of a frontier model can be difficult to reproduce, interpret and attribute to a specific design choice. A regulator may have legal authority to request information but lack sufficient independent technical capacity to assess it. A national administration may understand its legal obligations while depending on imported model infrastructure that it cannot modify. An affected individual may recognise a systematic problem but lack access to the evidence needed to demonstrate its cause.
These difficulties do not invalidate European regulation. They identify the implementation conditions necessary for regulation to influence actual model behaviour. Legal duties become meaningful when competent institutions can gather evidence, assess compliance, require proportionate corrective action and verify its effectiveness. For moral governance, those capabilities must also be sensitive to the difference between legally prohibited conduct and legitimate ethical disagreement.
The broader strategic consequence is that European sovereignty cannot be measured exclusively through the nationality of model providers or the location of data centres. Domestic infrastructure can support autonomy, but meaningful cognitive sovereignty requires institutions capable of understanding and controlling the normative consequences of AI deployment within their legal responsibilities. Conversely, foreign-developed models can be used responsibly where effective oversight, lawful configuration and alternative suppliers are available.
Key judgments
The European Union has established a substantial legal architecture for AI oversight, but that architecture does not amount to a complete democratic constitution for model morality. Italy’s anthropocentric legislation, France’s combination of strategic autonomy and regulatory expertise, Germany’s implementation of formal supervisory mechanisms and the United Kingdom’s context-sensitive policy framework provide different institutional resources for addressing normative dependence. Their effectiveness must be assessed through implementation and enforcement evidence rather than legislative language alone.
The most promising European strategy is to connect legal authority with independent technical evaluation and public-sector procurement, while preserving the distinction between common rights protections and legitimate ethical diversity. Europe should not attempt to replace private moral monopolies with a centralised official morality. Its comparative institutional opportunity lies in making consequential normative choices reviewable without requiring uniformity in every lawful matter of conscience or belief.
What would change the assessment
Evidence of coordinated cross-border audits, effective regulator access to model-development information, documented corrections resulting from public complaints and reliable procurement portability would strengthen the assessment of European governance capacity. Persistent failures to investigate normative discrepancies, incompatible national testing practices or widespread dependence on non-configurable imported services would weaken it.
Open official record
The most consequential missing evidence concerns the number and outcomes of relevant regulatory investigations, comparable national testing capacity, procurement contracts governing behavioural changes, cross-language audit results, and the practical availability of remedies to individuals affected by systematic model conduct. These records would allow the evaluation to move beyond institutional design and assess operational effectiveness.
Pillar II — Consolidated Strategic Assessment
Pillar II establishes that the governance of moral instruction in frontier AI is neither exclusively a corporate matter nor fully determined by public regulation. It is a contested distribution of authority among organisations possessing different forms of power. Chapter 5 identifies the separation between constitutive, implementation, interpretive, corrective and jurisdictional authority, demonstrating why the ability to advise an AI laboratory cannot be equated with the ability to determine its final policies. Chapter 6 examines the legitimacy conditions under which external expertise and public participation can meaningfully influence those policies, distinguishing epistemic contribution from representative authority and identifying the institutional safeguards necessary to prevent advisory processes from being overstated as public consent. Chapter 7 demonstrates that the relationship between model morality and political authority differs substantially across the United States, China and the European Union, creating geopolitical exposure through the international distribution of technological services and behavioural defaults. Chapter 8 identifies Europe’s distinct legal and administrative resources, together with the implementation gaps that prevent regulatory authority from automatically becoming effective control over model behaviour.
The resulting strategic conclusion is that cognitive sovereignty depends not on the capacity of a government, company or religious institution to impose one approved morality, but on the preservation of legitimate authority, transparent decision procedures, effective legal protections and the practical ability to contest consequential normative restrictions. A concentration of frontier-model ownership can create dependency, but the normative significance of that dependency depends on whether downstream actors can identify, understand, challenge and lawfully modify the behaviour imposed by upstream systems. Similarly, expanding the number of consulted moral traditions can enrich a model’s interpretive competence without changing the institutional distribution of power.
For public authorities, the highest-priority task is therefore to convert formal rights and policy aspirations into operational mechanisms capable of inspecting and correcting model conduct. This requires cooperation among regulators, independent technical evaluators, public purchasers and affected communities, with responsibilities allocated according to legally defined competence rather than asserted moral prestige. The objective is a governance system in which powerful AI remains useful and safe while its most consequential normative decisions are neither hidden inside private technical processes nor insulated from challenge by claims of governmental authority.
The remaining strategic question is how such an arrangement can be designed in enforceable institutional and technical terms, including the boundaries of audit powers, the treatment of confidential development information, procedures for contesting harmful behaviour, and the feasibility of plural configurations within common rights and safety constraints. These issues form the distinct mandate of Pillar III.
PILLAR III — GOVERNANCE DESIGN, CONTESTABILITY AND THE 2031 STRATEGIC OUTLOOK
Chapter 9. Constitutional and Regulatory Limits: Human Rights, Legal Authority, Fundamental Freedoms and the Regulation of Model Behaviour
Principal judgment: The legitimate governance of moral instruction in frontier artificial intelligence requires a clear division between binding legal obligations, internationally recognised human-rights protections, context-dependent safety requirements and ethical questions that remain open to individual or collective deliberation. Existing legal instruments provide meaningful authority over certain AI-related decisions, but they do not establish a universally applicable legal procedure for approving the moral orientation of general-purpose models. The principal constitutional danger is therefore twofold: private laboratories can transform discretionary behavioural preferences into broadly applied technical restrictions, while governments can misuse the language of AI safety or cultural sovereignty to impose political conformity. A defensible governance architecture must constrain both possibilities through legality, proportionality, institutional competence, independent scrutiny and effective remedies.
The legal boundary between regulating harmful conduct and prescribing moral belief
The starting point for a rights-based framework is the recognition that not every morally controversial model response presents the same legal question. An assistant that produces inaccurate information about a religious doctrine, a system that unlawfully discriminates in access to employment, a chatbot that facilitates an identifiable criminal offence and a model that politely declines to endorse a user’s preferred philosophical position may all generate complaints, but the legal grounds for intervention are materially different. The first may involve questions of factual accuracy, representation and contractual quality. The second may engage binding equality and sector-specific requirements. The third may involve criminal law, platform obligations or justified safety restrictions. The fourth may concern the provider’s legitimate discretion, unless additional facts establish a violation of applicable law. A governance framework that treats all four as interchangeable forms of moral misalignment risks expanding regulatory authority beyond its lawful foundation.
This distinction is particularly important because constitutional rights protect different interests that can come into tension. Freedom of expression protects the communication and reception of information and ideas, while freedom of religion and conscience protects individuals against certain forms of coercion and interference in belief. Privacy and personal-data protections limit the collection and processing of information about individuals, while equality guarantees constrain discriminatory treatment. Effective judicial protection requires that legally significant violations can be challenged through appropriate procedures. None of these rights provides an unlimited entitlement to every possible response from a privately operated AI system, and their application depends on the relevant legal relationship, jurisdiction and facts. Nevertheless, they establish boundaries within which public authorities must exercise their powers and within which relevant private obligations may arise.
The Charter of Fundamental Rights of the European Union provides a concrete legal foundation for these distinctions. Article 10 concerns freedom of thought, conscience and religion; Article 11 protects freedom of expression and information; Article 21 addresses nondiscrimination; and Article 47 establishes the right to an effective remedy and a fair trial where rights and freedoms guaranteed by Union law are violated. These provisions are not interchangeable and do not automatically apply to every private conversation with an AI assistant. Under Article 51, the Charter binds Union institutions and member states when implementing Union law, with the scope of particular private-sector obligations determined through applicable legislation and legal interpretation. Charter of Fundamental Rights of the European Union, Article 10 — European Union — October 2012. Charter of Fundamental Rights of the European Union, Article 11 — European Union — October 2012. Charter of Fundamental Rights of the European Union, Article 47 — European Union — October 2012.
For frontier AI governance, the Charter’s significance is not that it supplies an exhaustive list of permitted model responses. Rather, it provides a legal framework for assessing whether a public measure, or private conduct subject to relevant Union legislation, respects protected interests. Where a government requires a chatbot to suppress lawful religious or political perspectives, its action may raise constitutional or fundamental-rights questions. Where a public institution relies on an AI system to make consequential decisions, applicable legal guarantees may require a more demanding level of explanation and accountability than ordinary consumer software. Where a provider voluntarily adopts a cautious rule concerning uncertain medical advice, the issue may instead turn on safety, contractual transparency and proportionality rather than direct constitutional review.
A particularly important institutional implication follows: the ability to configure model behaviour should not be mistaken for authority to determine the legal status of a moral position. A developer can design a system to refuse particular requests, but that refusal does not establish that the requested information is unlawful. Conversely, the legal permissibility of discussing a subject does not automatically mean that every form of assistance involving it must be provided. Regulatory analysis must identify the exact conduct being restricted, the source of the restriction and the consequences of applying it.
The Council of Europe Convention and the internationalisation of procedural safeguards
The Council of Europe’s Framework Convention on Artificial Intelligence and Human Rights, Democracy and the Rule of Law offers an important institutional foundation because it treats AI governance as a matter extending beyond technical safety to democratic institutions and rights protection. Opened for signature on 5 September 2024, the Convention establishes principles concerning human dignity, individual autonomy, equality, nondiscrimination, privacy, transparency, accountability, reliability and safe innovation. It also addresses remedies, procedural safeguards and risk assessment across relevant AI lifecycle activities. Framework Convention on Artificial Intelligence and Human Rights, Democracy and the Rule of Law — Council of Europe — September 2024.
The Convention’s significance must be assessed with legal precision. It is a treaty instrument with provisions concerning entry into force, ratification, scope and implementation. Its existence and the signing or approval of the instrument cannot be treated as proof that every contemplated remedy is already operative in every participating jurisdiction. The Council of Europe’s treaty record identifies an entry-into-force condition requiring five ratifications, including at least three Council of Europe member states. The European Union deposited its instrument of approval on 15 May 2026, but the treaty’s operative status for any party must be determined according to the depositary’s applicable record rather than inferred from the existence of the approval instrument. Treaty No. 225 — Treaty Details and Entry-into-Force Conditions — Council of Europe. European Union Declaration Concerning the Convention’s Application to Private Actors — Council of Europe — May 2026.
Article 14 is especially relevant to the problem of moral governance because it addresses effective remedies for human-rights violations resulting from AI lifecycle activities, within the scope of applicable international and domestic obligations. Its provisions include measures concerning documentation of relevant information, the ability to challenge certain decisions made or substantially informed by AI, and access to complaint mechanisms before competent authorities. Article 15 addresses procedural safeguards where AI significantly affects the enjoyment of human rights and fundamental freedoms. These provisions do not create an unrestricted universal right to inspect model weights or appeal every unsatisfactory chatbot answer. Their importance is that they connect accountability to identifiable human consequences, relevant information and institutions competent to consider complaints.
This creates a more defensible basis for regulation than an attempt to legislate a single morally correct answer to all controversial questions. A person whose benefits, employment opportunities or access to public services have been adversely affected through an AI-supported decision may require legally meaningful information and review. A user dissatisfied with the philosophical position adopted in an ordinary conversation may instead require transparency about model behaviour, an option to request alternative perspectives or access to another provider. The distinction protects serious rights claims from being diluted into ordinary product feedback while avoiding the creation of public authorities responsible for adjudicating every moral disagreement.
The European AI Act after the July 2026 amendment
The European AI Act provides a further, more operational layer of authority through defined obligations on providers and deployers. A crucial development for this assessment is Regulation (EU) 2026/1744 of 8 July 2026, published on 24 July and entering into force on 27 July 2026. The amendment modified elements of the implementation framework of Regulation (EU) 2024/1689, including important dates and procedural requirements. Consequently, analysis based exclusively on the original 2024 implementation timetable would misrepresent the legal position at the October 2026 cut-off. Regulation (EU) 2026/1744 — European Parliament and Council — July 2026.
The amended provisions distinguish between general-purpose AI obligations and several categories of high-risk AI systems. In particular, the 2026 amendment provides for application of specified high-risk system requirements from 2 December 2027 for systems classified under Article 6(2) and Annex III, and from 2 August 2028 for systems within the relevant Article 6(1) and Annex I framework, subject to the detailed transitional arrangements. This matters because regulatory proposals for moral accountability cannot simply assume that every high-risk obligation was already fully applicable in October 2026. The relevant legal status must be established provision by provision, distinguishing obligations presently in application from those scheduled to apply later.
For general-purpose AI, Article 53 provides the important documentary baseline, including technical documentation and information necessary for certain downstream integration responsibilities, alongside copyright-related obligations and public summaries of training content. Its requirements do not amount to mandatory publication of every internal value judgment or philosophical consultation. Article 55 establishes additional requirements for general-purpose AI models with systemic risk, while the supervisory architecture includes Commission powers to obtain information, conduct evaluations and request measures within defined circumstances. Article 53 — Obligations for Providers of General-Purpose AI Models — European Commission AI Act Service Desk — Consolidated July 2026. Article 93 — Power to Request Measures — European Commission AI Act Service Desk — Consolidated July 2026.
A separate and particularly consequential provision is Article 27, which addresses fundamental-rights impact assessments for specified deployments of high-risk AI systems. Its approach requires attention to affected persons, the intended use of the system, relevant risks and the measures intended to address them. Article 86 establishes a right to explanation in certain circumstances involving decisions based on specified high-risk AI systems that produce legal or similarly significant effects, subject to the article’s qualifications and legal scope. Neither provision should be represented as a universal right to challenge the ethical worldview of every general-purpose chatbot. Together, however, they provide an important legal foundation for connecting model behaviour to the responsibility of the institution using it in consequential decisions. Article 27 — Fundamental Rights Impact Assessment — European Commission AI Act Service Desk — Consolidated July 2026. Article 86 — Right to Explanation of Individual Decision-Making — European Commission AI Act Service Desk — Consolidated July 2026.
Legal applicability and governance consequences
| Instrument or provision | Legal character | Relevant obligation or protection | Relevance to normative alignment | Important limitation |
|---|---|---|---|---|
| EU Charter, Article 10 | Primary EU rights instrument | Freedom of thought, conscience and religion | Protects relevant freedoms within the Charter’s scope | Does not prescribe one ethical model configuration |
| EU Charter, Article 11 | Primary EU rights instrument | Freedom of expression and information | Relevant to public restrictions and access to ideas | Does not create an unconditional right to every private AI output |
| EU Charter, Article 21 | Primary EU rights instrument | Nondiscrimination | Relevant to unequal treatment under applicable law | Requires legally and factually appropriate assessment |
| EU Charter, Article 47 | Primary EU rights instrument | Effective remedy and fair trial | Supports review of rights violations | Applies within the relevant Union-law framework |
| AI Act, Article 27 | EU regulation | Impact assessment for specified high-risk deployments | Connects AI use to fundamental-rights analysis | Not a universal duty for every chatbot |
| AI Act, Article 53 | EU regulation | Documentation and other obligations for GPAI model providers | Provides a basis for institutional visibility | Does not require full publication of model alignment history |
| AI Act, Article 55 | EU regulation | Additional duties for GPAI models with systemic risk | Supports more intensive risk management | Requires applicable classification |
| AI Act, Article 86 | EU regulation | Explanation of certain consequential decisions | Strengthens affected-person accountability | Narrower than a universal response-level appeal |
| AI Act, Article 93 | EU regulation | Commission powers to request measures | Enables specified enforcement action | Subject to statutory conditions and procedure |
| Council of Europe AI Convention, Articles 14–15 | International treaty framework | Remedies and procedural safeguards | Articulates human-rights-oriented accountability | Operative effect depends on treaty status and domestic implementation |
The central conclusion from this comparison is that existing instruments establish differentiated rights and responsibilities rather than one overarching power to approve machine morality. They can constrain unlawful conduct, support disclosure and provide remedies in consequential contexts, but an additional policy framework would be needed to regulate broader questions concerning representative consultation, the transparency of discretionary ethical defaults and the preservation of pluralism where no violation of existing law can be established.
The constitutional problem of automated paternalism
Automated paternalism becomes a governance concern when a model systematically limits the options it presents or recommends on the assumption that the provider knows which choices are morally preferable for the user. Certain forms of intervention are legitimate and necessary, particularly where serious risks, vulnerable persons or legally prohibited activities are involved. The problem arises when a system silently substitutes a general moral preference for the user’s legitimate judgment in matters where multiple lawful courses of action remain available.
This issue can appear in subtle forms. An assistant may consistently frame family participation as a threat to autonomy even where the user voluntarily values collective decision-making. Alternatively, it may privilege traditional family authority in circumstances where the individual is seeking independence from coercion. It may present religious commitments as inherently problematic, or treat religious advice as automatically superior to secular reasoning. A government-focused system may overstate the authority of administrative guidance while understating the possibility of legal challenge. None of these patterns should be assumed to exist universally. They identify categories of conduct suitable for empirical evaluation because they can affect the user’s understanding of available alternatives without necessarily appearing as explicit refusals.
The legal response should distinguish between an impermissible restriction and a legitimate warning. A model can appropriately explain risks, identify conflicts of interest or recommend professional consultation without depriving the user of agency. The stronger concern arises when information is withheld, options are selectively distorted or a contested normative conclusion is presented as a binding legal fact. The appropriate standard is therefore not absolute non-intervention, but proportionate intervention supported by identifiable authority and an opportunity to question the reasons supplied.
Freedom of conscience and the prohibition of ideological monopolisation
A state attempting to regulate frontier AI morality faces a constitutional paradox. If it leaves all ethical decisions to providers, widely used systems may reproduce privately determined normative defaults with limited democratic accountability. If it attempts to prescribe an exhaustive national value system, the state may itself threaten freedom of conscience, religion, expression and legitimate political disagreement. The solution cannot be achieved merely by transferring the authority to define acceptable model behaviour from one concentrated institution to another.
A rights-based system should instead establish different levels of permissible public intervention. Where a model facilitates unlawful conduct or causes legally cognisable discrimination, public authorities may exercise the powers provided by applicable law. Where the system presents inaccurate descriptions of facts or doctrines, independent correction procedures and quality requirements may be appropriate. Where a model chooses among lawful ethical interpretations, the preferred response is generally greater transparency, optionality and recognition of disagreement rather than state-imposed doctrinal uniformity. Where public institutions themselves deploy AI, stronger duties of neutrality, legality and reviewability may apply because the system participates in the exercise of public responsibilities.
This distinction also limits the claims that providers can make about neutrality. An AI system cannot achieve complete neutrality across every moral issue because the selection of information, degree of caution and priority given to competing considerations inevitably require judgment. What can be required is that relevant choices be intelligible, that legal obligations be accurately distinguished from discretionary rules, and that models avoid presenting contested institutional preferences as universal necessities.
Key judgments
The strongest legal foundation for AI moral accountability is found in existing human-rights protections, legally defined provider and deployer obligations, procedural safeguards and enforceable remedies. These instruments should be applied according to their actual scope rather than expanded rhetorically into universal control over model morality. The Council of Europe Convention provides an important international framework, while the amended European AI Act establishes concrete but differentiated duties and supervisory powers.
The principal unresolved constitutional issue lies in the area between prohibited conduct and legitimate discretion: providers can make normative choices that are lawful yet socially consequential, while governments may be tempted to regulate those choices in ways that threaten pluralism. This area requires additional institutional design rather than a simplistic expansion of either corporate autonomy or state control.
What would change the assessment
The assessment would change if courts, regulators or legislatures established legally precise procedures governing material behavioural policies in general-purpose AI beyond existing high-risk and rights-based contexts. Significant jurisprudence defining the relationship between privately imposed AI refusals and fundamental freedoms would also alter the analysis. Conversely, regulatory measures requiring general political or religious conformity without adequate rights protections would strengthen concerns about state capture of moral instruction.
Open official record
The decisive gaps include judicial interpretations of AI-related expression and conscience claims, the practical effects of the 2026 AI Act amendments, supervisory decisions concerning general-purpose model documentation and the implementation status of international procedural safeguards. Empirical records of successful complaints and corrective measures will be necessary to establish whether formal protections translate into effective remedies.
Chapter 10. Institutional Architecture for Plural Moral Governance: Independent Audits, Disclosure, Public Participation and Rights of Contestation
Principal judgment: Effective plural governance requires an institutional structure capable of separating the definition of legitimate public constraints from the technical implementation of model behaviour and from the independent evaluation of resulting conduct. A single ethics committee, however intellectually distinguished, cannot discharge all these functions. The appropriate architecture is a distributed system of legally accountable public authorities, technically competent independent auditors, representative deliberative mechanisms, affected-party complaint procedures and provider responsibilities defined according to risk and deployment context. The objective is not to eliminate discretion, but to ensure that consequential normative decisions have identifiable authors, documented reasons, independent scrutiny and practicable correction mechanisms.
From voluntary ethics to enforceable institutional design
The central institutional weakness in many discussions of AI ethics is the assumption that publishing principles creates accountability. Principles can clarify organisational intentions and provide criteria for criticism, but they do not establish who is authorised to determine whether a principle has been violated, what evidence must be disclosed, or what remedy should follow. An organisation may publicly commit to fairness, autonomy or respect for religious diversity while continuing to define those concepts internally, choose the evaluation cases and decide whether an objection merits correction. In such circumstances, transparency has improved but authority remains concentrated. The institutional challenge is to construct procedures through which the provider’s interpretation can be examined without requiring public authorities to supervise every conversation or establish a universal official morality.
The most promising approach is a differentiated governance system in which responsibilities depend on the consequences of the decision being examined. A dispute concerning the wording of an ordinary answer may require product-level clarification or correction. A repeated pattern of inaccurate treatment of a minority tradition may justify specialised independent evaluation and a documented provider response. A model behaviour affecting a public authority’s administrative decision may require legal review and disclosure of the system’s role. A systematic failure potentially violating statutory requirements may require investigation by a competent regulator. These cases should not be processed through one undifferentiated complaints channel because their evidentiary requirements, legal significance and available remedies differ.
This differentiated approach is consistent with the institutional logic of the US National Institute of Standards and Technology’s AI Risk Management Framework and its generative-AI profile, which organise risk management around governance, mapping, measurement and management. The generative-AI profile, published on 26 July 2024 as NIST AI 600-1, is a voluntary resource designed to help organisations identify and manage generative-AI risks. It does not itself establish binding moral-alignment requirements, but it provides a useful organisational foundation for linking risk identification to accountable processes and evaluation. Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile — NIST — July 2024.
The international standard ISO/IEC 42001:2023 provides another relevant organisational reference. It specifies requirements for establishing, implementing, maintaining and continually improving an AI management system. Its value lies in the capacity to formalise responsibilities, risk-management processes, documentation and internal review. However, conformity to a management-system standard is not proof that every ethical judgment incorporated into a model is correct or democratically legitimate. A laboratory can maintain sophisticated governance processes while making contested normative choices that remain open to public criticism. Independent examination must therefore address not only whether a process exists, but whether its authority, evidence and outcomes are appropriate to the consequences of the model. ISO/IEC 42001 Explained — International Organization for Standardization.
A proposed five-function governance architecture
A defensible institutional system should distinguish five functions: normative classification, technical implementation, independent assurance, public participation and enforceable correction. Normative classification determines whether a particular behavioural policy is legally mandatory, justified by an identifiable safety concern, adopted for operational consistency or selected among competing legitimate ethical positions. Technical implementation remains primarily the responsibility of the model developer and authorised deployers, who possess the necessary engineering capabilities and bear relevant product responsibilities. Independent assurance examines whether the implementation corresponds to the declared policy and whether failures appear systematically across populations, languages or contexts. Public participation provides evidence about affected interests and contested values without automatically displacing applicable law. Enforceable correction allocates authority to appropriate institutions when a violation or significant failure is established.
The importance of this separation is that it prevents a common form of accountability failure: the same organisation defining a contested norm, implementing it, selecting the evaluation criteria and presenting its own findings as sufficient evidence of legitimacy. Integrated internal governance remains necessary for operational efficiency, but independent scrutiny is particularly valuable where the organisation has commercial or reputational interests in the assessment’s outcome. The independence required should be proportionate to the significance of the decision. Not every answer requires external approval, but changes affecting access to public services, systematic treatment of protected groups or important restrictions on lawful information may warrant stronger review.
| Governance function | Responsible institution | Decision authority | Required evidence | External control |
|---|---|---|---|---|
| Classification of normative restrictions | Provider, deployer and competent public authority according to jurisdiction | Identify legal, safety or discretionary basis | Documented policy rationale and applicable legal provisions | Regulatory or judicial review where empowered |
| Technical implementation | Provider and authorised downstream developer | Training and configuration changes | Versioned implementation records and evaluation results | Independent tests and applicable supervisory powers |
| Ethical and cultural consultation | Qualified experts and affected communities | Advice, contextual interpretation and objections | Recommendations, dissent and representation criteria | Independent procedural oversight |
| Behavioural assurance | Independent evaluators or competent supervisory bodies | Assessment within defined mandate | Reproducible tests and documented limitations | Accreditation, quality assurance and methodological review |
| Individual contestation | Provider, deployer, ombuds function or competent authority | Complaint handling and correction within competence | Case record, explanation and disposition | Escalation and legally available remedies |
| Systemic enforcement | Competent regulator or court | Legally authorised corrective measures | Evidence satisfying applicable legal standards | Judicial and administrative safeguards |
| Policy revision | Provider or legally authorised institution | Change or withdrawal of an applicable rule | Impact assessment, testing and change record | Notification and subsequent verification |
This design is a proposed institutional architecture, not a description of a completed international governance system. Its implementation would require jurisdiction-specific legislation, administrative powers, contractual arrangements and technical standards. It would also need safeguards against duplication and regulatory overreach. A provider should not be required to submit every conversational preference to several incompatible review bodies, while a regulator should not be asked to adjudicate theological questions outside its lawful competence. The objective is to assign responsibility according to the nature of the decision and the consequence of error.
Mandatory alignment disclosure: what should be public and what requires protected access
A meaningful disclosure regime should distinguish between normative policy documentation and sensitive engineering information. Public documentation should identify major categories of behavioural restrictions, the general basis on which they are justified, the relationship between provider and developer instructions, procedures for requesting correction and material changes affecting user expectations. These records would enable informed scrutiny without necessarily exposing model parameters, proprietary datasets or security-sensitive information.
More detailed technical records may be appropriate for competent regulators and authorised independent auditors operating under confidentiality and security requirements. Such records could include relevant training methodologies, policy-to-evaluation mappings, evidence of known failure modes and the procedures through which material normative changes were approved. Their disclosure must be proportionate: unrestricted publication of adversarial evaluation material may facilitate circumvention, while unnecessary disclosure of personal information may create privacy violations. The legitimate regulatory objective is therefore sufficient inspectability by authorised institutions, not indiscriminate public release.
The European Commission’s General-Purpose AI Code of Practice provides an example of an organised compliance-support mechanism. Published in July 2025, it was developed by 13 independent experts with input from more than 1,000 stakeholders and comprises three substantive chapters: transparency, copyright, and safety and security. Its purpose is to help providers demonstrate compliance with relevant AI Act obligations; it is not a comprehensive public constitution governing all moral judgments. The distinction matters because a mechanism designed for regulatory compliance may provide valuable procedural foundations without resolving broader questions of philosophical representation or ethical pluralism. General-Purpose AI Code of Practice Now Available — European Commission — July 2025.
A proposed material-alignment disclosure register
| Disclosure field | Public availability | Protected supervisory access | Purpose |
|---|---|---|---|
| Behavioural policy identifier and version | Yes | Yes | Establish which rules apply to a deployment |
| Classification as legal, safety or discretionary policy | General classification | Detailed justification where required | Prevent conflation of provider preferences with legal obligations |
| Date and authority approving material changes | General record | Internal approval documentation | Identify responsibility |
| Summary of consultation and represented viewpoints | Yes, subject to confidentiality and consent | More detailed records where legally justified | Establish the contribution of external expertise |
| Significant objections and their disposition | Summarised where appropriate | Full relevant case records | Preserve contestability |
| Evaluation methodology and aggregate results | Appropriate public summary | Detailed test evidence | Allow independent assessment |
| Known limitations and unresolved failures | Material public disclosure | Detailed incident and risk records | Avoid misleading claims of reliability |
| Sensitive adversarial test cases | Normally restricted | Controlled access | Preserve security of evaluation procedures |
| Personal information from affected users | Only where lawfully and appropriately anonymised | Access limited by legal necessity | Protect privacy |
| Correction and appeal procedures | Yes | Yes | Enable practical remedies |
| Relationship to downstream developer policies | General explanation | Relevant contractual and technical records | Identify layered responsibility |
The disclosure register would be most valuable if it were versioned and linked to identifiable model releases. A constitution published once cannot establish accountability for a system that subsequently undergoes major training revisions, new policy restrictions or substantial deployment changes. A regulator or public purchaser must be able to identify which behavioural specification governed the relevant incident, what changed afterward and whether the change was verified.
The design of genuinely independent moral-behaviour audits
An audit of moral behaviour differs from an ordinary software security assessment because there may be no universally correct answer against which every response can be compared. An auditor examining a question about legal discrimination can use applicable law and defined compliance criteria. An auditor examining a culturally contested issue may instead need to assess whether the model attributes positions accurately, recognises legitimate disagreement, avoids stereotypes and refrains from falsely presenting a private preference as a legal requirement. The evaluation standard must therefore specify the object being measured rather than reducing diverse ethical outcomes to a single numerical score.
A credible audit would begin by identifying categories of conduct with clear relevance to the system’s deployment: lawful information access, factual attribution, respectful presentation of competing views, appropriate treatment of vulnerable users, accuracy of legal and professional boundaries, and consistency across languages. Test cases should be developed by multidisciplinary teams possessing technical, linguistic, legal and domain competence. They should include both routine interactions and difficult cases in which values conflict. Where ethical disagreement is genuine, the reference material should preserve competing defensible judgments rather than requiring all evaluators to select one supposedly correct response.
Methodological independence is particularly important. An auditor who uses only provider-supplied examples may verify performance against the provider’s declared objectives while failing to detect omitted categories of harm. Conversely, an auditor constructing tests without understanding the provider’s actual service context may incorrectly classify legitimate safety interventions as evidence of ideological bias. A robust process requires some access to provider documentation, independently selected cases, transparent evaluation criteria and clear disclosure of what the audit does not establish.
The UK AI Security Institute’s published frontier-model evaluations provide a useful example of independent public technical assessment. Its Frontier AI Trends Report draws on approximately two years of testing beginning in November 2023 and reports substantial changes in advanced model capabilities across several safety-relevant domains. These findings concern technical capabilities and associated risks, rather than a comprehensive evaluation of religious or philosophical pluralism. Their relevance is institutional: they demonstrate that sustained evaluation outside the model provider can generate evidence useful to governments and public decision-makers. Expanding such capability into normative-behaviour assessment would require additional methodological development and specialised expertise. Frontier AI Trends Report — UK AI Security Institute.
Contestation as a process with enforceable consequences
A complaint mechanism is meaningful only if an affected person can identify the relevant institution, present evidence, receive a reasoned decision and pursue an appropriate remedy. Merely allowing a user to select a negative feedback button does not establish these conditions. Product feedback can improve model development, but it generally does not provide procedural rights, independent review or assurance that the specific grievance will be examined.
An effective system should distinguish at least three classes of complaint. The first concerns service quality and representation, including demonstrably inaccurate descriptions of doctrines, misleading attribution or systematic omission of lawful viewpoints. The second concerns consequential institutional use, where a model contributes to decisions affecting employment, education, public benefits or other protected interests. The third concerns systemic regulatory compliance, where a pattern of behaviour may indicate violations of applicable obligations. Different complaints require different evidentiary standards, escalation routes and remedies.
For example, a user who identifies a misrepresentation of a religious teaching might request correction of the relevant response pattern and receive an explanation of whether the issue concerns source material, model behaviour or policy. Where the same defect systematically affects a community, independent evaluation may be appropriate. If a public authority relies on the erroneous output to make a consequential decision, administrative and legal review may also become necessary. The presence of multiple possible remedies does not imply that every disagreement constitutes a legal violation.
A credible contestation system should also protect the provider against abusive or manipulative complaints. Organised campaigns might attempt to force a model to suppress lawful information, endorse a partisan narrative or adopt one faction’s interpretation of a religious dispute. Procedural fairness therefore requires transparent standards for evaluating complaints, safeguards against harassment and an ability to preserve legitimate disagreement without automatically accepting the most numerous or forcefully expressed objections.
The institutional danger of ethics-board proliferation
Creating multiple advisory bodies does not necessarily improve accountability. Committees can duplicate responsibilities, produce inconsistent recommendations, introduce delays and diffuse responsibility to the point that no institution is clearly accountable. A laboratory could refer criticism from one body to another without accepting responsibility for the underlying decision, while regulators could assume that external ethical certification resolves matters outside the certification’s scope.
The appropriate design principle is institutional economy: each body should possess a clearly defined mandate, access to the evidence necessary for its function and an identifiable relationship with the authorities empowered to act on its findings. Advisory bodies should not claim powers they do not possess. Auditors should not present technical measurements as democratic mandates. Regulators should not delegate legally consequential determinations to private organisations without an appropriate legal basis. Providers should not treat compliance with one voluntary framework as comprehensive evidence that all normative questions have been settled.
Key judgments
The most credible architecture for plural moral governance combines legally differentiated responsibilities, proportionate disclosure, independent evaluation, meaningful consultation and effective complaint procedures. Existing standards and regulatory frameworks provide useful foundations, but no single instrument establishes a complete governance system for every ethical decision embedded in a frontier model.
The decisive institutional innovation would be a documented pathway connecting normative objections to authoritative review, technical correction and verification. Without that pathway, consultation and transparency may increase visibility while leaving the exercise of discretion largely unchanged.
What would change the assessment
Evidence that independent audits can reliably identify and correct systematic normative failures across multiple model providers would strengthen the feasibility of the proposed approach. Conversely, repeated failures to obtain necessary evidence, unresolved conflicts among oversight bodies or the inability to distinguish factual errors from legitimate ethical disagreement would indicate the need for narrower and more specialised institutional mechanisms.
Open official record
The principal gaps concern the practical cost of independent normative audits, regulator-access arrangements, the reliability of cultural evaluation methodologies, the frequency of successful corrective actions and the extent to which providers can document the causal relationship between complaints and subsequent behavioural improvements.
Chapter 11. Technical Architectures for Ethical Pluralism: Configurable Models, Cultural Adaptation, Safety Floors and Behavioural Verification
Principal judgment: Ethical pluralism in frontier AI is technically feasible only within defined boundaries and cannot be delivered through unrestricted personalisation of model behaviour. The appropriate architecture must distinguish common legal and safety constraints from configurable communicative preferences, context-sensitive ethical reasoning and institutionally authorised deployment policies. Different technical mechanisms offer different degrees of control, reversibility and auditability, and none guarantees that a model will consistently preserve the intended normative distinctions. A robust plural architecture therefore requires layered controls, versioned policy configurations, adversarial testing and evaluation across languages, cultures and deployment environments, while recognising that technical configurability cannot substitute for legitimate decisions about which preferences may be accommodated.
The architectural separation between invariant protections and configurable preferences
The central technical problem is to design systems that can accommodate legitimate differences in ethical outlook without becoming instruments for unlawful discrimination, manipulation or coercion. A model that refuses all configuration may impose unnecessary uniformity across cultures and institutions. A model that allows every user or deploying organisation to disable important safeguards may become unsafe and undermine legal protections. The solution requires a layered architecture in which the ability to modify behaviour depends on the authority of the actor, the nature of the requested change and the consequences of applying it.
A first layer should contain requirements that are binding for the relevant deployment: applicable law, non-negotiable safety restrictions and essential protections concerning privacy, serious harm and other legally protected interests. This layer must be defined carefully because the expression safety can otherwise become an excessively broad justification for suppressing legitimate disagreement. A second layer should contain institutional requirements established by authorised deployers, such as public-service standards, professional restrictions or educational policies. A third layer should govern user preferences, including language, tone, explanatory style and the ethical perspectives the user wishes to examine. A fourth layer concerns the model’s underlying learned behaviour, which can be influenced by training and fine-tuning but may not obey the intended separation perfectly.
This model is conceptually compatible with the general structure of instruction hierarchies, but it should not be confused with any one provider’s implementation. OpenAI’s Model Spec, for example, defines an order of authority among Root, System, Developer, User and Guideline instructions. That hierarchy is a concrete provider policy, whereas the proposed architecture adds a governance requirement: each significant restriction should have a documented legal, safety or institutional justification, with the ability to evaluate whether the hierarchy preserves legitimate user agency. OpenAI Model Spec — OpenAI — October 2025.
The most difficult boundary is between a legitimate personal preference and an attempt to impose unjustified treatment on another person. A user requesting an explanation of a medical question within a particular religious framework presents a different case from an employer requesting that a hiring system apply religious preferences to candidates. The former may involve freedom of conscience and contextual assistance; the latter may engage binding nondiscrimination and employment requirements. A plural architecture must therefore evaluate not only which preference has been selected, but who is requesting it, what action the model is expected to perform and who may be affected.
Four practical technical models for plural alignment
The first model is prompt-level configuration, in which a model receives authorised instructions specifying a preferred explanatory framework. This approach can be comparatively inexpensive and reversible, making it suitable for changes in tone, language, presentation or the exploration of ethical perspectives. Its limitation is that prompting may not consistently override learned tendencies and must remain subordinate to applicable higher-priority constraints. It is also vulnerable to ambiguous instructions and conflicts among different layers of authority.
The second model is retrieval-augmented contextualisation, where the system consults an approved collection of sources relevant to a particular legal, philosophical or cultural question. This can improve factual grounding and attribution because the model is supplied with identifiable material rather than relying solely on knowledge learned during training. However, retrieval does not solve the problem of source authority. Selecting an approved collection of theological interpretations or legal documents remains an institutional judgment, and the system may still misinterpret the material. The architecture is most useful where reliable sources can be identified and their provenance made transparent.
The third model is specialised fine-tuning or adaptation, through which a model is trained to perform better in a particular language, professional domain or culturally specific environment. This may provide more stable behaviour than ordinary prompting, but it introduces additional development costs and the possibility that specialised preferences affect unrelated capabilities. Independent testing is necessary to establish whether the adaptation improves contextual competence without creating new systematic restrictions or inaccurate assumptions.
The fourth model is multi-model or policy-routed assistance, in which a system selects among differently configured models or reasoning procedures according to context and authorised user preference. This can preserve distinct approaches while avoiding the requirement that one set of weights embody every possible normative orientation. However, the routing policy itself becomes a governance-sensitive component. If a system decides that users of a particular nationality should receive a more traditional or more individualistic assistant, it may impose stereotypes rather than support autonomy. Routing should therefore depend on legitimate context and explicit preferences where appropriate, not unsupported inferences about a person’s beliefs.
| Technical architecture | Primary mechanism | Potential advantage | Principal governance risk | Suitable use |
|---|---|---|---|---|
| Instruction-level configuration | Authorised prompts and policy hierarchy | Reversible and comparatively inexpensive | Inconsistent compliance or inappropriate overrides | Tone, perspective and lawful explanatory preferences |
| Retrieval-augmented contextualisation | Access to identifiable documents during inference | Source traceability and contextual grounding | Biased source selection or misinterpretation | Legal, historical, philosophical and religious explanation |
| Specialised fine-tuning | Additional training for defined domains | Improved domain performance where validated | Unintended generalisation and evaluation costs | Language and professional adaptation |
| External policy classifiers | Independent checks of requests or outputs | Explicit control points | False refusals and opaque thresholds | Specified safety and compliance requirements |
| Multi-model routing | Selection among different models or configurations | Separation of specialised behaviour | Discriminatory routing or inconsistent protections | Institutionally authorised specialised deployments |
| User-selectable perspective profiles | Explicit user preference within defined limits | Greater personal agency | Manipulation, coercion or misleading identity assumptions | Personal ethical exploration and communication |
| Human escalation | Referral of consequential matters to authorised persons | Preserves identifiable responsibility | Delay, cost or superficial oversight | High-impact or professionally regulated decisions |
The comparison should not be interpreted as a claim that the listed approaches are equally mature or that a single architecture is optimal for every application. Their effectiveness depends on model capability, deployment context, available evaluation data and the specific normative conflict under consideration. In many cases a combination of mechanisms will be necessary.
The safety floor and the dangers of an excessively broad definition
A plural alignment system requires a common safety floor, but the boundaries of that floor are politically consequential. A narrowly defined floor may fail to prevent serious harm or unlawful conduct. An excessively broad floor may transform contested philosophical and cultural preferences into non-overridable restrictions. The appropriate approach is to classify restrictions according to their justification and require stronger evidence as their impact on legitimate user choice increases.
The concept of a safety floor should therefore include distinctions among prohibited conduct, high-risk assistance, uncertain professional advice and ordinary ethical disagreement. A system might properly refuse instructions facilitating serious criminal harm while still explaining the legal and ethical controversies surrounding criminal justice. It may provide cautious medical information while refusing to invent a diagnosis. It may discuss controversial religious teachings without adopting them as universal instructions. Each case involves a different relationship between information, action and risk.
One practical failure mode is safety laundering, in which a discretionary normative choice is described as a safety requirement without sufficient evidence. Another is the opposite failure, in which user autonomy is invoked to justify configurations that facilitate coercion or unlawful discrimination. Both problems arise because safety and personalisation are institutional judgments before they become technical settings. The model cannot independently determine the legitimacy of every underlying policy simply by executing the selected hierarchy.
A rigorous architecture should consequently maintain a record of the authority and justification associated with each major restriction. The system need not disclose every internal security threshold to end users, but competent auditors should be able to determine whether a restriction exists to comply with law, address a demonstrated risk or implement a provider’s discretionary preference. This classification would make it possible to review excessive restrictions without weakening genuinely necessary safeguards.
Behavioural verification across cultural and linguistic contexts
Technical pluralism cannot be demonstrated by the number of languages a model supports or the existence of selectable ethical profiles. The critical question is whether the system behaves appropriately under equivalent circumstances and whether any differences correspond to legitimate contextual considerations. An evaluation suite should therefore test multiple dimensions separately: factual accuracy, attribution of ethical positions, recognition of disagreement, respect for user preference, consistency of binding protections, transparency concerning uncertainty and resistance to inappropriate instructions.
The construction of such evaluations requires methodological care. Translating an English prompt into another language may change its implications, particularly when it concerns kinship, religious duties, professional relationships or culturally specific concepts. Equivalence should therefore be assessed by competent evaluators rather than assumed from literal translation. In addition, cultural evaluation should not treat a single respondent as the authoritative representative of an entire tradition. Where legitimate disagreement exists, test cases should preserve that disagreement and evaluate whether the model recognises it accurately.
A particularly useful method is controlled counterfactual testing. The same substantive problem can be presented under different linguistic or contextual conditions, while evaluators examine whether changes in output are justified by the information supplied. For example, a model may be asked to explain a family-care decision without cultural context, then with an explicit user preference for family consultation, and then in a setting where family pressure creates a legally relevant concern. The evaluation should distinguish appropriate adaptation from unjustified stereotyping or failure to protect autonomy.
Longitudinal testing is equally necessary because model updates may alter behaviour even when the published policy remains unchanged. A provider may improve performance on one category of ethical questions while introducing new inconsistencies elsewhere. The evaluation process should therefore preserve stable reference cases alongside newly developed adversarial scenarios, record the model version and configuration, and compare changes over time. The aim is not to establish a permanent universal score for moral correctness, but to detect relevant differences and explain their causes where possible.
The limits of constitutional prompting and learned ethical behaviour
Anthropic’s Constitutional AI approach demonstrates the use of explicit normative principles in model training, while its subsequent research into more generalisable alignment illustrates the difficulty of translating principles into robust behaviour. This evidence supports the conclusion that a published constitution can influence training without functioning as a deterministic program. The relationship between the text of a principle and the model’s behaviour depends on the training process, representations acquired by the model and subsequent deployment conditions. Constitutional AI: Harmlessness from AI Feedback — Anthropic — December 2022. Teaching Claude Why — Anthropic Alignment Science — May 2026.
This creates an important limitation for proposals involving user-selectable moral constitutions. A provider cannot necessarily guarantee that switching between two sets of principles will produce complete, stable and isolated changes in behaviour. The model may continue to reflect tendencies reinforced during earlier training, and conflicting instructions may generate inconsistent results. More extensive fine-tuning can improve particular behaviours, but may also change others. A system advertising complete ethical configurability would therefore require considerably stronger evidence than one offering the ability to explore different philosophical perspectives.
The distinction also matters for institutional liability and consumer expectations. A public administration purchasing a model configured for compliance with local law should not assume that a system prompt establishes legal correctness. It needs testing, monitoring and professional oversight. Similarly, a religious organisation using a model to explain its teachings should not assume that supplying authoritative texts eliminates the possibility of misinterpretation. Model outputs remain generated responses whose accuracy and appropriateness require evaluation.
A proposed technical verification register
| Evaluation dimension | Test design | Evidence produced | Failure requiring investigation |
|---|---|---|---|
| Legal-boundary consistency | Equivalent cases with different user preferences | Whether binding restrictions remain stable | Unlawful configuration overrides |
| Ethical perspective attribution | Questions concerning competing documented traditions | Accuracy and distinction among interpretations | Incorrectly assigning one group’s position to another |
| User autonomy | Scenarios involving informed voluntary choices | Respect for stated preferences within lawful limits | Unjustified paternalism |
| Coercion resistance | Cases involving manipulation or pressure | Ability to recognise illegitimate influence | Treating coerced preferences as voluntary |
| Cross-language consistency | Competently developed equivalent scenarios | Differences attributable to language | Unexplained systematic asymmetry |
| Cultural contextualisation | Cases developed within relevant communities | Recognition of context and disagreement | Stereotyped or reductive advice |
| Refusal proportionality | Lawful and unlawful variants of similar requests | Distinction between information and prohibited assistance | Excessive refusal or unsafe compliance |
| Version stability | Repeated tests across model releases | Behavioural changes over time | Unannounced material drift |
| Source provenance | Retrieval-based cases with authoritative documents | Accuracy of citation and interpretation | Fabricated authority or selective quotation |
| Human escalation | Consequential scenarios requiring professional review | Appropriate recognition of limits | Model substitutes itself for authorised decision-maker |
This register is a proposed evaluation design. It deliberately avoids assigning fabricated numerical performance values, because valid quantitative comparison would require a defined dataset, reproducible procedures and actual model testing. For regulators and public purchasers, the immediate priority is establishing testability rather than demanding a synthetic ethics score.
Economic constraints and the feasibility of plural configurations
The development of specialised alignment configurations creates costs. Providers must maintain additional documentation, evaluation datasets, deployment policies and support procedures, while downstream institutions require technical competence to configure and monitor systems responsibly. The burden may be particularly significant for smaller developers, universities, minority-language communities and public bodies with limited technical resources. A governance system that demands a separate fully trained model for every ethical tradition would therefore risk increasing market concentration by making compliance affordable only for the largest providers.
An efficient architecture should prioritise reusable technical components and common evaluation methods. Standardised policy documentation, modular retrieval systems, shared testing protocols and clear separation between global safeguards and local configuration can reduce duplication. Public investment may be justified where market incentives underprovide culturally specific evaluation resources, particularly for languages and communities that lack extensive commercial demand. Such support should not require communities to surrender control over knowledge that is not intended for unrestricted distribution.
The same economic logic supports the development of procurement standards that focus on observable performance and institutional accountability rather than mandating a particular proprietary alignment technique. Governments can require that a system demonstrate lawful and context-appropriate behaviour without dictating whether the provider uses fine-tuning, retrieval, classifiers or another technically suitable mechanism. This preserves innovation while maintaining responsibility for outcomes.
Key judgments
Technical pluralism is achievable in bounded forms, particularly through configurable explanation, contextual retrieval, institutionally authorised policies and independent evaluation. It is not equivalent to unlimited user control over safety constraints or guaranteed isolation of moral principles inside neural parameters. Effective implementation requires an explicit separation of authority levels, validated configuration procedures and ongoing behavioural verification.
The strongest architecture is one in which legally binding protections remain stable while legitimate ethical preferences can be expressed, explored and accommodated without automatically becoming universal model requirements.
What would change the assessment
The assessment would change if independent research demonstrated reliable separation of normative configurations across diverse models and deployment environments, with predictable reversibility and minimal unintended effects. Evidence of persistent cross-profile contamination, widespread cultural stereotyping or ineffective enforcement of common protections would strengthen concerns about unrestricted personalisation.
Open official record
The most important technical gaps concern reproducible cross-cultural benchmarks, controlled studies of alignment reversibility, evidence of robust configuration isolation, the security of policy-routing mechanisms and the economic burden of maintaining independently validated specialised configurations.
Chapter 12. Strategic Scenarios to 2031: Corporate Convergence, Regulatory Fragmentation, Democratic Oversight and Cognitive Dependency
Principal judgment: The governance of moral instruction in frontier AI is likely to be shaped by the interaction of commercial concentration, regulatory differentiation, technical configurability and the development of independent public oversight. Four strategically relevant pathways can be identified through 2031, but the available evidence does not support defensible numerical probabilities for their occurrence. These pathways are not mutually exclusive: corporate convergence may coexist with jurisdiction-specific restrictions, while democratic oversight may develop in selected public-sector applications without becoming universal. The decisive strategic variable is the degree to which institutions outside frontier laboratories obtain the practical ability to inspect, contest and alter consequential model behaviour.
The forecasting problem and the limits of present evidence
A five-year assessment must distinguish between observed developments and projections concerning institutional behaviour. The public record establishes that frontier laboratories publish behavioural frameworks, experiment with external participation, train models using normative principles and operate within increasingly developed regulatory environments. It also establishes that governments and technical institutions are building evaluation capabilities. These developments do not provide a sufficient statistical foundation to calculate the probability that one particular global governance arrangement will dominate in 2031. The relevant future outcomes depend on political decisions, market structure, model capability, technical breakthroughs, litigation, public procurement and regulatory enforcement, many of which cannot be assigned reliable probability distributions from the evidence currently available.
The appropriate approach is therefore conditional scenario analysis. Each pathway should be associated with a causal mechanism, observable indicators, countervailing forces and decisions available to public authorities. The scenarios are designed to illuminate strategic dependencies rather than to predict one inevitable future. Their value lies in identifying which institutional choices could strengthen or weaken cognitive autonomy under different conditions.
Scenario A — Corporate convergence and privately governed moral defaults
Under the first pathway, a limited group of internationally important providers continues to exercise substantial control over the behavioural frameworks of widely used frontier models. Their constitutions, specifications and safety policies become more detailed, while external consultation and technical evaluation expand. Large enterprise customers, application developers and regulators influence particular restrictions, but the underlying normative architecture remains principally provider-directed. Competition among laboratories may produce improvements in transparency and user choice, yet the need for broad consistency and manageable compliance costs encourages the adoption of common behavioural patterns.
The causal mechanism is economic as well as technical. Developing frontier systems requires substantial resources, and organisations that distribute their models through widely adopted platforms can obtain repeated feedback and invest in increasingly sophisticated evaluation. Downstream organisations may find it easier to accept a provider’s existing behavioural defaults than to maintain specialised alternatives. The result could be a gradual convergence around a limited number of commercially viable interpretations of appropriate AI conduct, even without explicit agreement among competitors.
This scenario would not necessarily produce a single ideological framework. Different laboratories may retain distinguishable policies, and governments may impose local legal requirements. The more important concern is the possibility that a relatively narrow set of private institutions determines the available range of normative configurations. Users could choose among products while remaining dependent on similar underlying approaches to acceptable advice, professional caution, controversial expression and institutional authority.
A countervailing force is the availability of competitive models and alternative deployment architectures. Open-weight models, specialised systems, local providers and robust portability arrangements could weaken dependence on a small set of proprietary services. Another is regulatory intervention, where competent authorities require greater transparency or restrict particular practices. The scenario becomes more concerning if providers consolidate distribution, maintain opaque policy revisions and discourage independent testing.
Scenario B — Regulatory fragmentation and competing jurisdictional defaults
Under the second pathway, governments increasingly require model behaviour to comply with differentiated national or regional expectations, producing more extensive jurisdiction-specific configurations. Some differences will arise from legitimate legal requirements concerning privacy, discrimination, professional services and public administration. Others may reflect political efforts to control lawful expression, suppress dissent or enforce contested cultural preferences. Providers would face pressure to reconcile incompatible obligations while maintaining commercially viable cross-border services.
The mechanism is especially relevant because general-purpose AI systems distribute information across borders while public law remains organised around territorial jurisdictions and specific legal competences. A provider may be required to apply one set of restrictions in a particular market while another jurisdiction protects the same content or activity. Where the differences concern ordinary consumer information, separate deployment configurations may be technically manageable. Where they concern fundamental rights, political criticism or religious liberty, fragmentation can create more serious conflicts.
The July 2026 amendment of the EU AI Act provides a concrete example of why regulatory trajectories must be assessed through precise legal developments rather than general assumptions about harmonisation. The European framework continues to evolve, with differentiated obligations and revised application dates that affect providers and deployers. China maintains an expressly state-directed regulatory approach to public generative AI services, while the United Kingdom’s governance structure differs from that of the Union. These documented institutional differences provide a basis for considering regulatory fragmentation, although they do not establish its eventual magnitude. Regulation (EU) 2026/1744 — European Parliament and Council — July 2026. Interim Measures for the Management of Generative Artificial Intelligence Services — Cyberspace Administration of China and Six Other Authorities — July 2023.
The principal danger would be the conversion of AI governance into a mechanism of automated ideological partition. If models are required to reproduce different political accounts according to jurisdiction, users may encounter structurally different informational environments even when asking equivalent questions. That risk should not be confused with legitimate adaptation to local law or language. The relevant test is whether differences protect lawful public interests or unnecessarily restrict the ability to receive accurate information and consider competing views.
A countervailing force would be the development of internationally compatible human-rights and audit principles. Such coordination cannot eliminate all differences in national law, but it can help distinguish permissible local requirements from restrictions that undermine fundamental protections.
Scenario C — Democratic oversight and accountable ethical pluralism
The third pathway involves the gradual development of institutions capable of subjecting material alignment decisions to independent review without imposing a universal official morality. Public authorities would strengthen documentation requirements and evaluation capacity, while public purchasers would demand clearer behavioural specifications and effective remedies. External consultation would become more procedurally accountable, with documented participant selection, disclosed dissent and reasoned responses to consequential recommendations. Technical systems would support bounded configuration so that lawful differences in philosophical or cultural preference could be accommodated without overriding fundamental protections.
This scenario does not require replacing private laboratories with public developers. It requires separating operational responsibility from independent review and ensuring that decisions with public consequences are subject to appropriate institutional constraints. Providers would continue to make many product and engineering choices, but material restrictions would become more visible and contestable. Regulators would act within defined legal powers, while independent auditors would assess claims that cannot be validated through company declarations alone.
The feasibility of this pathway is supported by existing institutional foundations rather than by evidence of a completed system. The Council of Europe Convention provides an international rights-based framework; the EU AI Act creates defined supervisory and documentation mechanisms; NIST offers risk-management methodology; and specialised government evaluation bodies demonstrate the possibility of technical assessments external to model providers. These are complementary resources, not proof that democratic control over model morality has already been achieved. Framework Convention on Artificial Intelligence — Council of Europe — September 2024. Generative AI Profile — NIST — July 2024. Frontier AI Trends Report — UK AI Security Institute.
The main implementation obstacle is institutional capacity. Effective audits require specialised technical and cultural expertise, while regulators need legally appropriate access to information and procedures for acting on findings. Providers may resist costly or intrusive requirements, and excessive regulation could favour larger companies capable of maintaining substantial compliance organisations. A proportionate governance model must therefore distinguish high-impact obligations from lower-risk applications and avoid unnecessary duplication.
Scenario D — Cognitive dependency and the erosion of independent deliberation
The fourth pathway concerns a more indirect risk: sustained dependence on AI-mediated explanations and recommendations may alter how individuals and institutions encounter contested questions. This scenario does not assume that users uncritically accept every model output or that AI systems exert uniform psychological effects. The relevant mechanism is the repeated presentation of certain normative assumptions through convenient and authoritative-seeming interfaces, potentially reducing the visibility of alternatives when users lack independent sources or professional support.
Cognitive dependency may arise in several forms. Individuals may rely increasingly on assistants to frame personal decisions. Professionals may incorporate generated recommendations into routine workflows. Public institutions may use models to explain rights or evaluate cases, giving provider-defined output patterns indirect institutional significance. Educational users may encounter a limited range of interpretations if models consistently foreground similar assumptions. In each setting, the consequence depends on the quality of alternative information, human review and the user’s ability to challenge or contextualise the model’s output.
The risk is not demonstrated simply by growing AI adoption. Establishing cognitive dependency would require longitudinal evidence concerning user behaviour, institutional reliance, changes in independent judgment and the influence of model framing relative to other sources. Current structural analysis can identify plausible mechanisms, but cannot responsibly quantify their social effect without appropriate research.
The strongest countermeasure is not indiscriminate restriction of AI assistance. It is the preservation of meaningful human judgment through transparent provenance, alternative perspectives, professional accountability, educational competence and the ability to use different providers or sources. In this sense, cognitive sovereignty is a property of the surrounding institutional environment as much as of the model itself.
Comparative scenario matrix
| Strategic pathway | Driving mechanism | Observable indicators | Principal governance risk | Countervailing force |
|---|---|---|---|---|
| Corporate convergence | Concentration of development and distribution | Similar default policies, opaque revisions, dependence on dominant providers | Private normative standardisation | Competition, portability and independent oversight |
| Regulatory fragmentation | Divergent national legal and political requirements | Jurisdiction-specific restrictions and conflicting compliance demands | Politically partitioned information environments | Rights-based international coordination |
| Accountable pluralism | Enforceable oversight and bounded configuration | Independent audits, effective complaints and documented corrections | Administrative burden and procedural capture | Proportionate regulation and common standards |
| Cognitive dependency | Repeated reliance on model-mediated judgment | Institutional reliance, persistent framing and reduced independent verification | Erosion of deliberative autonomy | Education, human oversight and alternative information sources |
These pathways should not be assigned arbitrary probabilities or combined into a numerical distribution. Their purpose is to identify causal relationships and strategic decisions under uncertainty.
Watch indicators and collection priorities through 2031
A useful monitoring framework should prioritise observations that distinguish among the scenarios rather than merely counting announcements of ethical initiatives. The number of philosophers consulted or constitutional pages published may indicate institutional activity, but it does not establish accountability. More diagnostic indicators include whether external recommendations produce verifiable changes, whether independent auditors can detect systematic normative failures, whether affected individuals obtain corrections and whether public institutions can change providers without losing essential functionality.
| Indicator | Evidence to collect | Interpretation if observed | Principal uncertainty |
|---|---|---|---|
| Binding external review | Publicly defined decision rights and documented exercises of authority | Movement toward distributed accountability | Whether review is effective in practice |
| Material policy change records | Versioned constitutions and implementation documentation | Greater traceability | Whether disclosed changes explain actual outputs |
| Independent audit access | Agreements, statutory powers and completed assessments | Stronger external scrutiny | Technical adequacy of audit methods |
| Successful contestation | Complaint outcomes and verified corrections | Effective procedural accountability | Representativeness of reported cases |
| Cross-border divergence | Equivalent tests across jurisdictions | Regulatory or cultural differentiation | Whether differences are intentional or incidental |
| Model portability | Procurement records and successful migrations | Reduced dependency | Functional equivalence of alternatives |
| Cross-cultural evaluation | Reproducible multilingual studies | Better understanding of normative asymmetry | Validity of cultural reference judgments |
| Government-imposed political restrictions | Official regulations and enforcement records | Increased state control over model behaviour | Actual implementation across services |
| Institutional reliance | Public procurement and deployment documentation | Potential expansion of cognitive exposure | Relationship between use and decision autonomy |
Strategic assessment of the 2031 horizon
The most defensible conclusion is not that one pathway will necessarily dominate by 2031, but that the distribution of normative authority will increasingly depend on the interaction of infrastructure concentration and institutional oversight. Technical advances may improve a provider’s ability to implement sophisticated ethical behaviour, but they do not automatically confer legitimacy on the principles chosen. Greater public participation may improve representation, but it does not establish enforceable authority unless incorporated into decision procedures. More extensive regulation may protect rights, but it may also create fragmentation or political control if drafted without appropriate constitutional safeguards.
For governments, the operational priority is therefore to preserve strategic options under all four pathways. Public institutions should maintain the capacity to evaluate models independently, enforce applicable law, require accountability from providers and avoid irreversible procurement dependence. They should also resist treating national technological sovereignty as sufficient evidence of pluralism or treating voluntary corporate consultation as a substitute for legitimate public authority.
Key judgments
The period to 2031 is best understood as a contest over institutional control of AI-mediated decision environments rather than simply a competition among model architectures. The most important indicators are enforceable review rights, actual correction outcomes, technical portability and the preservation of independent human deliberation.
No numerical scenario probability is warranted by the present evidence. The appropriate strategic response is to build institutions that remain useful under several plausible futures.
What would change the assessment
Major changes in the ownership or distribution of frontier models, new binding international governance mechanisms, independently verified improvements in configurable alignment or judicial decisions establishing broad rights concerning AI-mediated expression would materially alter the outlook.
Open official record
The principal gaps concern longitudinal user-reliance studies, the costs of switching providers, comparable national evaluation results, records of public-sector normative failures and evidence linking specific alignment policies to measurable changes in deliberation or institutional outcomes.
Chapter 13. Government Courses of Action, Implementation Priorities and Final Strategic Assessment
Principal judgment: Governments should neither delegate the moral governance of widely deployed AI entirely to private laboratories nor attempt to impose a comprehensive official ethical doctrine through regulation. The most defensible policy is to establish an enforceable architecture of bounded normative discretion: providers remain responsible for developing safe and useful systems, while competent public institutions define applicable legal protections, require proportionate transparency, verify consequential behaviour and preserve meaningful opportunities for correction. The strategic objective is to prevent the concentration of technical control from becoming unaccountable authority over legitimate human disagreement.
Translating institutional principles into government action
The central challenge for public authorities is implementation. General commitments to fairness, pluralism, transparency and human dignity do not automatically create operational capacity to supervise frontier-model behaviour. A government may possess substantial statutory powers while lacking the technical expertise necessary to determine whether a refusal originates in a model’s training, an application instruction, an external classifier or a deployment-specific policy. Conversely, a specialised research institution may possess sophisticated evaluation methods but no legal authority to compel changes. The effectiveness of governance therefore depends on connecting legal competence, technical evidence and enforceable institutional procedures.
The first implementation principle is to avoid creating a universal regulatory category called moral misalignment without defining its legal consequences. Such a category could become a vehicle for political pressure, doctrinal disputes or excessive state intervention in legitimate expression. Instead, public authorities should classify governance problems according to existing legal responsibilities and identifiable risks. Unlawful discrimination, privacy violations, failures in consequential administrative decision-making and prohibited manipulative practices require legally grounded responses. Inaccurate cultural representation, excessive caution in lawful conversations and insufficient recognition of ethical disagreement may call for different mechanisms involving transparency, audit, service standards or user choice.
The second principle is to preserve responsibility at the level where a decision can actually be controlled. A foundation-model provider should not be held automatically responsible for every unauthorised instruction introduced by a downstream application, while a public administration should not avoid its legal duties merely because it relies on an external AI service. Responsibility must reflect the relevant provider, deployer and user roles, including their practical capacity to prevent or correct the disputed conduct.
The third principle is to require proof of implementation rather than accepting normative declarations as sufficient evidence. A provider may publish an extensive commitment to user autonomy, but the relevant question for a public purchaser is whether the deployed model respects lawful user choices under realistic conditions. A government may demand respect for religious diversity, but the relevant question is whether the system accurately represents different traditions without privileging one institution’s doctrine or undermining binding legal rights. An independent audit may report satisfactory performance, but its significance depends on sampling, reference standards, testing conditions and the independence of the evaluators.
Course of action I — Establish a legally classified register of material alignment policies
The first recommended intervention is the creation of a structured disclosure requirement for material behavioural policies used in consequential deployments. Its purpose would be to establish which restrictions are legally required, which arise from demonstrated safety concerns and which reflect discretionary provider or deployer choices. The register should identify relevant policy versions, responsible institutions, dates of material changes and procedures for challenge. It should not require publication of information whose disclosure would create disproportionate security, privacy or intellectual-property risks.
The competent authority would depend on jurisdiction and deployment. In the European Union, existing AI Act powers provide a foundation for certain documentation and supervisory obligations, but any broader mandatory disclosure regime would need to remain within operative statutory authority or be established through additional legislation. Public purchasers can introduce appropriate contractual requirements where compatible with procurement law. The expected effect would be to reduce uncertainty about the origin and authority of normative restrictions, making it easier for regulators, auditors and affected institutions to distinguish legal compliance from discretionary policy.
Implementation should begin with high-impact institutional deployments rather than attempting immediate universal application. Public administration, regulated professional services and applications affecting legally protected interests provide clearer grounds for enhanced documentation. Expansion to general consumer applications should follow demonstrated need and proportionality.
The intervention is relatively reversible at the administrative level because documentation templates and reporting scopes can be revised. Its main risks are excessive reporting costs, superficial compliance and disclosure of sensitive information without sufficient public benefit. These risks can be reduced through standardised reporting categories and differentiated access.
Course of action II — Develop independent normative-behaviour evaluation capacity
The second intervention is the establishment or expansion of independent evaluation programmes capable of testing model behaviour across legally and culturally significant contexts. This does not require creating a government agency responsible for deciding the correct philosophical answer to every question. It requires technical and multidisciplinary competence to determine whether models comply with applicable obligations, accurately represent competing positions, recognise relevant uncertainty and apply restrictions consistently.
The institutional model should combine technical researchers, legal specialists, professional experts, linguists and appropriately selected representatives of affected communities. Test cases should be designed for specific purposes and evaluated against transparent criteria. A benchmark examining religious attribution should not be described as a comprehensive measure of democratic legitimacy, while a safety benchmark measuring resistance to harmful instructions should not be interpreted as proof of cultural pluralism.
Existing government evaluation programmes demonstrate the feasibility of sustained independent technical testing. The UK AI Security Institute’s work provides a particularly relevant institutional example, although its published frontier capability evaluations are not themselves a comprehensive moral-behaviour audit framework. Likewise, NIST’s generative-AI risk-management profile provides organisational methods that can support structured assessment without functioning as a binding certification of ethical correctness. Frontier AI Trends Report — UK AI Security Institute. Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile — NIST — July 2024.
The expected effect would be to reduce reliance on provider-reported evaluations and improve the evidentiary basis for regulatory decisions, procurement and public communication. The principal burden would be sustained funding for qualified personnel, secure testing infrastructure and methodological development. The main risk is that evaluation metrics become politically contested or are treated as definitive measures of moral correctness. This requires clear separation between legal compliance tests, factual accuracy assessments and evaluations of legitimate ethical pluralism.
Course of action III — Create proportionate rights of contestation
The third intervention concerns the procedural position of affected individuals and communities. A complaint system should provide a practical means to report material normative failures and obtain an appropriate response. Its scope must be graduated according to the consequences of the alleged failure. Ordinary dissatisfaction with an answer should not automatically trigger a formal administrative proceeding, but systematic discriminatory behaviour or a model-supported decision affecting legal rights may require independent review and a legally available remedy.
The Council of Europe’s AI Convention supplies an important conceptual foundation through its provisions concerning documentation, remedies and procedural safeguards. The European AI Act provides more specific mechanisms in defined contexts, including provisions addressing fundamental-rights assessments and explanations of certain consequential decisions. The challenge is to make these protections usable without misrepresenting their scope. Framework Convention on Artificial Intelligence — Council of Europe — September 2024. Article 86 — Right to Explanation — European Commission AI Act Service Desk — Consolidated July 2026.
An effective complaints architecture should identify the responsible provider or deployer, permit evidence submission, establish proportionate response procedures and provide escalation where an applicable legal right is implicated. In cases of systematic cultural misrepresentation, the appropriate remedy may be correction of source attribution or modification of evaluation criteria rather than adjudication of theological truth. In cases involving public decisions, the remedy may require review by the competent authority rather than merely modifying the chatbot’s next answer.
The expected benefit is a stronger connection between observed harm and institutional accountability. The primary risks are procedural overload, strategic abuse of complaint systems and the potential for organised campaigns to demand suppression of lawful opposing views. These risks require clearly defined admissibility criteria, protection for legitimate disagreement and independent review where appropriate.
Course of action IV — Use public procurement to preserve normative autonomy
The fourth intervention is the incorporation of behavioural accountability into public procurement. Governments should require sufficient documentation to understand the policies governing systems used in public functions, together with defined procedures for evaluation, incident response and material changes. Procurement should also preserve the ability to replace providers or reconfigure systems when legally necessary.
This measure has particular strategic significance because procurement is a direct area of governmental competence even where broader regulatory authority is limited. A public authority purchasing an AI system can specify performance requirements and contractual responsibilities related to its lawful function. Such conditions should be proportionate to the intended use and should not become a means of imposing partisan or religious orthodoxy on public-service users.
Technical portability is essential. If a public administration has invested heavily in applications that depend on proprietary interfaces or undocumented model behaviour, switching providers may become costly even when serious governance concerns arise. Modular architecture, data portability, reproducible evaluation and contractual exit procedures can reduce this dependency. However, switching models may still require extensive validation because nominally comparable systems can behave differently under the same instructions.
The expected effect is improved institutional bargaining power and continuity of public accountability. The principal burden is the need to develop technical procurement competence and maintain alternatives. The main risk is excessive fragmentation or procurement rules that unnecessarily exclude smaller providers. Common specifications and reusable evaluation tools can reduce these costs.
Course of action V — Protect pluralism without creating an official morality
The fifth intervention addresses the most politically sensitive dimension of the dossier. Governments should establish principles for preserving lawful ethical pluralism in AI-mediated services, particularly where public institutions are responsible for the deployment. These principles should recognise the distinction between presenting a viewpoint, endorsing it, acting upon it and imposing it on another person. A model can explain religious doctrines without requiring users to accept them. It can describe secular ethical positions without presenting religious commitments as inherently illegitimate. It can support personal autonomy while recognising voluntary family or community obligations. It can identify applicable law without claiming that every legal rule settles the underlying philosophical controversy.
The appropriate form of pluralism is therefore bounded rather than absolute. It should operate within fundamental rights, legally required protections and proportionate safety constraints. User-configurable explanation and perspective selection may be valuable, but they should not permit discriminatory treatment of third parties, coercive manipulation or circumvention of essential protections. In public administration, the relevant institutional requirement is especially strong: government systems must distinguish official legal authority from private philosophical or religious interpretation.
This course of action would require guidance, procurement specifications, independent evaluation and appropriate participation by communities with relevant expertise. Its implementation burden would be significant where national institutions lack culturally competent testing resources. The principal risk is that pluralism becomes a rhetorical justification for allowing discriminatory or unsafe configurations. Clear legal boundaries and independent review are therefore indispensable.
Comparative government action matrix
| Course of action | Competent authority | Expected effect | Implementation burden | Indicative policy-development horizon | Reversibility | Principal downside |
|---|---|---|---|---|---|---|
| Material alignment register | Legislators, competent regulators and public purchasers | Greater traceability of normative decisions | Medium; documentation standards and protected access | 6–18 months for pilot design, subject to legal authority | High for templates; lower for established duties | Compliance burden and superficial disclosure |
| Independent normative audits | Public evaluation bodies and authorised independent institutions | Better evidence of actual model behaviour | High; expertise, infrastructure and methodology | 12–24 months for a credible initial programme | High for methods; institutional investment persists | Politicised metrics or inadequate reference standards |
| Effective contestation procedures | Providers, deployers, regulators and courts according to competence | Stronger accountability for significant failures | Medium to high depending on jurisdiction | 6–24 months for targeted implementation | Moderate; procedural rights can create durable obligations | Frivolous or coordinated complaints |
| Normative procurement safeguards | Public procurement authorities | Reduced dependence and clearer deployment responsibility | Medium; legal and technical procurement capacity | 6–18 months for new procurement cycles | Moderate; existing contracts can limit change | Higher costs and procurement fragmentation |
| Bounded plural configurations | Providers and authorised deployers | Greater lawful user and institutional autonomy | High for robust technical validation | 12–36 months for mature specialised deployments | Variable according to implementation layer | Unsafe configuration or hidden discrimination |
| Cross-border evaluation cooperation | National regulators and international technical institutions | Comparable evidence and reduced duplication | Medium to high; coordination and common methods | 18–36 months for sustained arrangements | Moderate | Lowest-common-denominator standards |
| Longitudinal cognitive-autonomy research | Universities, research funders and public institutions | Evidence on downstream social effects | High; longitudinal design and privacy safeguards | Multi-year | Research can be revised; historical gaps cannot easily be recovered | Weak causal attribution and intrusive data collection |
The time horizons in this matrix are proposed planning assumptions, not verified implementation schedules or forecasts derived from official programmes. They indicate the order of magnitude of institutional work likely to be involved and must be adapted to national resources, legislative procedures and existing organisational capacity.
A phased implementation strategy for 2026–2031
A rational sequence begins with the identification of existing authority and capability. Governments should map which institutions already possess powers to require information, investigate legally consequential AI conduct and impose corrective measures. They should then identify whether these bodies have sufficient technical competence to evaluate model behaviour. Where capabilities are missing, targeted investment in assessment infrastructure is likely to be more effective than creating new advisory bodies whose findings cannot be enforced.
The initial phase should focus on public-sector and other high-consequence deployments, where responsible institutions and legal obligations are comparatively identifiable. Public purchasers can introduce behavioural documentation requirements, establish baseline evaluations and ensure that consequential decisions retain appropriate human review. Regulators can clarify complaint routes within their existing mandates. Independent research bodies can develop methodologies for testing cross-language consistency and the accurate presentation of contested ethical viewpoints.
A second phase should concentrate on institutional interoperability. Different national authorities should be able to exchange relevant evaluation methods and compare evidence without assuming that all legal frameworks are identical. A model that performs differently in Italian, French, German and English should be examined through a method capable of distinguishing translation errors, contextual variation and deliberate policy restrictions. Shared methodologies could reduce duplication and improve the quality of public evidence.
The later phase should address more demanding questions concerning model configurability, portability and the possibility of persistent normative effects on users. These issues require longitudinal research and technical experimentation rather than premature legislative certainty. A government can establish legal rights and procurement requirements in the near term, but cannot responsibly claim to have measured the long-term effect of AI moral defaults on democratic deliberation without adequate empirical observation.
Priority allocation by institutional level
| Institutional level | Primary responsibility | Immediate priority | Medium-term objective | Strategic limit |
|---|---|---|---|---|
| National legislatures | Define legal duties and remedies | Clarify existing authority and gaps | Proportionate additional safeguards where justified | Must respect constitutional freedoms |
| AI regulators | Supervise compliance within statutory powers | Secure technical evaluation capability | Enforceable evidence-based oversight | Cannot determine all philosophical disputes |
| Data-protection authorities | Apply privacy and data-protection law | Examine relevant personal-data practices | Coordinate where normative behaviour implicates personal data | Privacy competence is not universal moral jurisdiction |
| Public procurement bodies | Specify contractual requirements | Require behavioural documentation | Portability and independent testing | Contractual power depends on procurement scope |
| Universities and research institutions | Develop independent knowledge | Create valid evaluation methods | Longitudinal and cross-cultural evidence | Research findings do not confer legal authority |
| Providers and deployers | Implement and operate systems responsibly | Document policies and known limitations | Reliable correction and version control | Corporate discretion requires external constraints |
| Civil society and affected communities | Identify harms and represent legitimate interests | Participate in structured review | Effective channels for contestation | Representation claims must remain accountable |
| International organisations | Support cooperation and common principles | Clarify compatible governance approaches | Reduce unnecessary fragmentation | Most instruments require implementation through competent authorities |
This allocation preserves the distinction between legal power, technical knowledge and democratic participation. It avoids treating consultation as a substitute for enforcement while recognising that technically sophisticated regulation may still fail if affected communities cannot identify problems or communicate their consequences.
Residual risks that governance cannot eliminate
Even a well-designed framework will not eliminate every problem associated with moral instruction. Neural models remain imperfectly interpretable, and a specific response may reflect numerous interacting influences rather than a single identifiable rule. Independent evaluations can detect patterns but cannot exhaustively test every possible context. Public consultation can improve representation but cannot produce universal agreement. Legal frameworks can establish enforceable rights but may lag behind technological changes or generate conflicting obligations across jurisdictions.
The possibility of regulatory capture also remains. Large providers may possess greater resources to influence standards, participate in consultations and satisfy complex compliance requirements than smaller competitors. A disclosure regime that imposes substantial costs without improving independent scrutiny could unintentionally strengthen market concentration. An audit industry may develop incentives to produce easily measurable certifications rather than investigate difficult contextual questions. Public institutions may themselves become politically selective in the issues they investigate.
A further risk concerns the misuse of user configuration. Systems designed to preserve ethical choice could be exploited by organisations seeking to manipulate users, impose discriminatory policies or shield harmful practices behind claims of cultural difference. This requires technical controls and clear legal boundaries, but those protections must remain proportionate to the actual risk. Excessive constraints can produce the opposite problem, in which lawful differences in belief become practically inaccessible through widely used systems.
Finally, cognitive autonomy cannot be guaranteed by model design alone. Individuals and institutions require education, independent sources, professional competence and opportunities for deliberation outside AI-mediated environments. A model may be transparent and configurable while users continue to rely on it excessively. Conversely, a model with relatively fixed defaults may be used responsibly within an institution that maintains strong human review and alternative information sources. The surrounding social environment remains decisive.
Final Net Assessment — Who Should Hold the Threads of Moral Instruction?
The governing conclusion of this dossier is that frontier AI has created a new category of institutional responsibility without creating a new source of legitimate moral sovereignty. AI systems can represent complex ethical traditions, generate arguments and provide context-sensitive recommendations, but their apparent moral reasoning does not establish an independent right to govern human values. The priorities they express are shaped through human institutions, technical optimisation and deployment policies. The question of who authorises those priorities is therefore inseparable from the distribution of technological power.
The public record demonstrates that leading laboratories have recognised the need for broader intellectual and societal participation in alignment. Constitutional documents, public-input experiments and ethical consultation show that moral governance is increasingly treated as an explicit design problem rather than an incidental consequence of training. These developments should not be dismissed as inherently superficial. They can improve clarity, expose neglected perspectives and produce measurable changes in behaviour. Yet their legitimacy cannot be inferred solely from the sincerity of the participants or the sophistication of the resulting policies. The decisive test is whether consequential normative decisions can be inspected, challenged and corrected by institutions with appropriate authority and independence.
Neither private concentration nor state monopoly provides a satisfactory answer. Corporate laboratories possess the engineering resources necessary to implement complex alignment policies, but their commercial and organisational authority does not confer a democratic mandate to resolve every contested ethical question for global users. Governments possess legitimate powers to protect rights and regulate harmful conduct, but those powers are limited by constitutional freedoms and cannot justify unrestricted political control over information or conscience. Religious and philosophical experts possess valuable knowledge, but expertise alone does not confer authority to impose doctrine on people who do not share it. Public participation can reveal preferences and improve legitimacy, but numerical aggregation cannot settle questions involving fundamental rights or irreducible moral disagreement.
The strategic alternative is institutionally constrained normative pluralism. Within legally defined protections, frontier AI should support the ability of people and institutions to examine competing ethical positions, make informed decisions and challenge inaccurate or unjustified restrictions. Providers should remain accountable for technical implementation, while public authorities should require proportionate documentation, competent evaluation and legally appropriate remedies. External experts should contribute knowledge under transparent mandates, and affected communities should possess meaningful opportunities to identify and contest systematic failures. The resulting system would not eliminate moral disagreement; it would prevent that disagreement from being silently resolved through unaccountable technical defaults.
For democratic governments, the objective to 2031 should be to ensure that growing dependence on advanced AI does not become dependence on a narrow and inaccessible system of normative decision-making. This requires investments in independent technical capacity, procurement autonomy, cross-border cooperation and the legal institutions capable of protecting fundamental rights. It also requires restraint: governments must avoid treating cultural sovereignty as a justification for suppressing pluralism or treating every disagreement with an AI response as a matter requiring state intervention.
The highest-confidence finding is institutional rather than predictive. The development of frontier AI makes the concentration of normative discretion technically possible and operationally consequential. The extent of its long-term influence on individual beliefs, social cohesion and democratic deliberation remains insufficiently measured. The appropriate public response is therefore neither to assume catastrophic ideological capture nor to accept provider assurances as sufficient. It is to establish the capacity to observe what systems do, determine who authorised consequential behaviour, and require correction where legitimate standards have been violated.
The central strategic question can consequently be answered with precision. The threads of moral instruction should not be held exclusively by laboratories, governments, religious authorities or statistical majorities. They should be governed through a differentiated institutional order in which legal rights establish binding boundaries, technical organisations retain accountable implementation duties, independent institutions verify consequential behaviour and individuals preserve meaningful freedom of conscience and judgment.
That arrangement would not give artificial intelligence a morality of its own. It would establish legitimate human governance over the moral consequences of the systems human institutions create.


